 IEEE/ICACT20250006 Slide.03
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250006 Slide.03
[Big Slide]
| Oral Presentation |
|
|
|
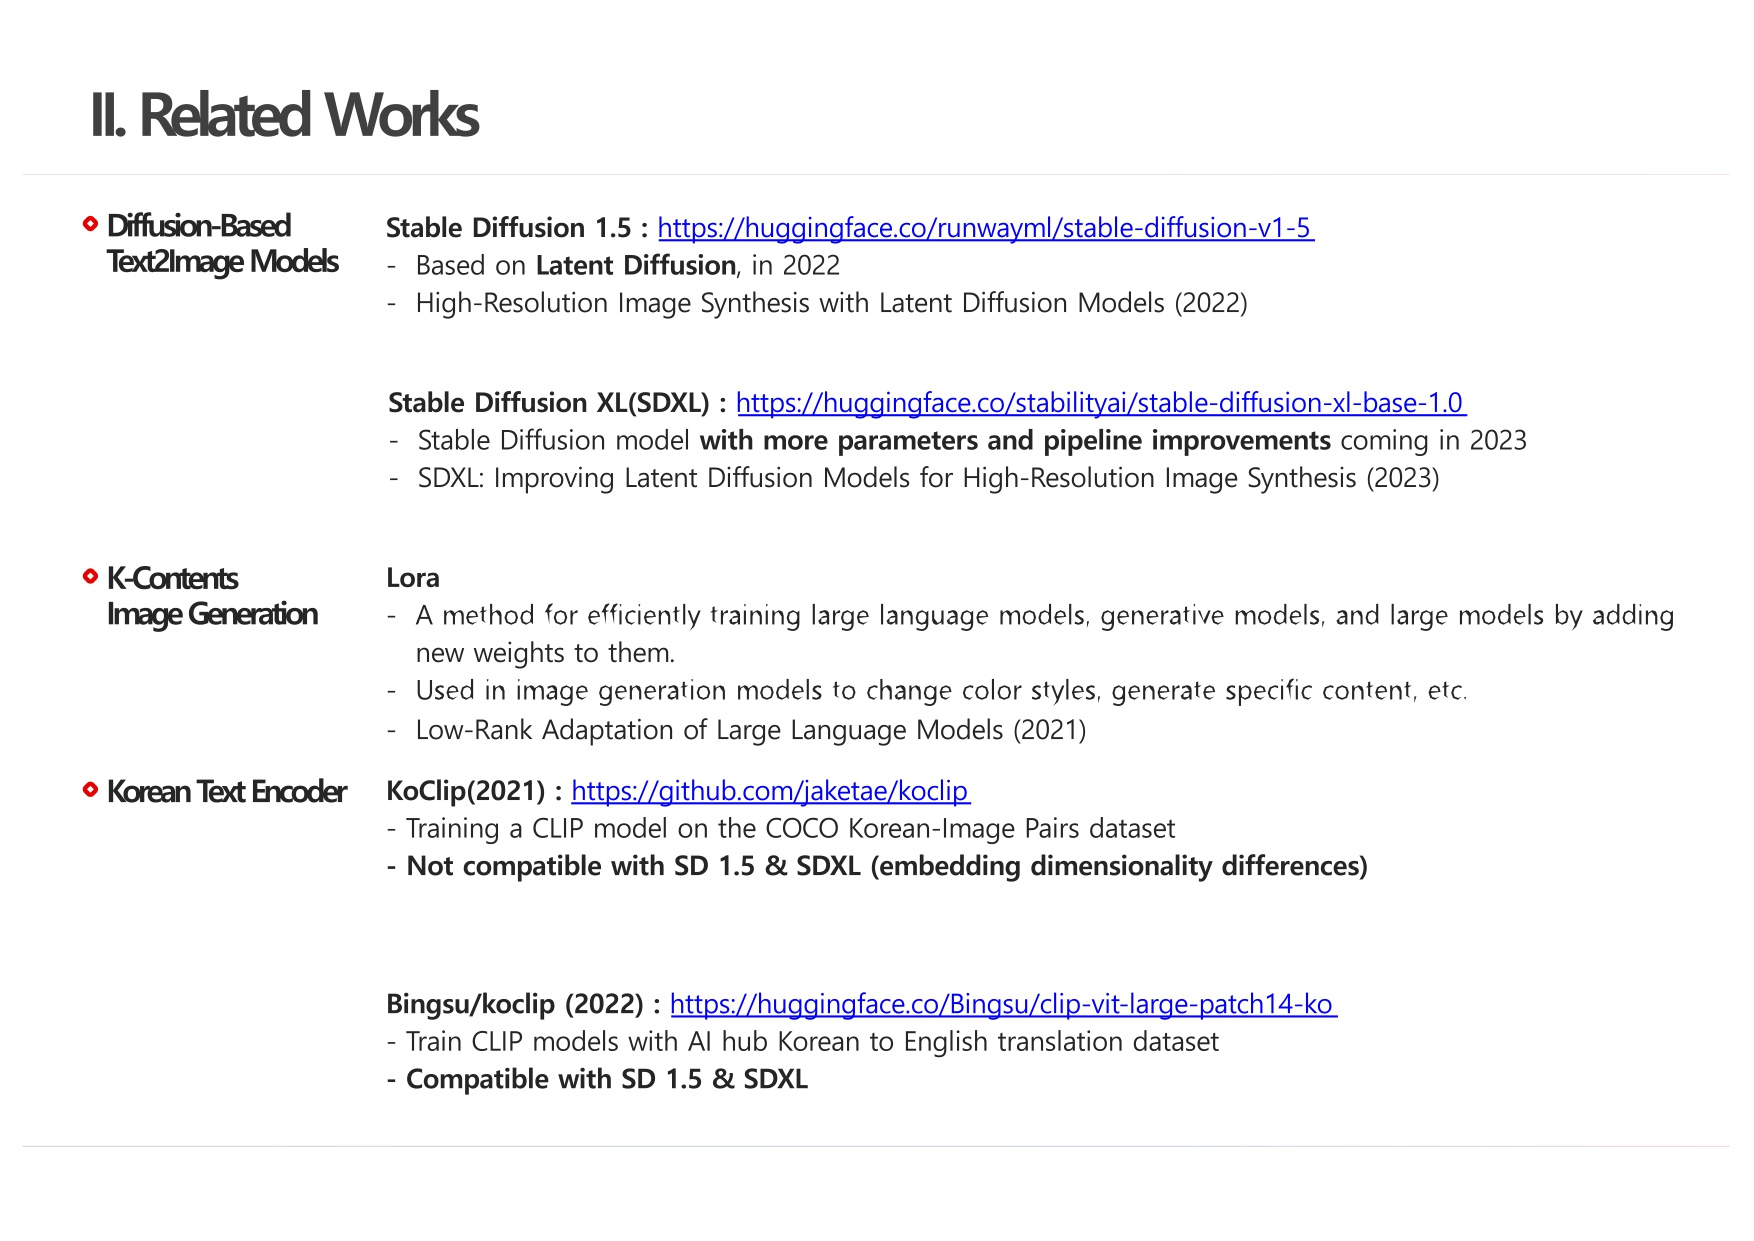
There has been some related research. Diffusion-Based Text to Image Model had SD1.5, SDXL, etc. For K-Contents Image Generation, there was a Low Rank Adaptation method that trained only some parameters. For learning Korean Text Encoder, there were Koclip on github, bingsu/koclip on huggingface. | |
| [Go to Next Slide] |