 |
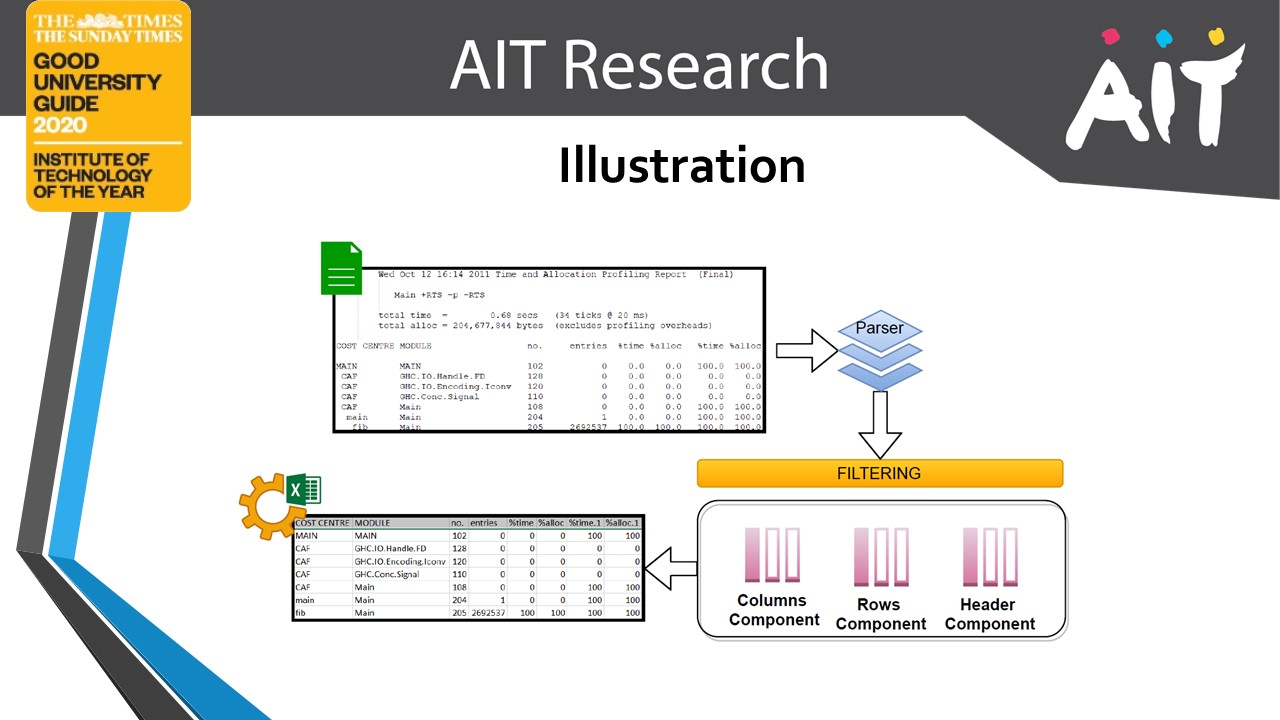
A simple illustration of our unstructured data parsing is shown in this figure. A text file is used as an input to the parser; the next step is identifying useful information from the text that can be used for exploratory data analysis. We remove information such as timestamp, metadata, and any information that is not useful. The filtered file is then analyzed to identify different tabular components such as header rows, data rows, and columns. The analyzed file is then parsed into a structured format and can be used for various machine learning applications. |
 IEEE/ICACT20210237 Slide.04
[Big Slide]
[YouTube]