 IEEE/ICACT20250006 Slide.04
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250006 Slide.04
[Big Slide]
| Oral Presentation |
|
|
|
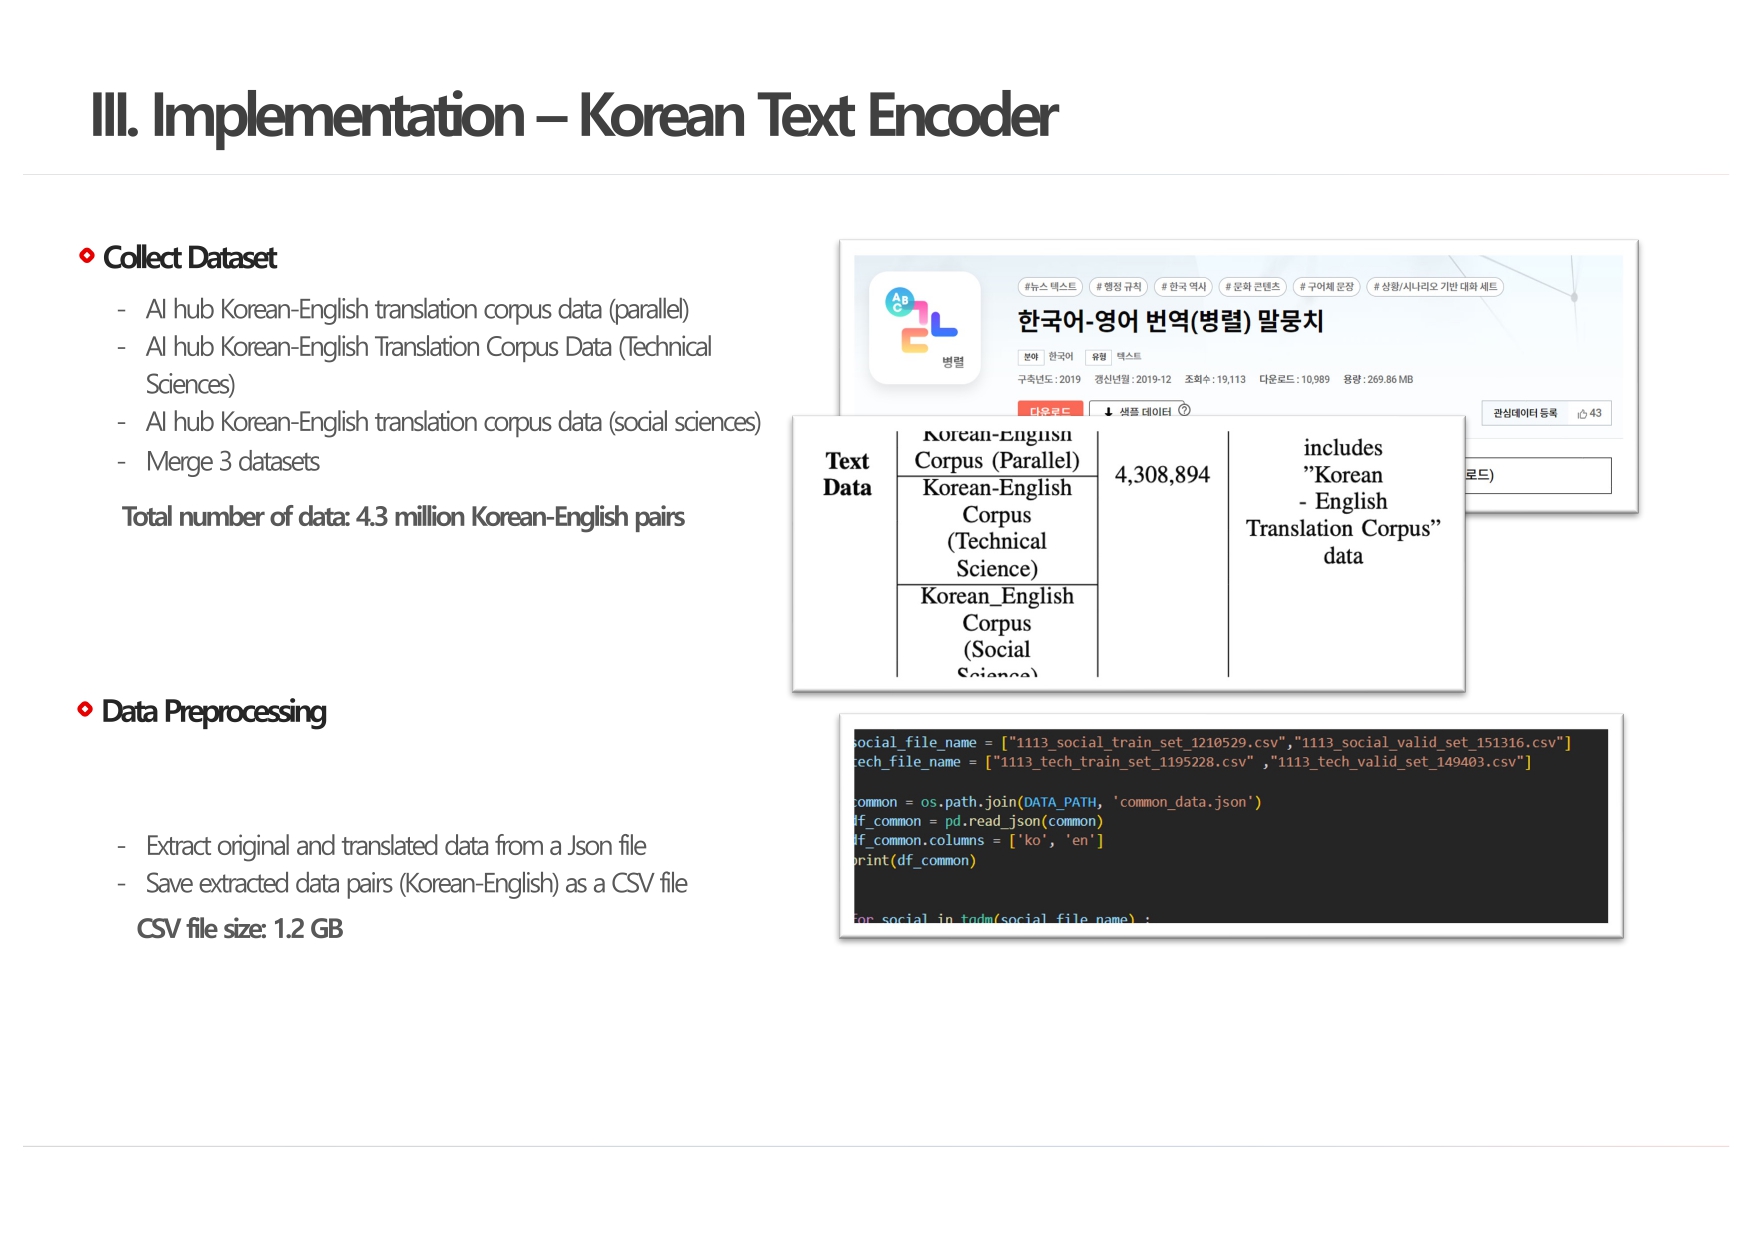
First, let's talk about the korean text encoder implementation. We collected three datasets named ˇ°Korean-English Translation Corpus Datasetˇ± from the AI Hub. And merged the three datasets to create 4.3 million Korean-English corpus pairs. The resulting preprocessed corpus pair CSV file was 1.2 gigabytes. | |
| [Go to Next Slide] |