 |
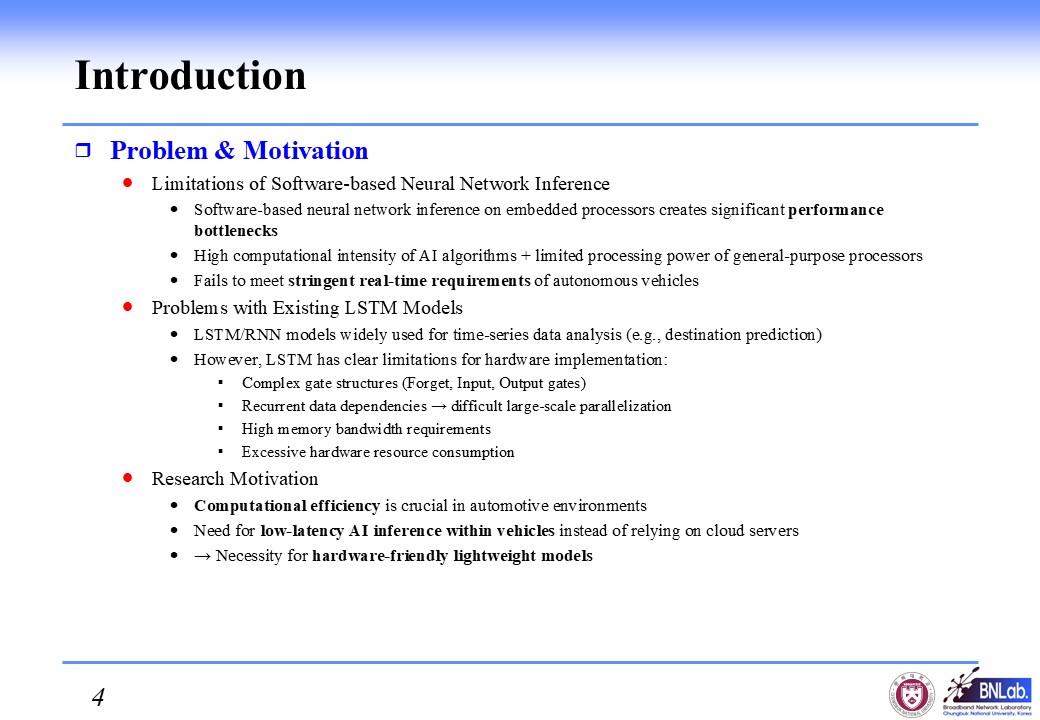
Software-based neural network inference on embedded processors creates significant performance bottlenecks and fails to meet real time requirements.
LSTM models have been widely used for destination prediction, but they have clear limitations for hardware implementation. Complex gate structures, recurrent data dependencies, and high memory bandwidth requirements make FPGA implementation inefficient.
Therefore, we need hardware-friendly lightweight models for low-latency AI inference within vehicles.
|
 IEEE/ICACT20260254 Slide.04
[Big Slide]
[YouTube]