 |
As researchers, we know why we don't have as many images available for training. It's not because we're not collecting enough; although it can be expensive to acquire medical images, healthcare centres already produce millions of scans each year both for direct care and for research worldwide. The images are acquired, they're just not openly available for research (nor should they be). Understandably, access to this data is highly constrained, even within institutions, thanks to important patient data privacy regulations.These privacy concerns are important and necessary, but this has limited us from fully maximizing the benefits of artificial intelligence in our research.
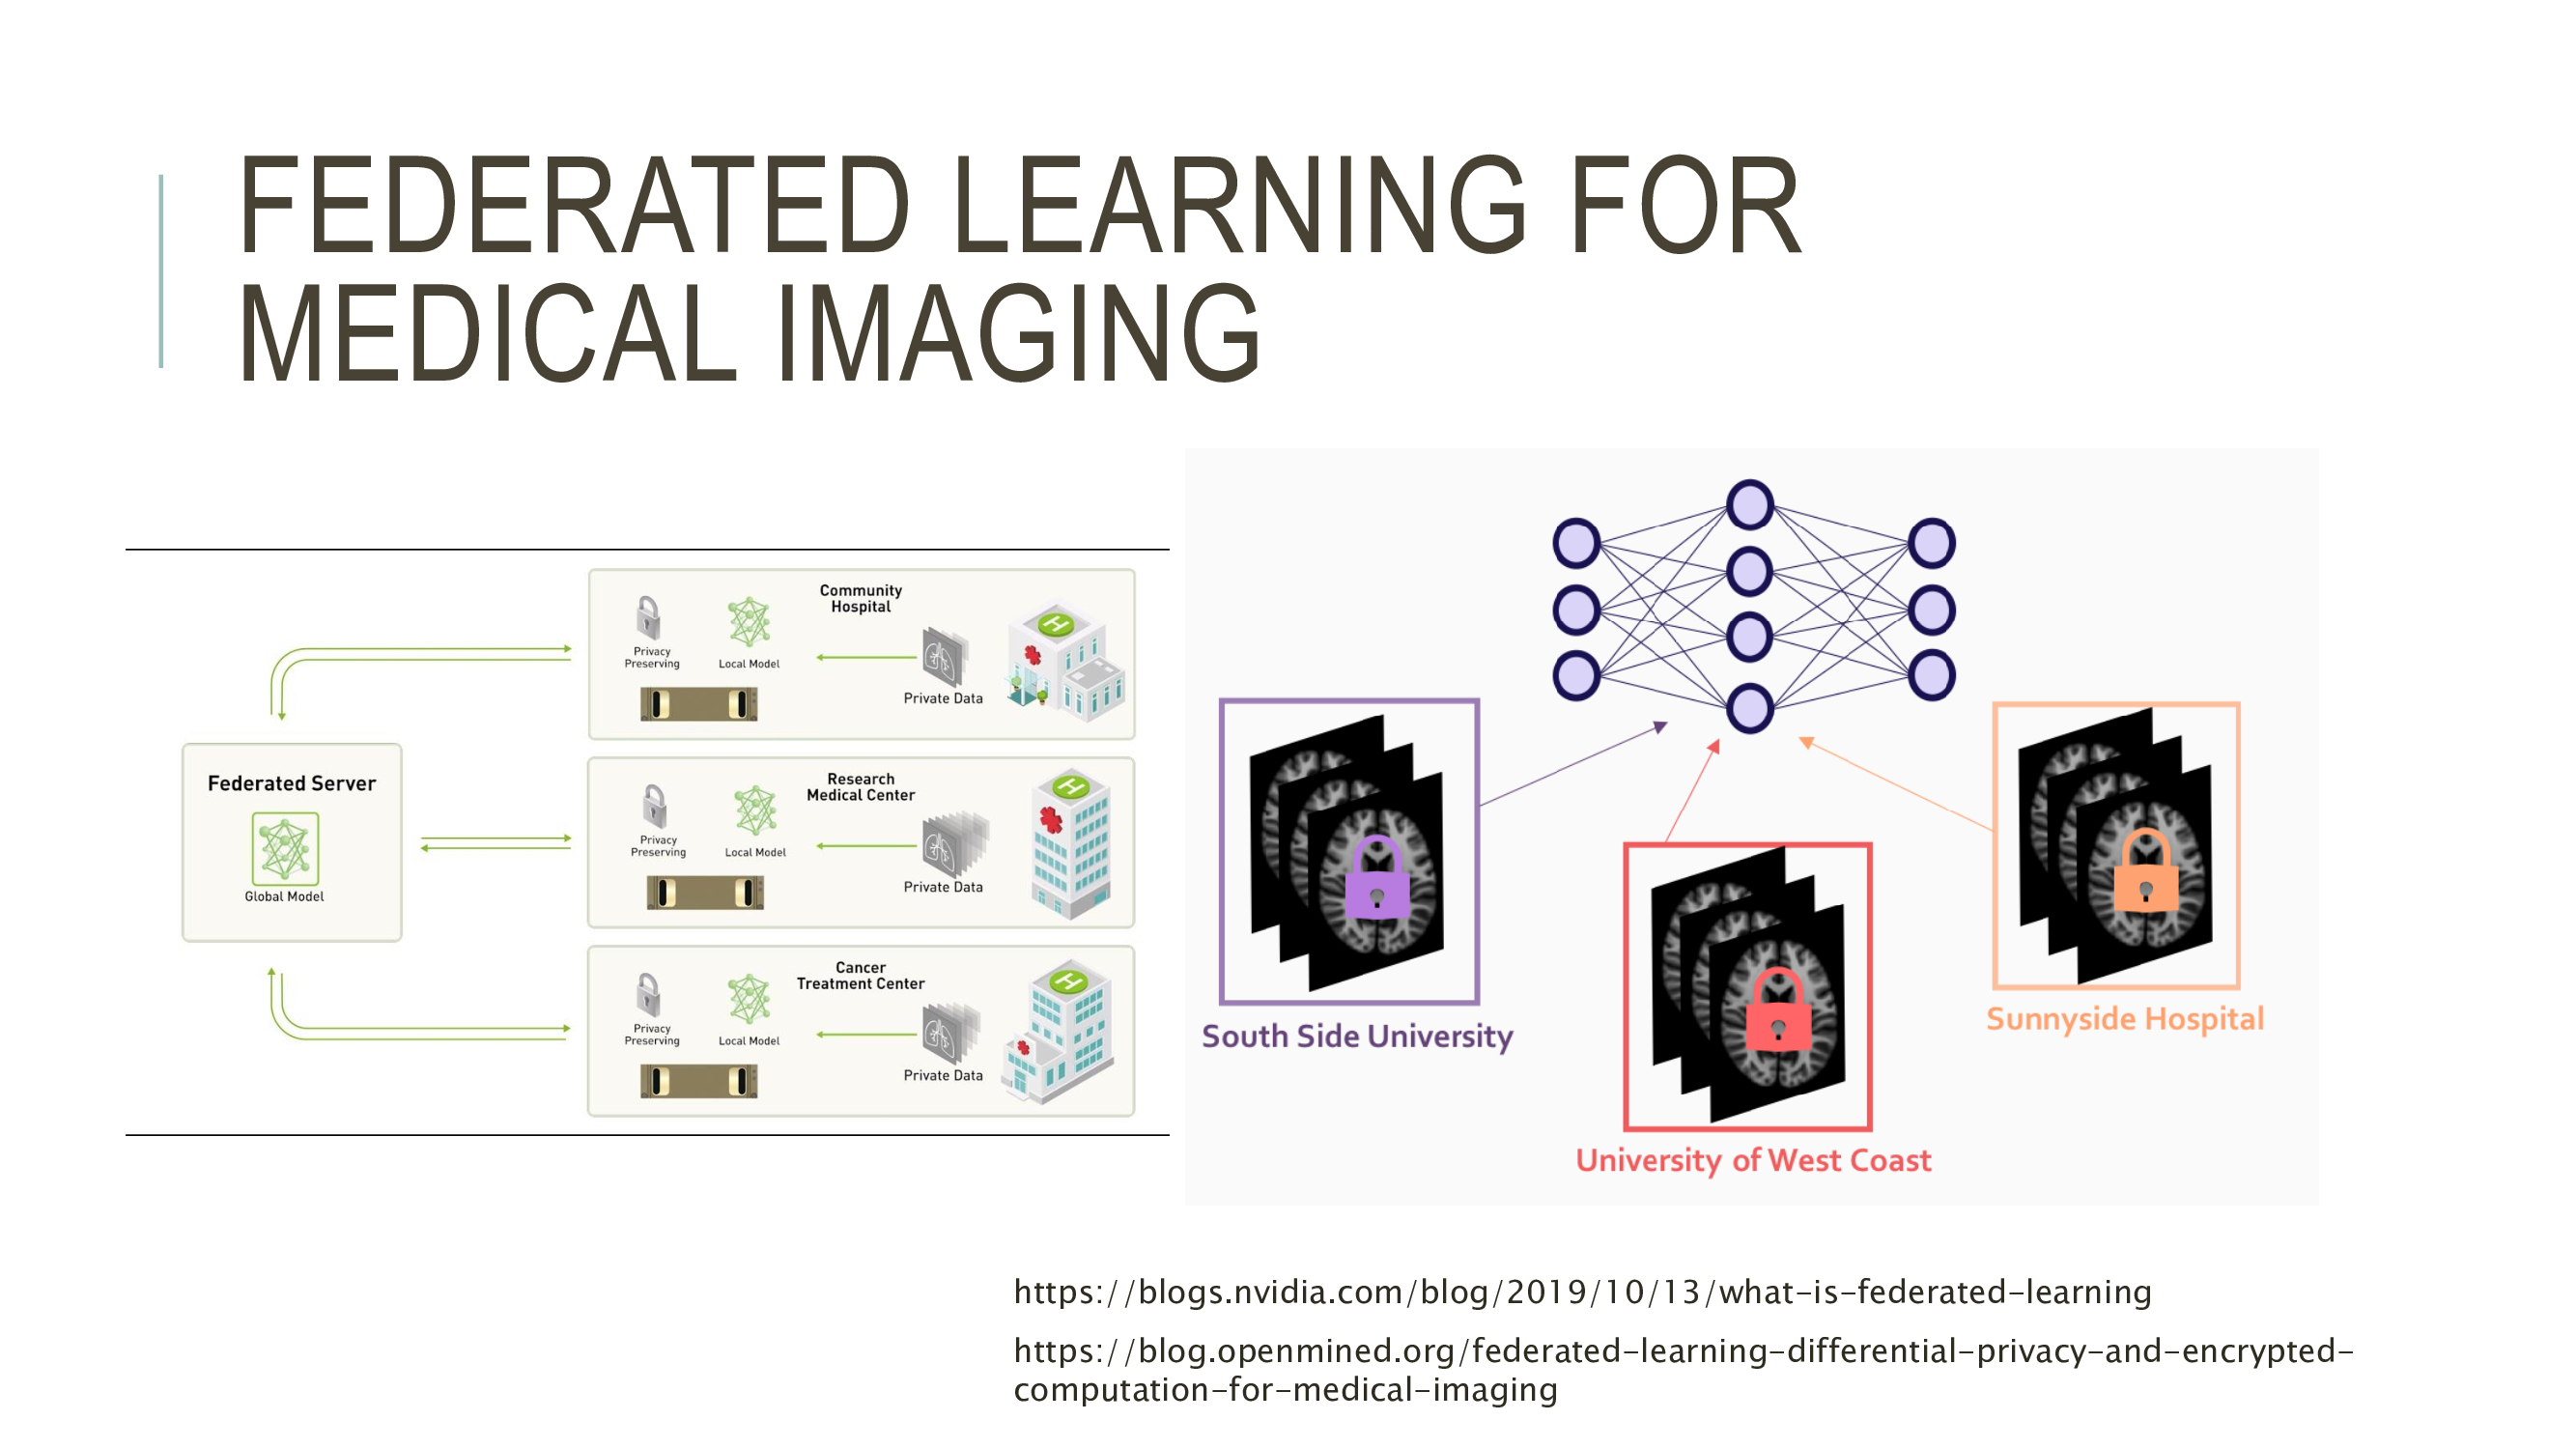
Our solution used federated learning, which allows us to train AI models on distributed datasets that we cannot access directly.
|
 IEEE/ICACT20210192 Slide.05
[Big Slide]