 |
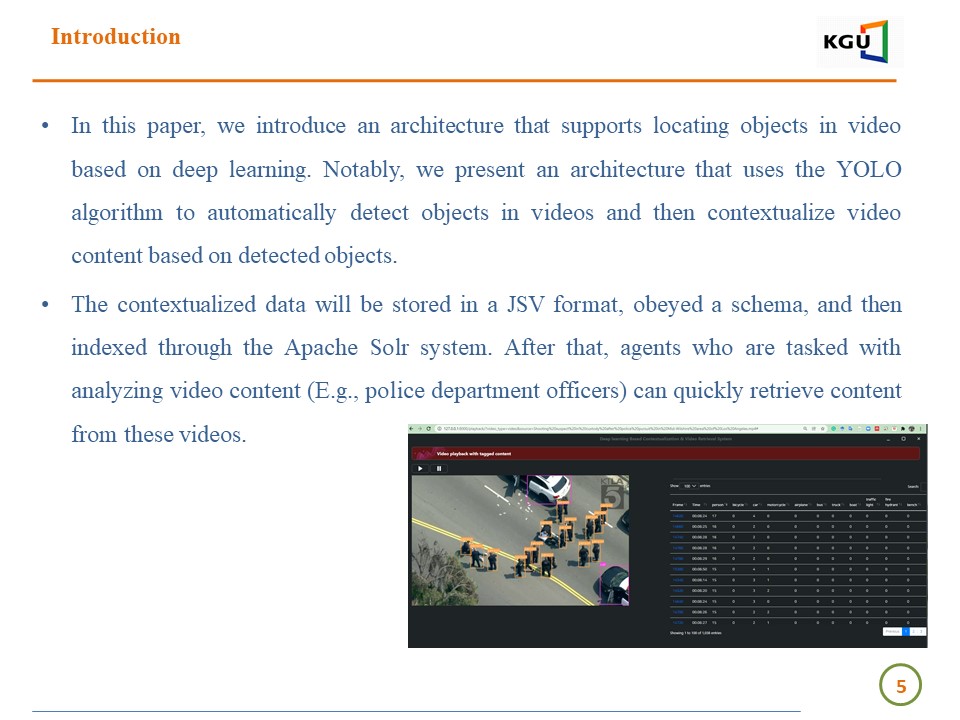
In this paper, we introduce an architecture that supports locating objects in video based on deep learning. Notably, we present an architecture that uses the YOLO algorithm to automatically detect objects in videos and then contextualize video content based on detected objects.
The contextualized data will be stored in a JSV format, obeyed a schema, and then indexed through the Apache Solr system. After that, agents who are tasked with analyzing video content (E.g., police department officers) can quickly retrieve content from these videos.
For more detail of slide 5 content, please watch the recorded clip on youtube at https://www.youtube.com/watch?v=oY1q12rwbfc |
 IEEE/ICACT20220317 Slide.05
[Big Slide]
[YouTube]