 IEEE/ICACT20230053 Slide.05
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20230053 Slide.05
[Big Slide]
| Oral Presentation |
|
|
|
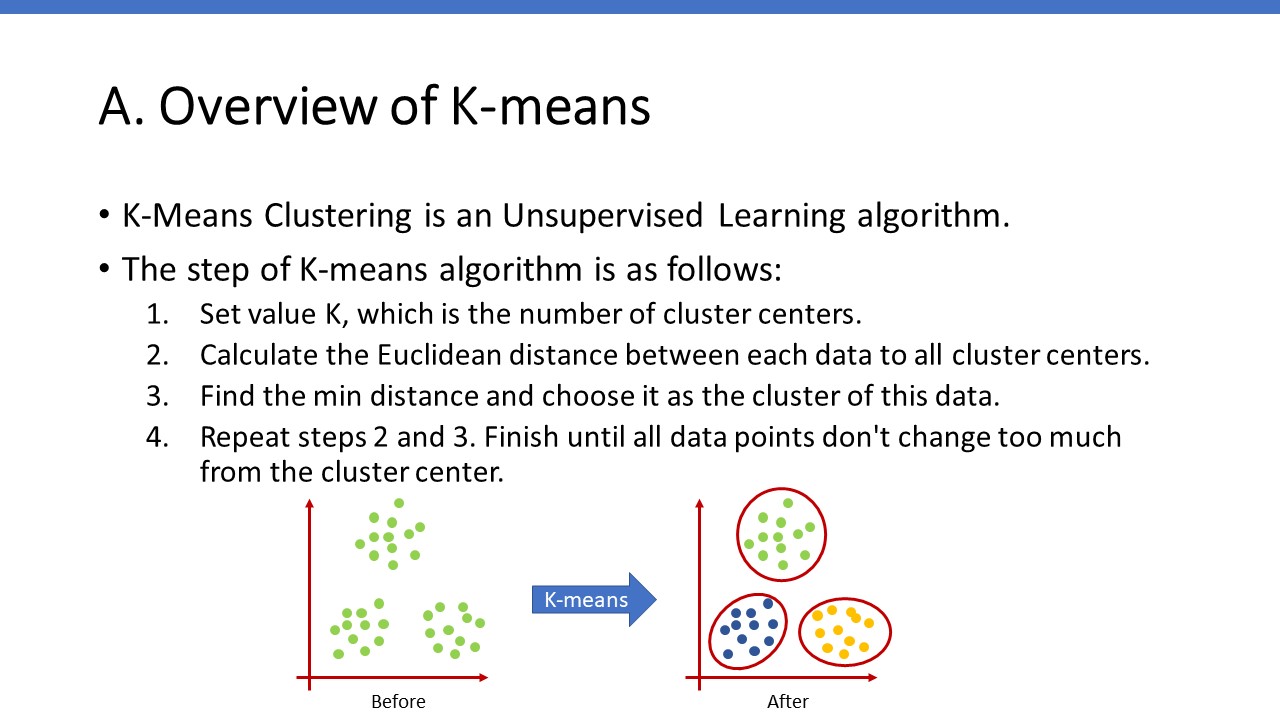
In data grouping, we use K-means to classify data. K-means is an unsupervised learning algorithm. The processing flow includes the following, first, set value K, which is the number of cluster centers, second, calculate the Euclidean distance between each data to all cluster centers. Third, Find the min distance and choose it as the cluster of this data, then repeat steps 2 and 3. Finish until all data points don't change too much from the cluster center. | |
| [Go to Next Slide] |