 |
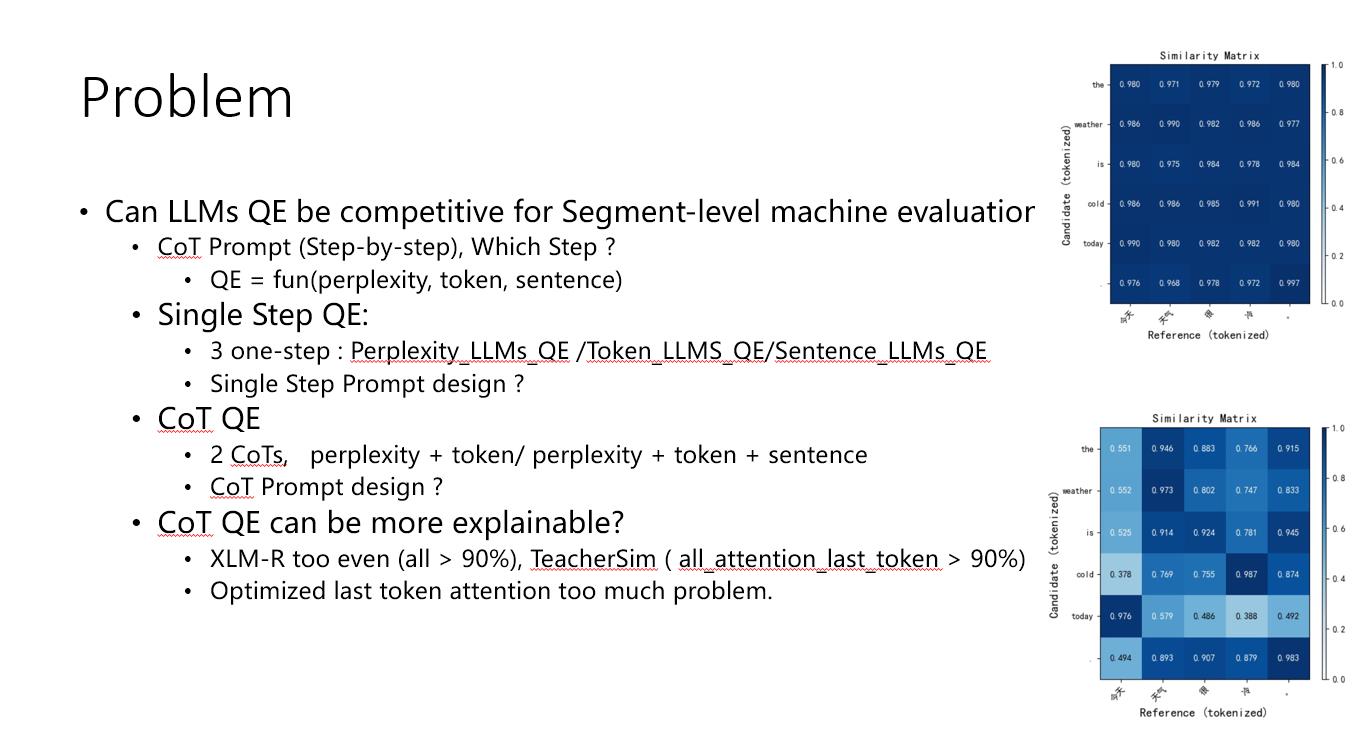
key points and questions on using large language models (LLMs) for fine-grained, interpretable quality estimation:
Can chain-of-thought (CoT) prompting make LLMs competitive with state-of-the-art models for segment-level machine translation evaluation?
What is the optimal CoT prompt design tracing model reasoning step-by-step?
Formally, LLM quality estimation (QE) is f(perplexity, token, sentence) scores.
We compare:
3 single-step models using each feature individually
2 CoT models combining perplexity + token and perplexity + token + sentence
How to design effective single-step vs CoT prompts?
We hypothesize CoT explanations can increase model interpretability. However, common approaches like XLM-R and TeacherSim overly optimize attention to the last token, reducing meaningfulness.
Key questions are:
Can CoT prompting improve on single-step performance?
How to design prompts guiding reasoning and explanation?
Can CoT interpretability outperform attention-based methods?
We aim to thoroughly evaluate knowledge prompting strategies for segment-level quality estimation using LLMs. |
 IEEE/ICACT20240321 Slide.05
[Big Slide]