 IEEE/ICACT20250006 Slide.05
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20250006 Slide.05
[Big Slide]
| Oral Presentation |
|
|
|
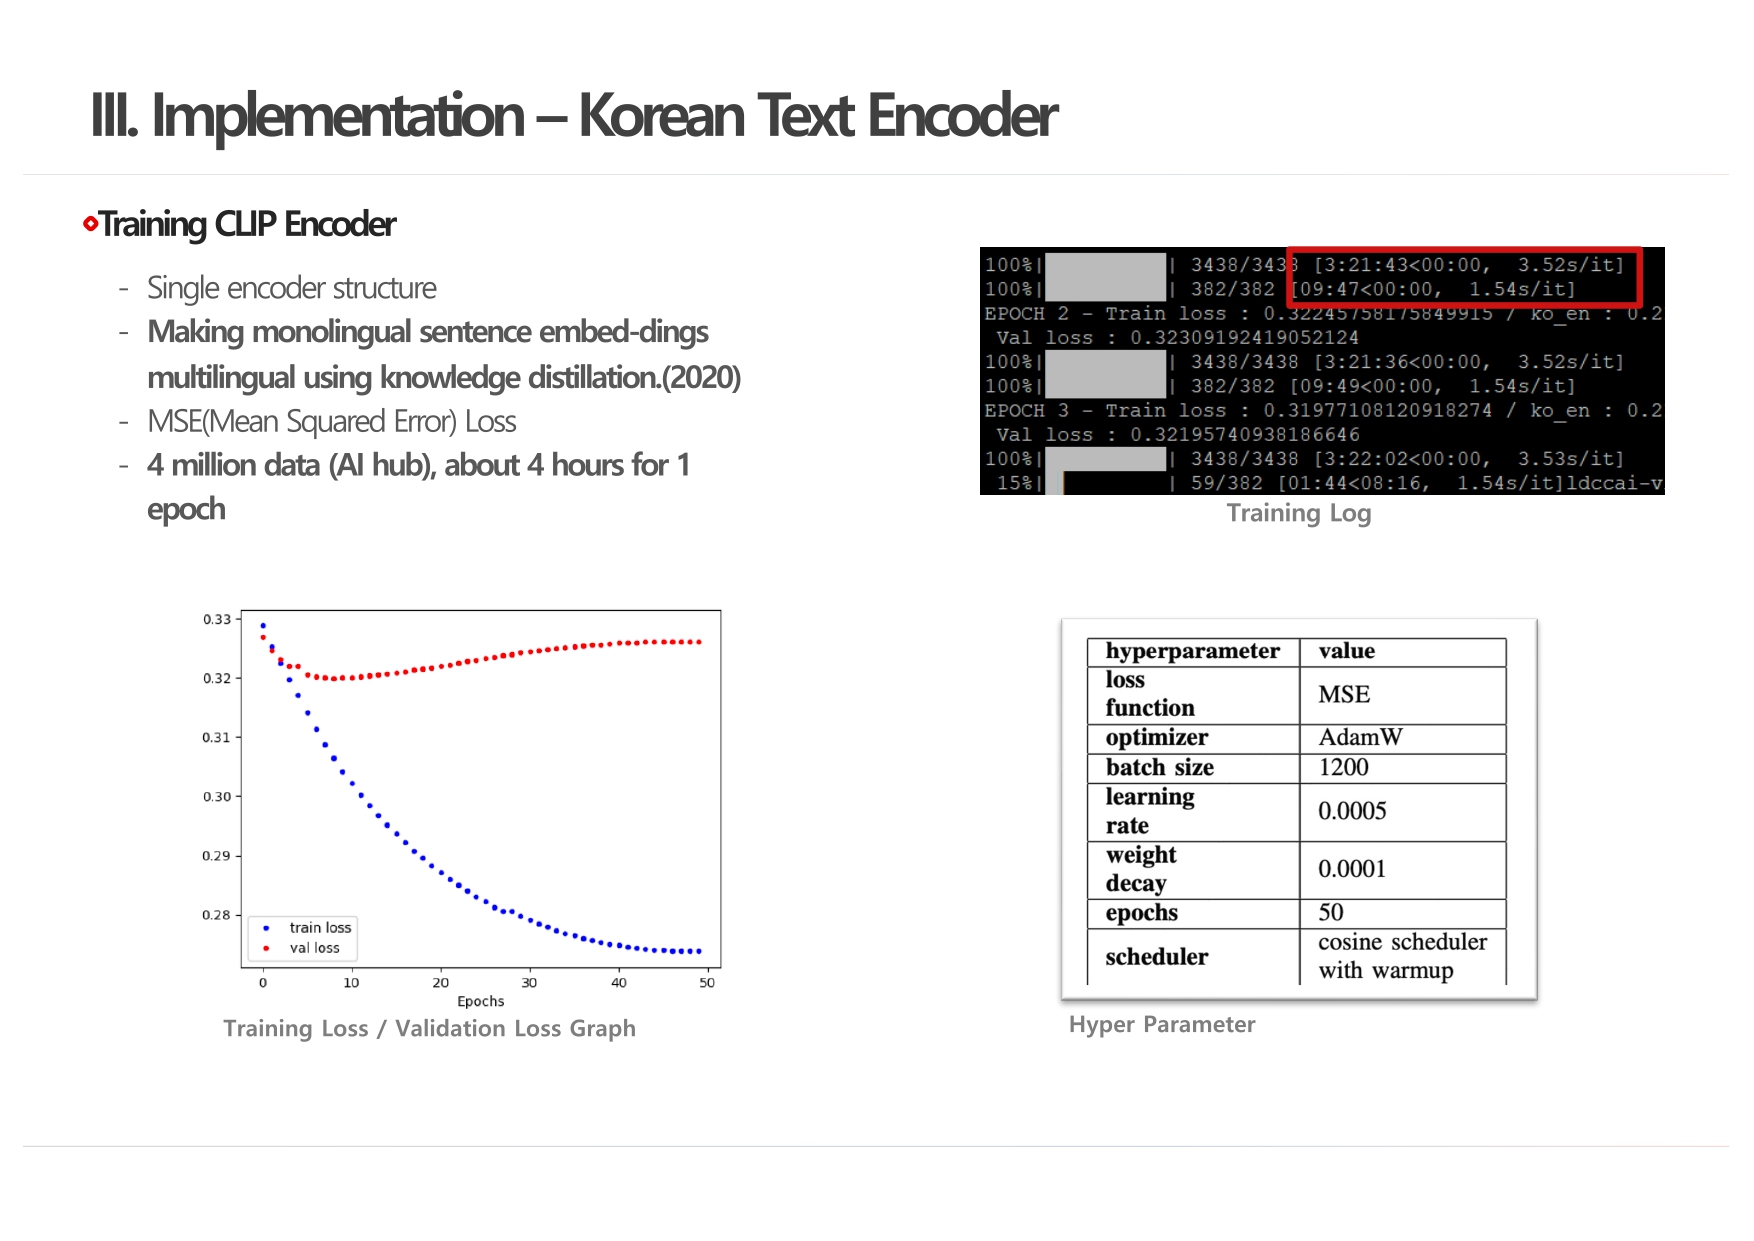
After collecting datasets, we trained CLIP Encoder with the Korean datasets. We used a method in the paper "Making monolingual sentence embeddings multilingual using knowledge distillation, 2020". For the training, used hyperparameter is shown in the slide. | |
| [Go to Next Slide] |