 IEEE/ICACT20260046 Slide.05
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20260046 Slide.05
[Big Slide]
| Oral Presentation |
|
|
|
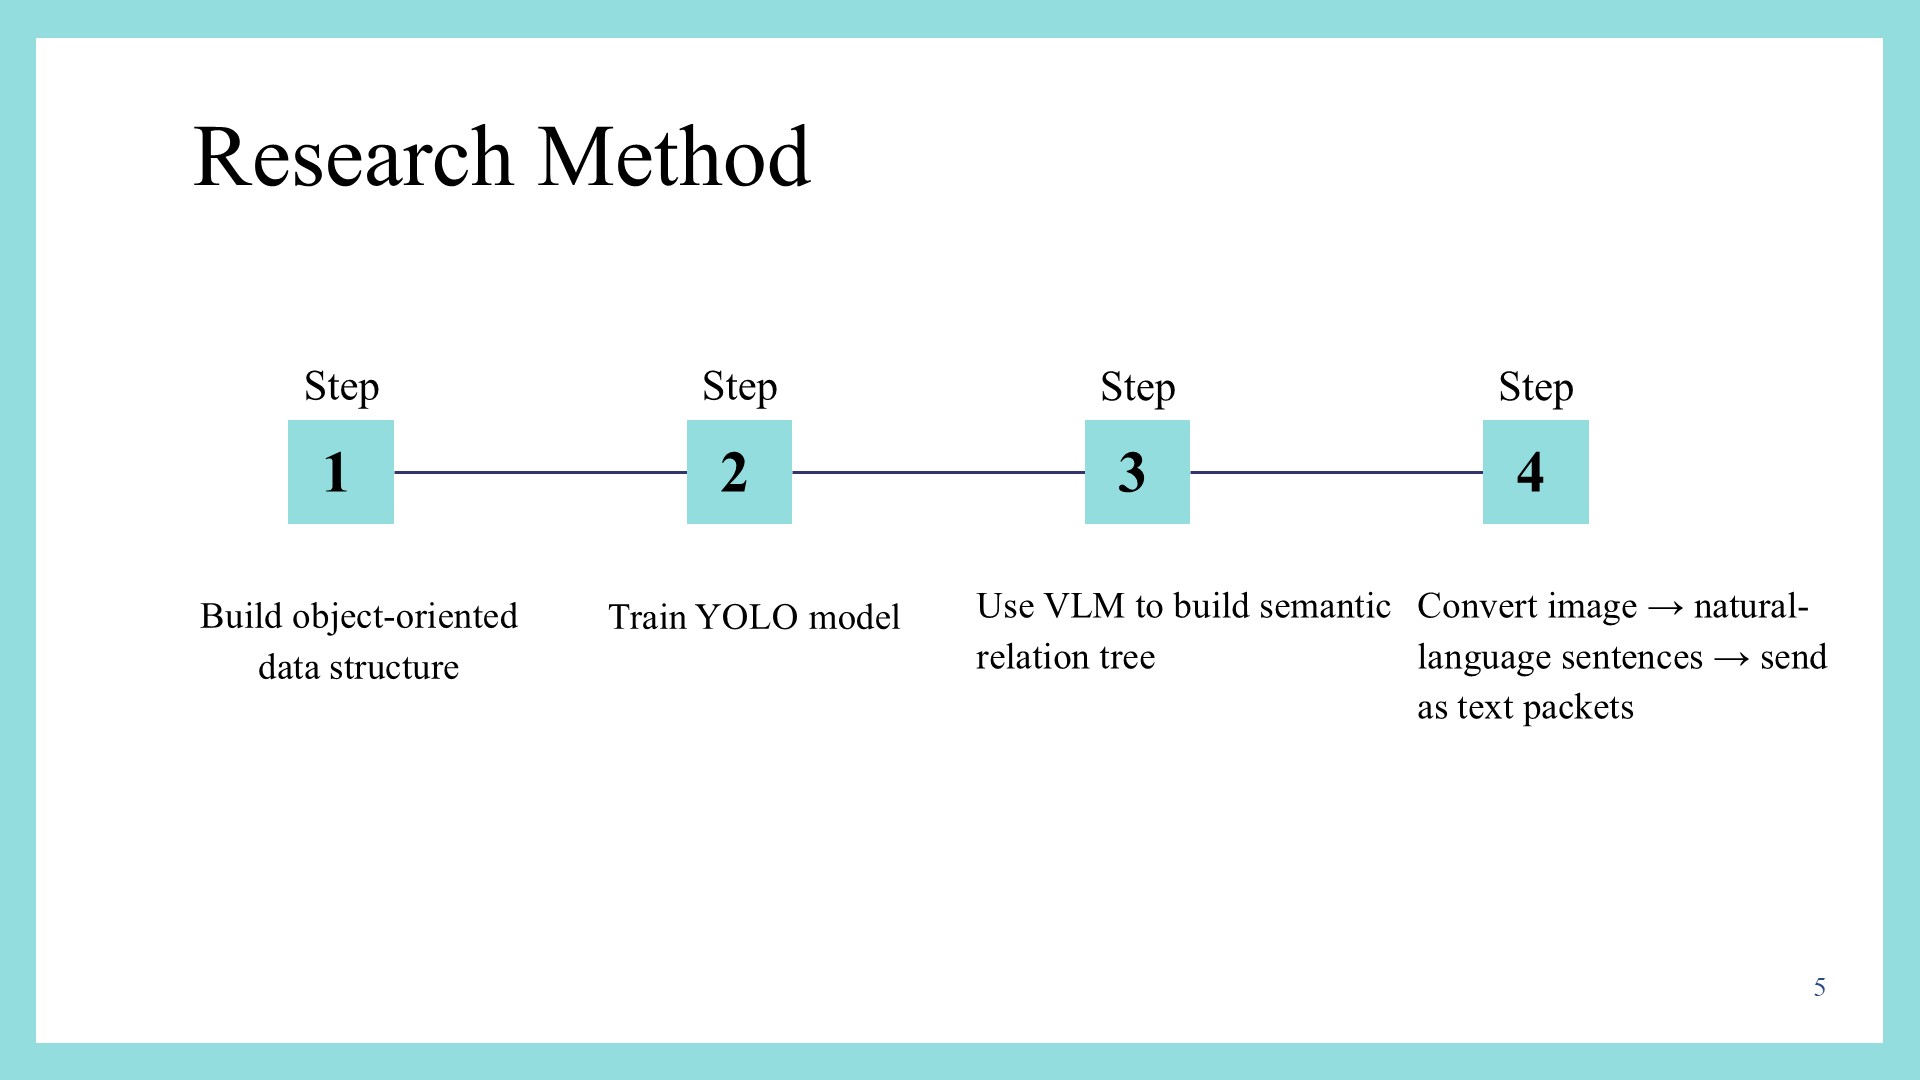
Our solution has four steps. First, we use YOLO to detect objects in the image. Second, we build a data structure to store object attributes such as color, size, and position. Third, we use a Vision Language Model to create a relationship tree between each of the objects. Finally, we convert the image into simple natural-language sentences and send only text through to the network. Next I`m going to explain why we use YOLO to detect objects. | |
| [Go to Next Slide] |