 |
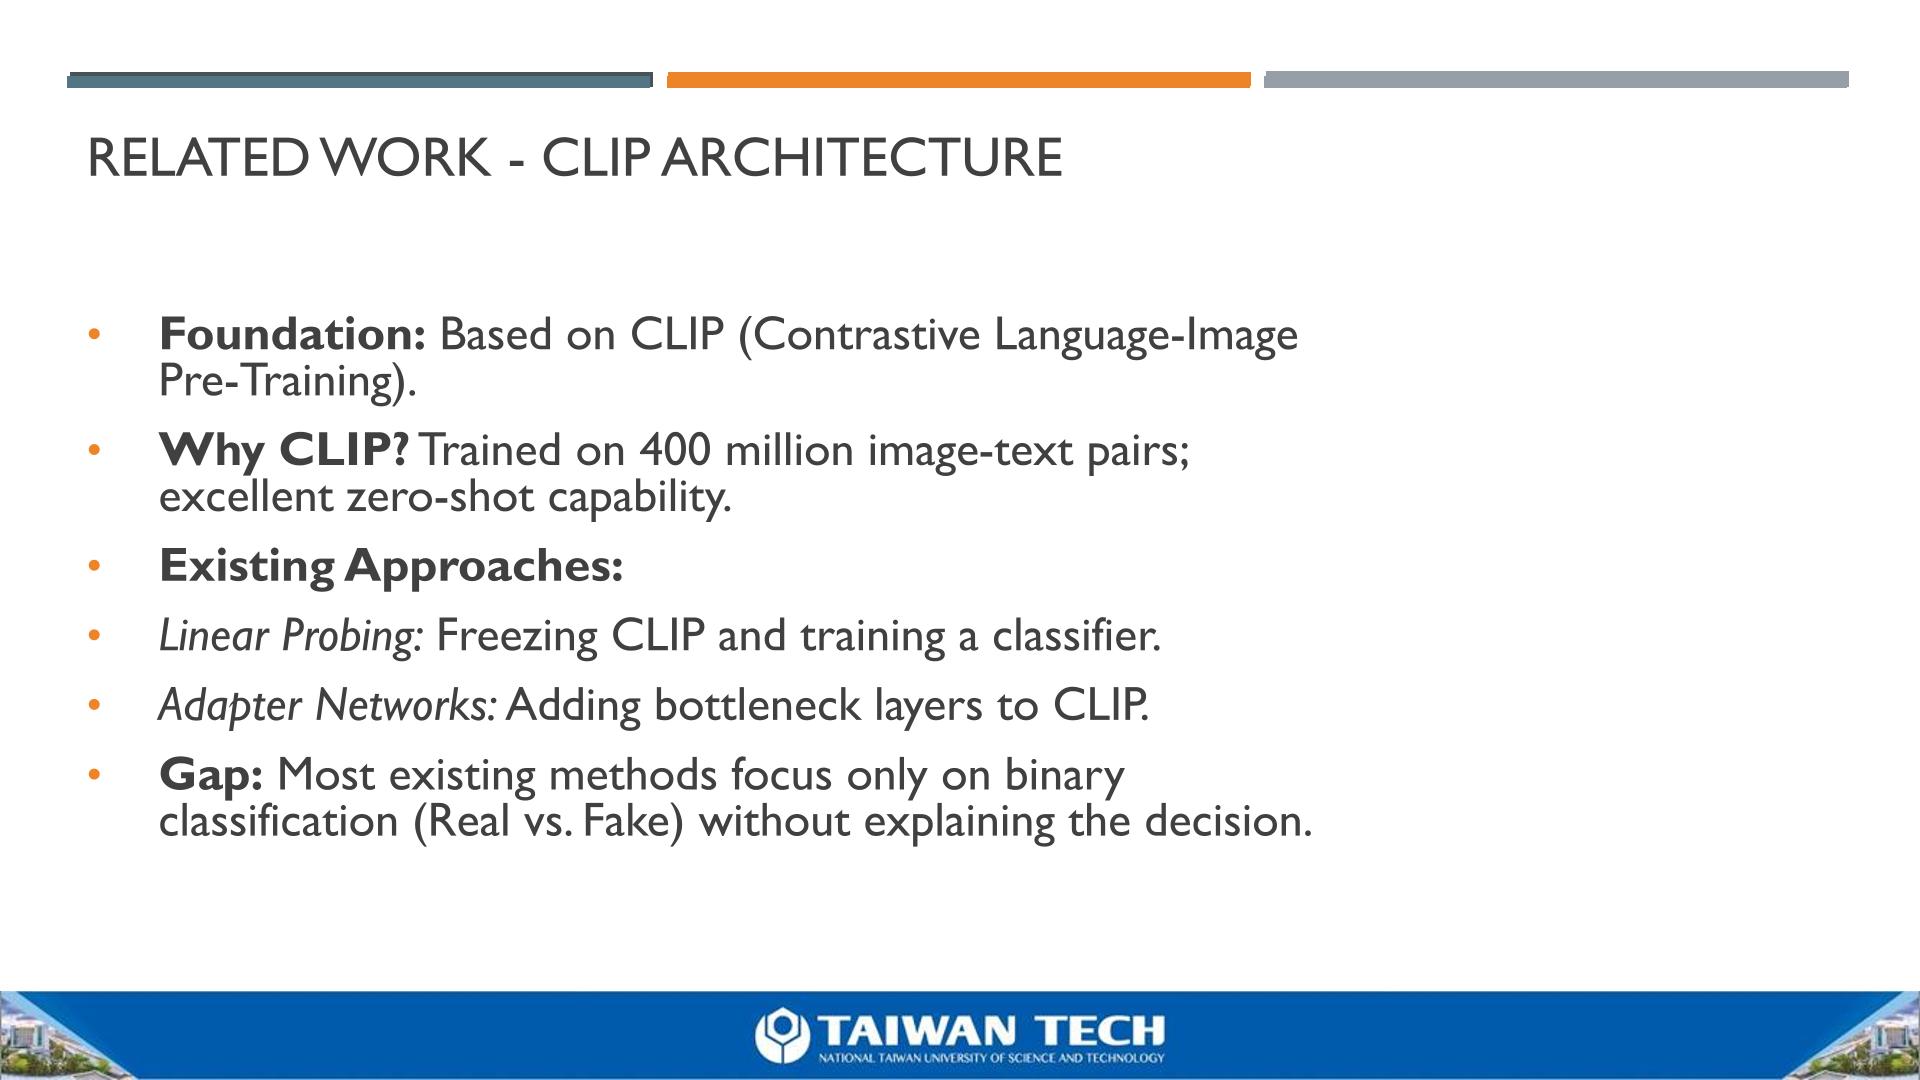
The research builds upon the CLIP architecture, a multimodal model pre-trained on 400 million image-text pairs and known for strong zero-shot capabilities . While existing methods like "Linear Probing" or "Adapter Networks" utilize CLIP for detection, these approaches typically focus solely on binary classification- determining if an image is real or fake without providing an explanation . This work addresses that gap by enhancing CLIPs semantic understanding through generated descriptions and adding an interpretability layer to identify specific generation traces . |
 IEEE/ICACT20260070 Slide.05
[Big Slide]