 |
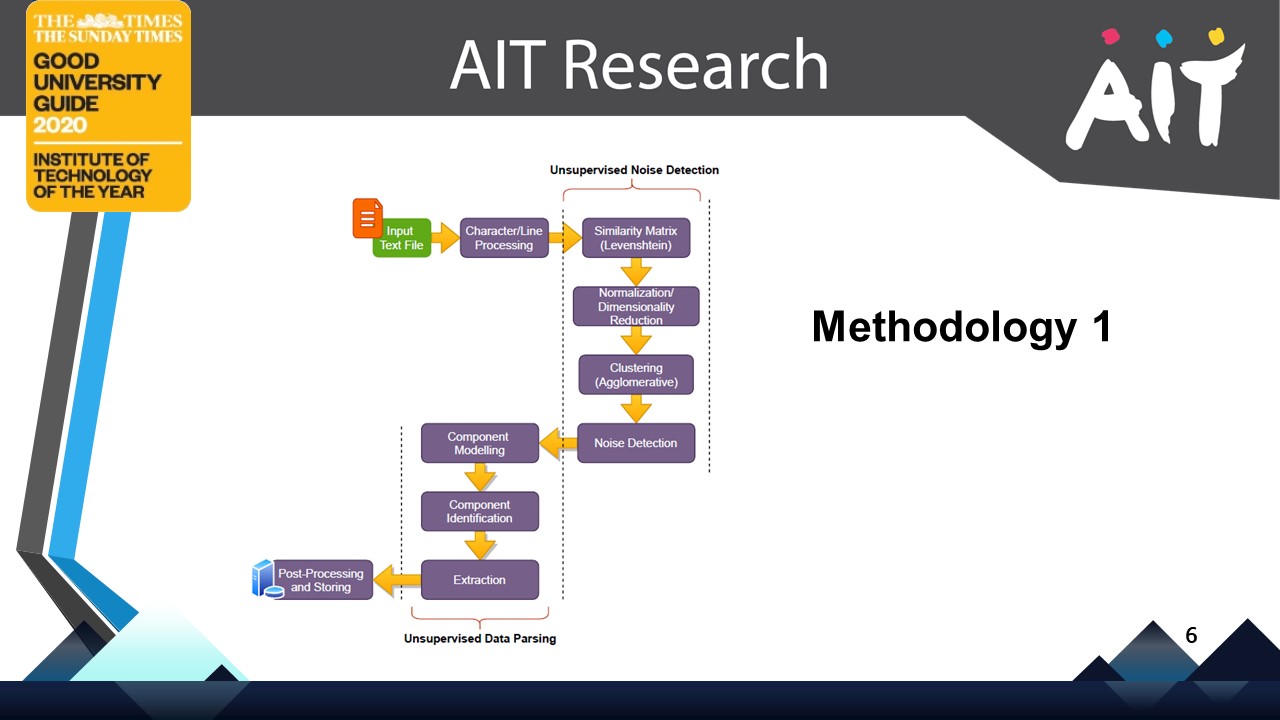
As illustrated in this figure, we use this similarity matrix to cluster the lines of text using Agglomerative clustering. This clustering technique identifies the two closest lines and merges them to form a cluster, repeating this all the lines are merged into a single cluster. The distance between consecutive pairs of nearest lines is recorded to generate a dendrogram that classifies the input file into noise and data. We further use the classified file with noise and data to identify table components. We analyze data rows using white space distribution and index positions of the words. We analyze lines and calculate a similarity score and meta score, which is the word's size and the front and back whitespaces. We use these scores to calculate the mean and then split words in the line and append them to a column. We further analyze the maximum similarity score in the lines and label that as our header line.
|
 IEEE/ICACT20210237 Slide.06
[Big Slide]
[YouTube]