 IEEE/ICACT20220147 Slide.06
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20220147 Slide.06
[Big Slide]
| Oral Presentation |
|
|
|
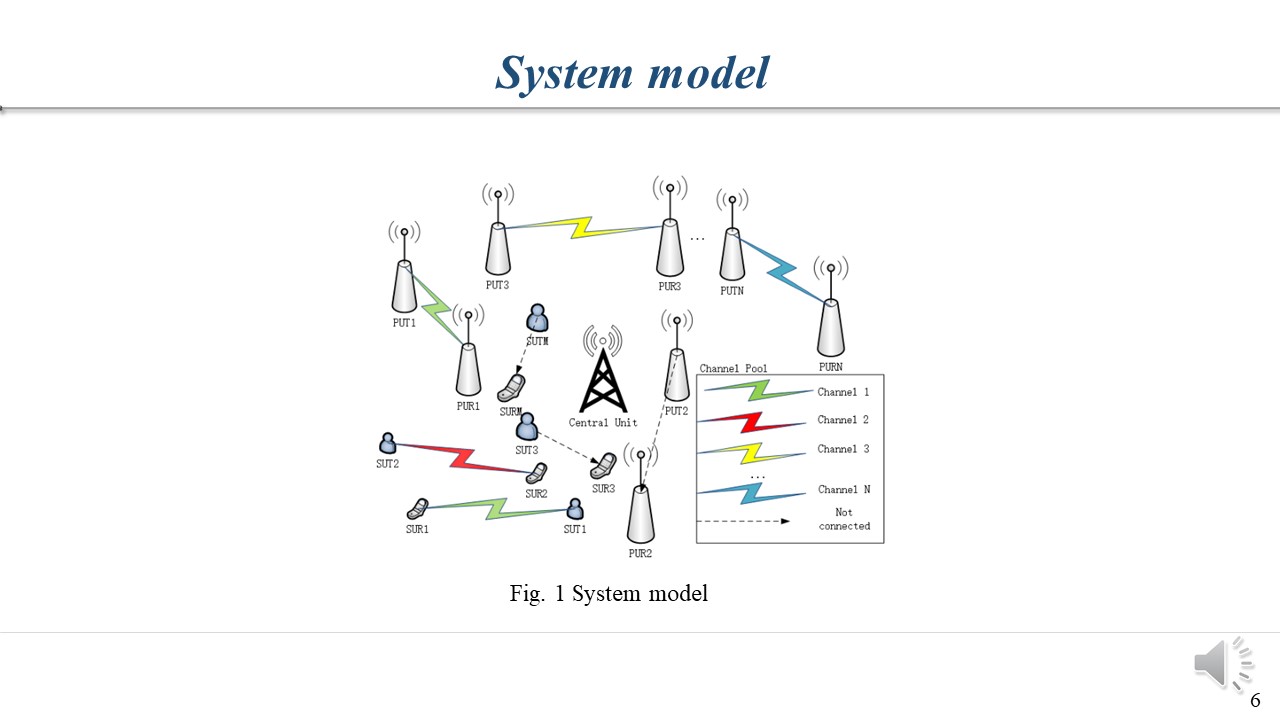
Using deep reinforcement learning techniques that enable devices to make their own judgments based on channel information. Also considering the cost and the interference between SUs, we use the central unit for uniform learning and scheduling. Our system model is shown in Fig. In a multi-PU DSA network, a central unit performs state identification based on the state information of the channel, and then schedules other SUs uniformly for access actions. | |
| [Go to Next Slide] |