 |
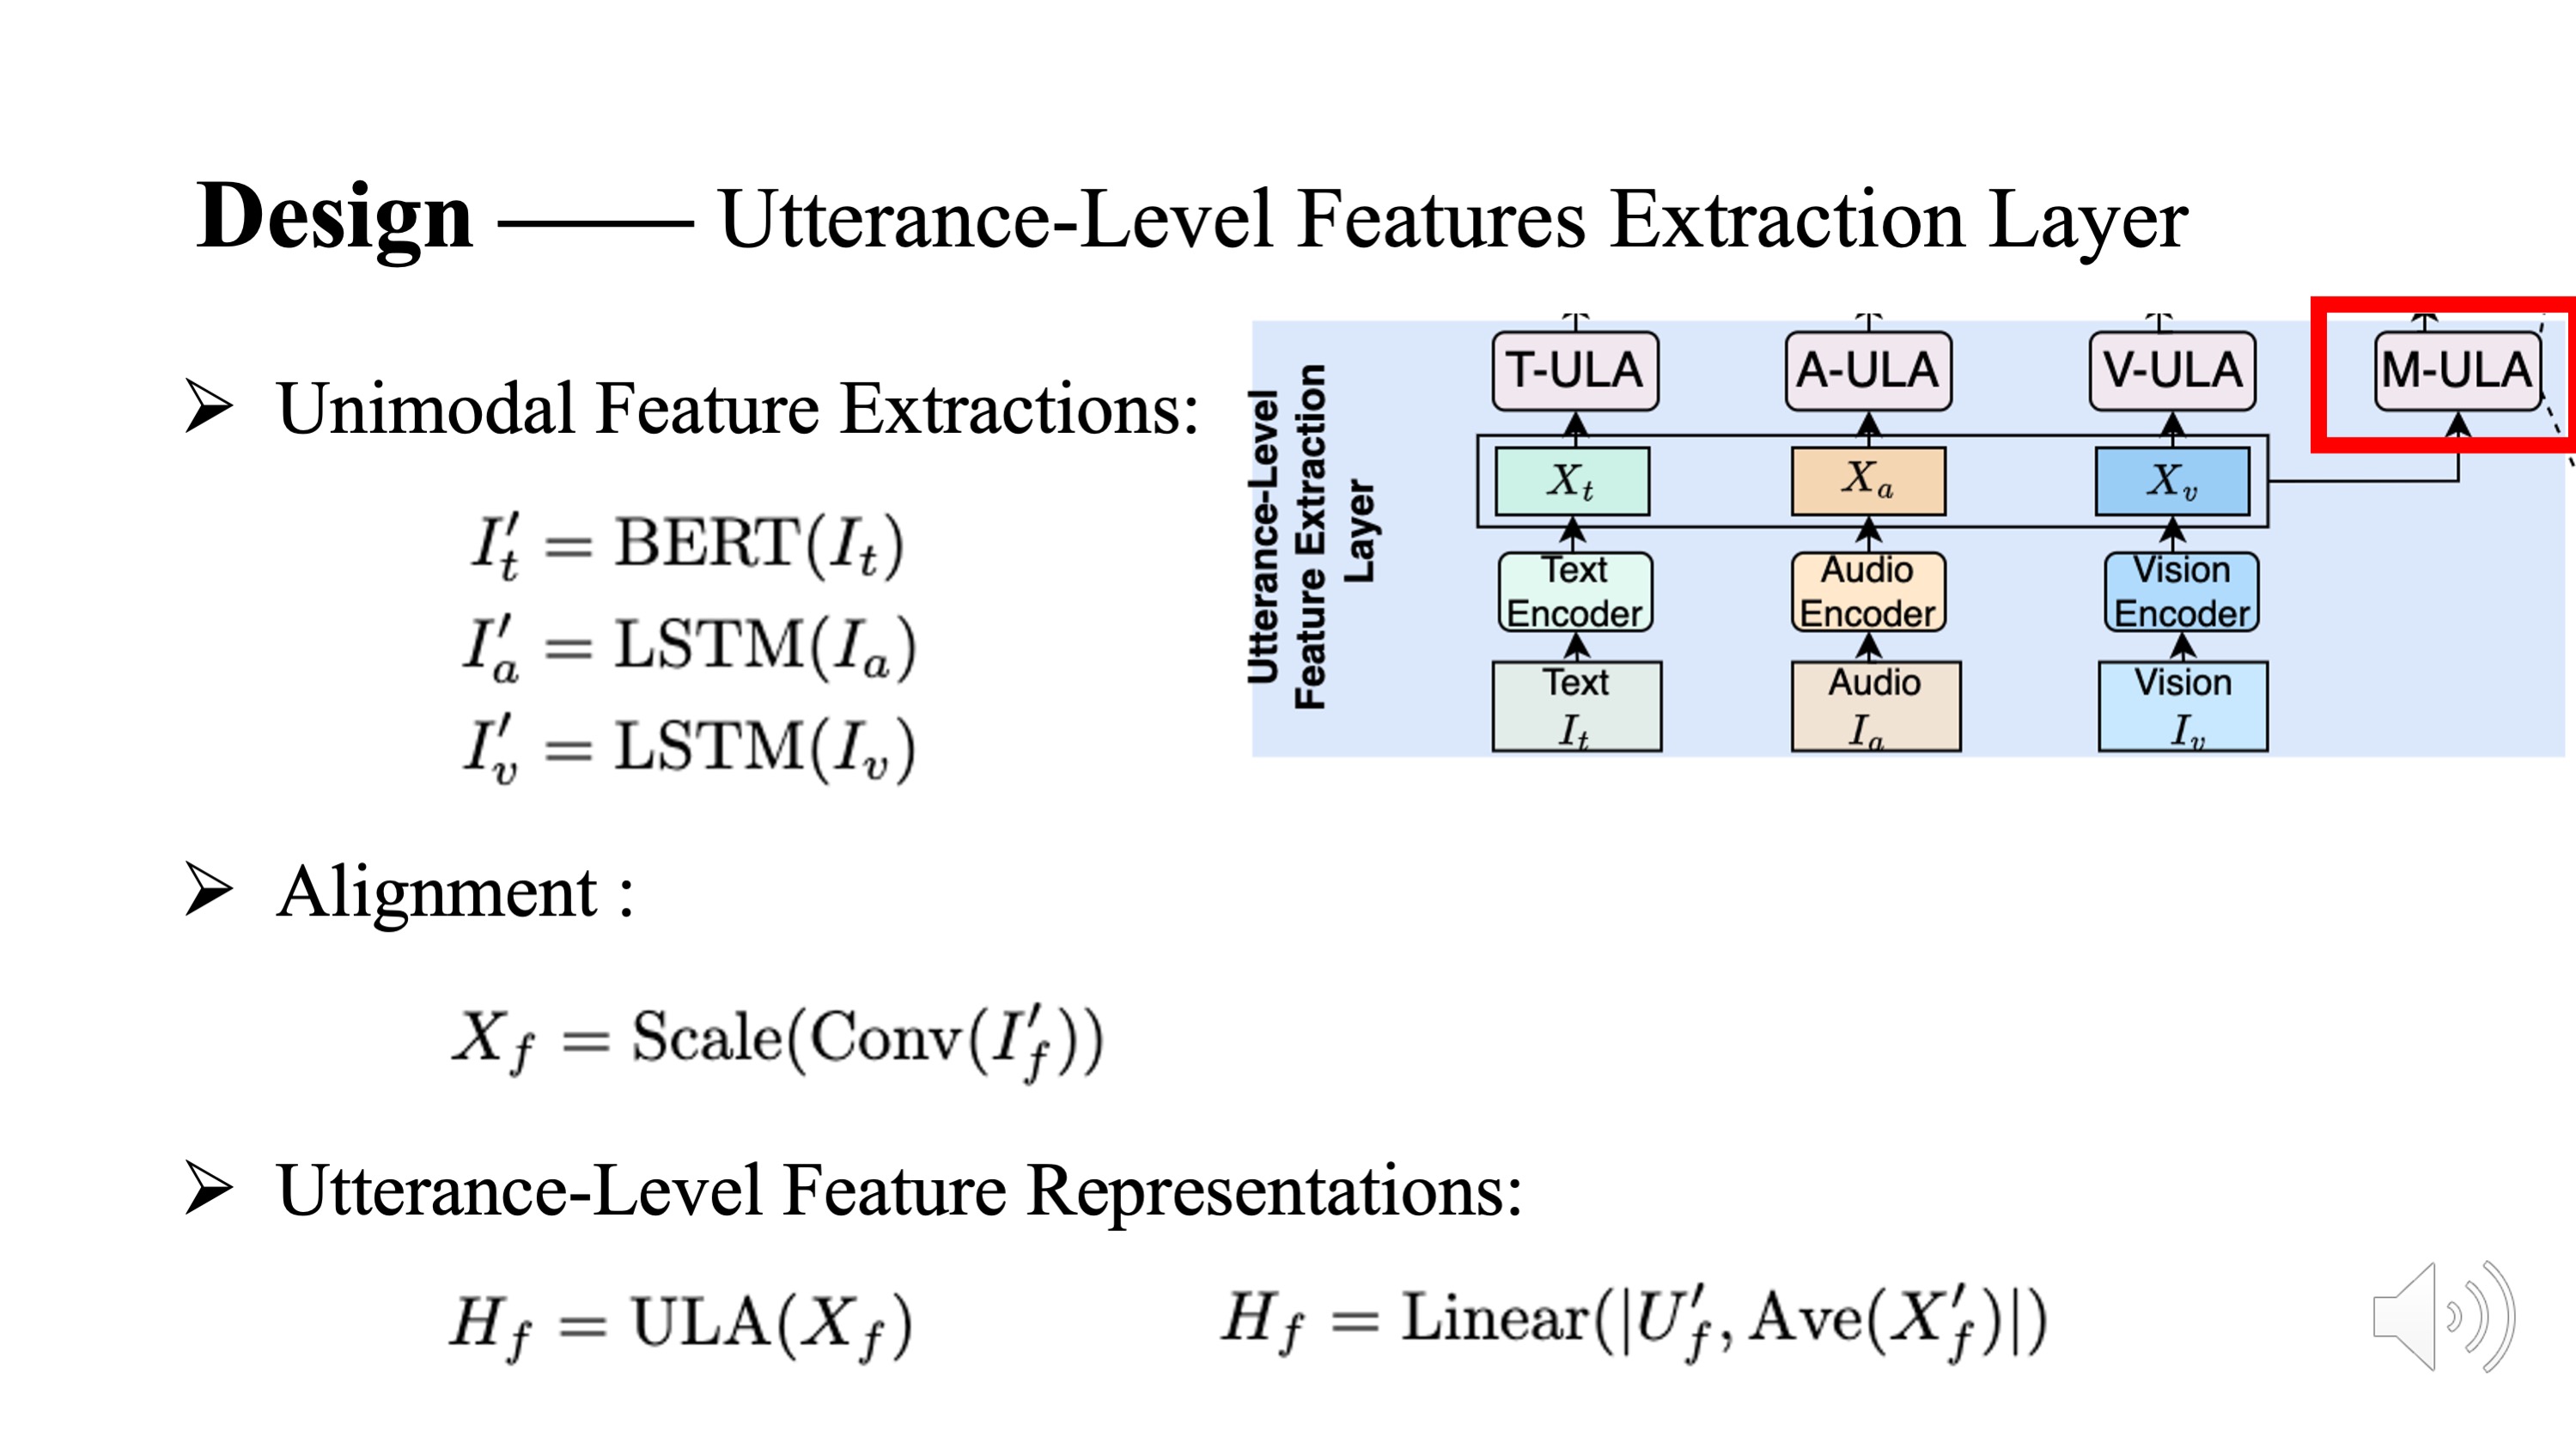
For the unimodal feature extractions, we employ a pre-trained BERT-base model to encode the input textual tokens into word embedding, and take advantage of Long Short-Term Memory(LSTM) to extract audio and vision features.
Next for the alignment part, we deploy a 1-dimensional convolution layer and a scale layer to align the dimension of feature vectors space.
And for the Utterance-Level Feature Representations, we employ utterance-level attention(ULA) to learn the distinctive properties of unimodal modality, as for the detailed information, refer to the next page.
|
 IEEE/ICACT20240342 Slide.06
[Big Slide]