 IEEE/ICACT20260046 Slide.06
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20260046 Slide.06
[Big Slide]
| Oral Presentation |
|
|
|
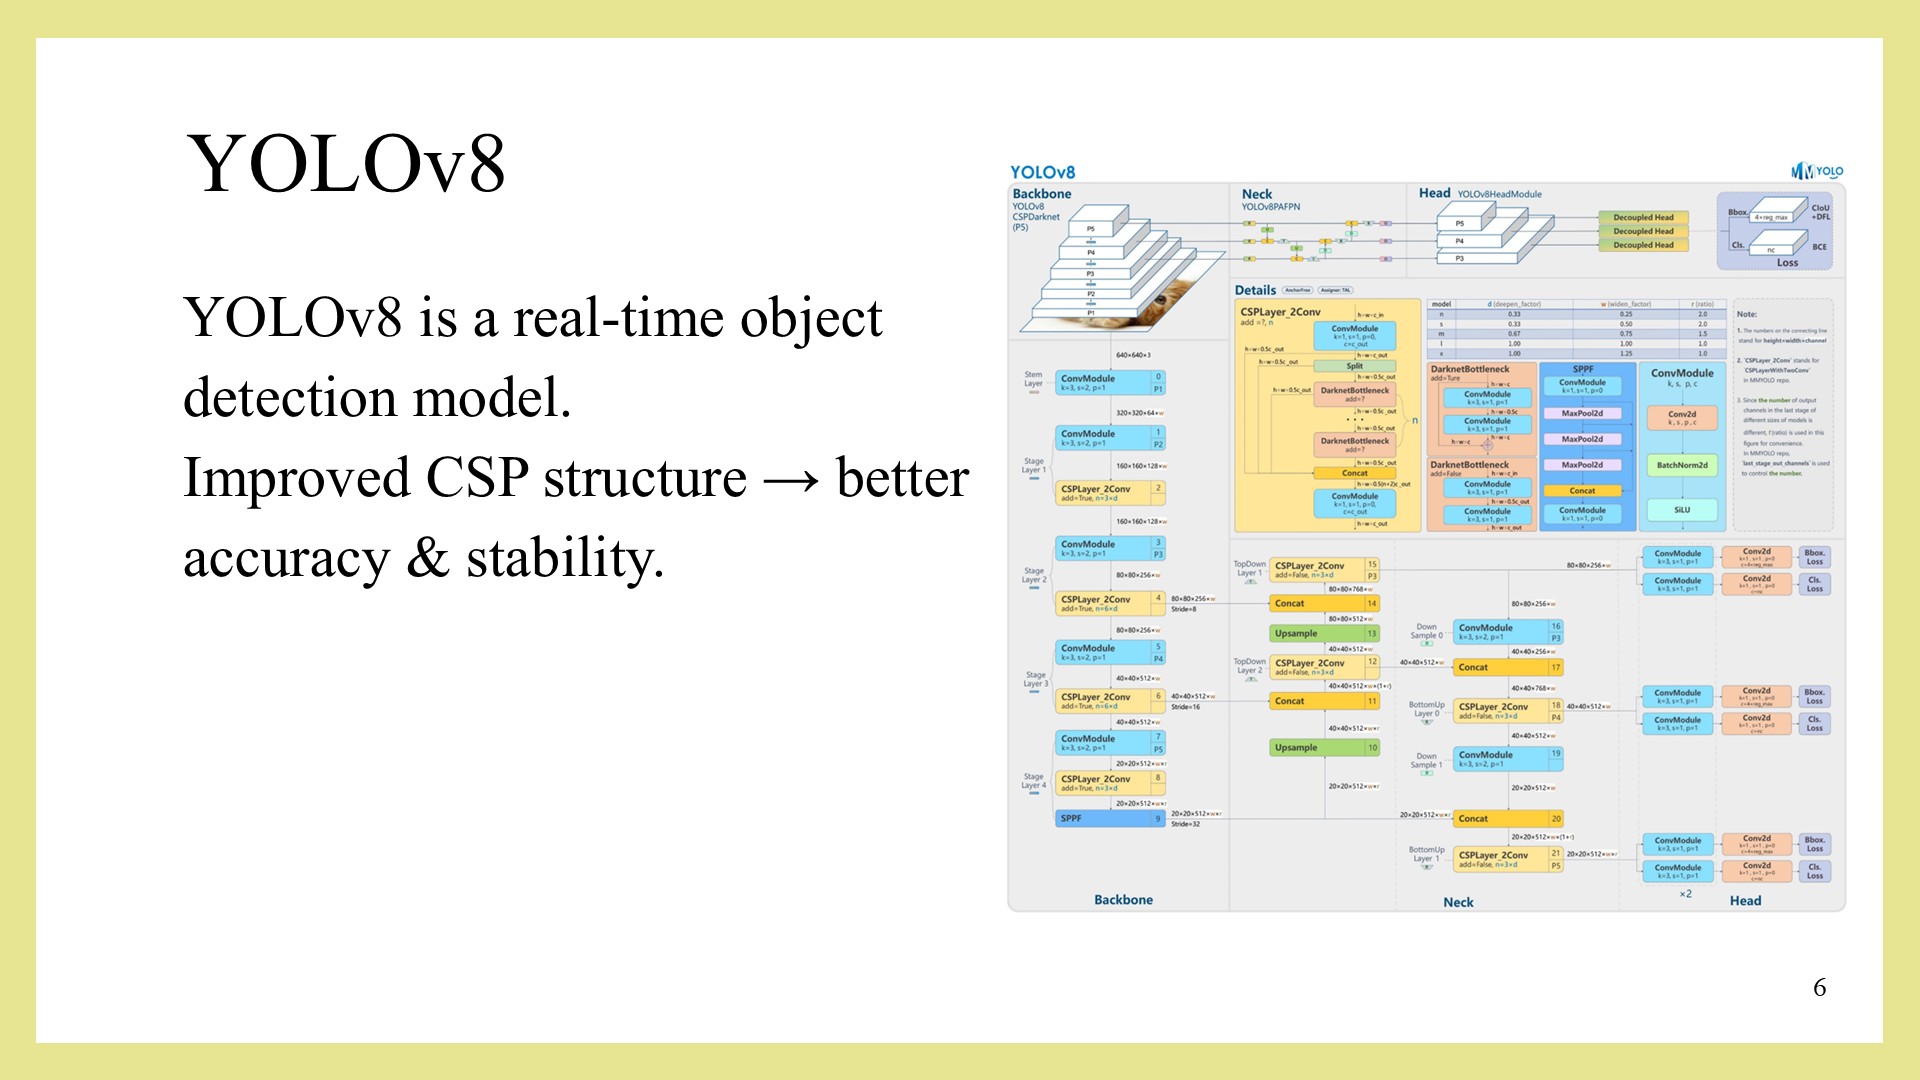
We chose YOLOv8 to be our detection training model because it is a relatively mature training structure(architecture). (In our research£¬ we improved the YOLOv8 CSP structure to have better accuracy and stability.) In the next section, we are going to discuss how we turn image content into text. | |
| [Go to Next Slide] |