 |
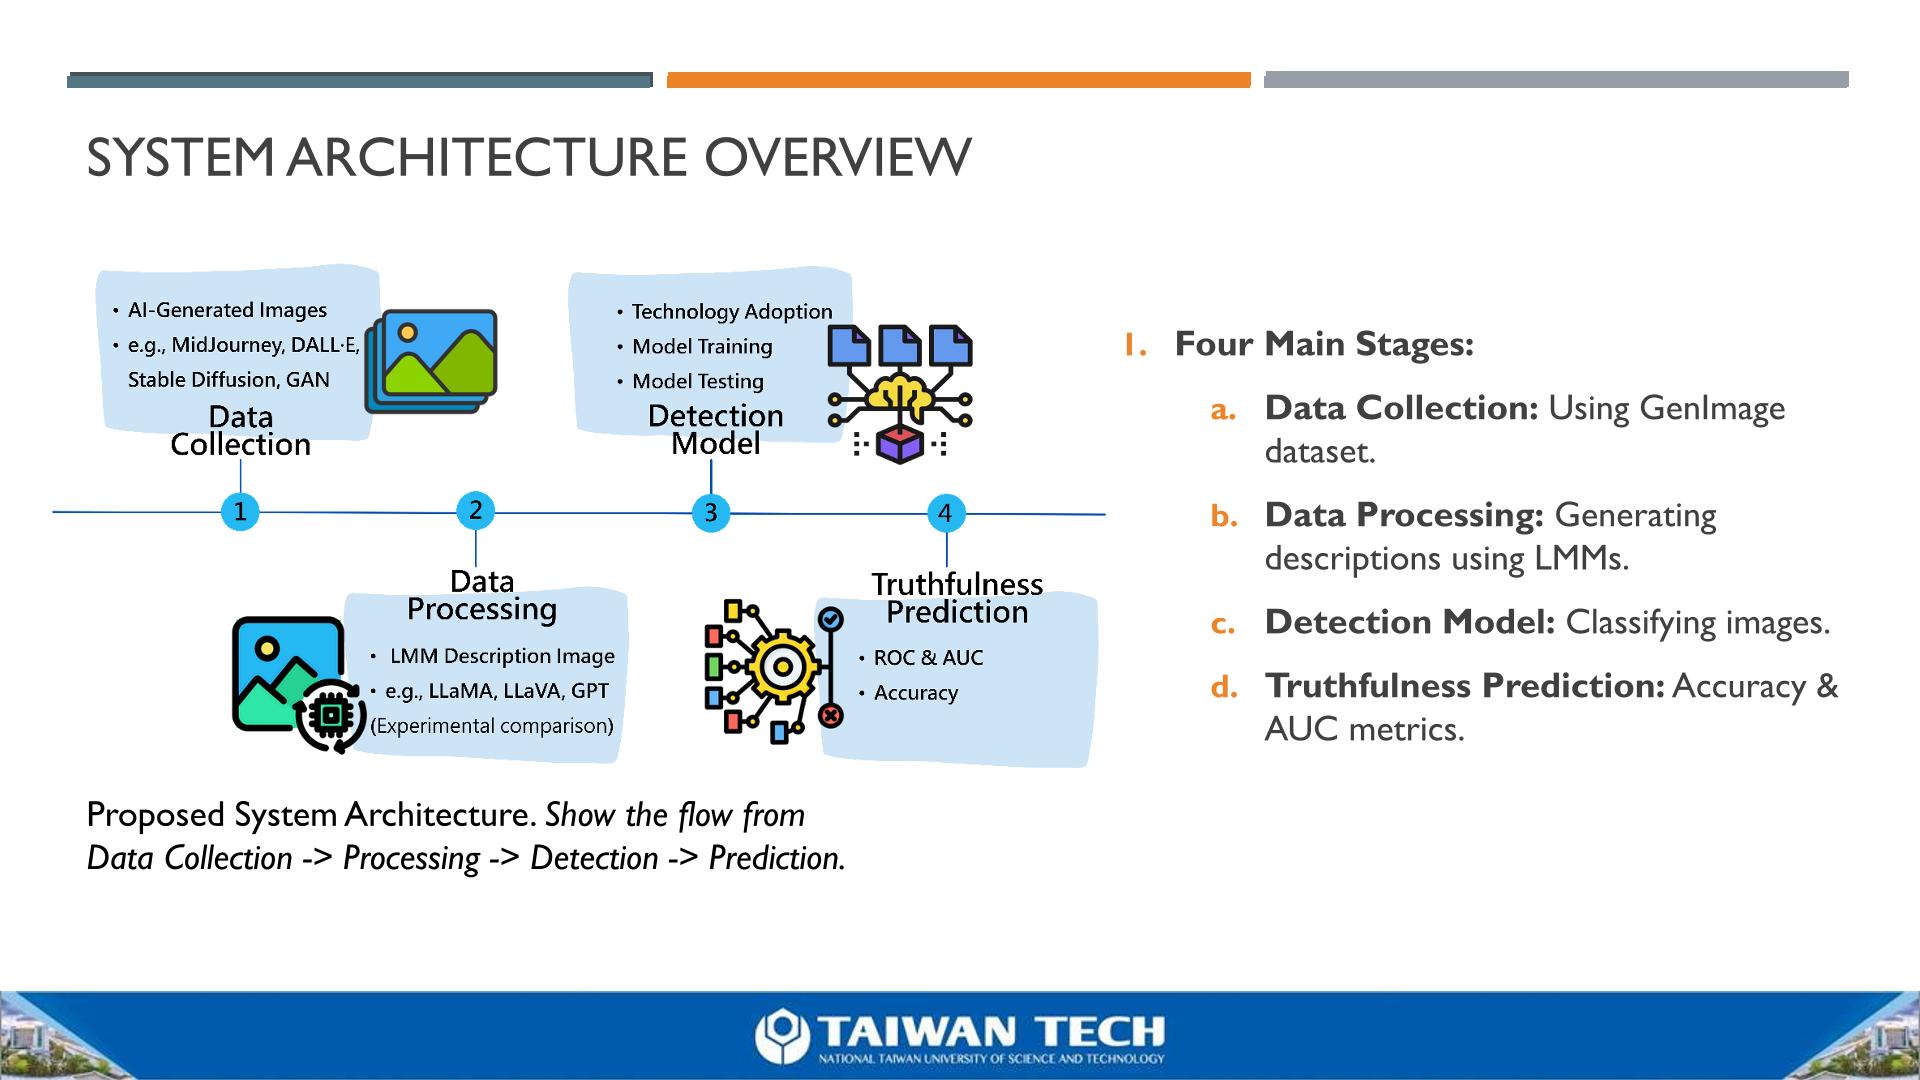
The GIDLMM system architecture consists of four distinct stages as illustrated in Figure 3.1 . First, the Data Collection stage utilizes the GenImage dataset. Second, the Data Processing stage enhances CLIPs detection capabilities by employing Large Multimodal Models, such as LLaMA and ChatGPT, to generate detailed image descriptions . Third, the Detection Model is trained to classify images utilizing these enhanced features. Finally, the Truthfulness Prediction stage assesses system performance using Accuracy and AUC metrics . |
 IEEE/ICACT20260070 Slide.06
[Big Slide]