 |
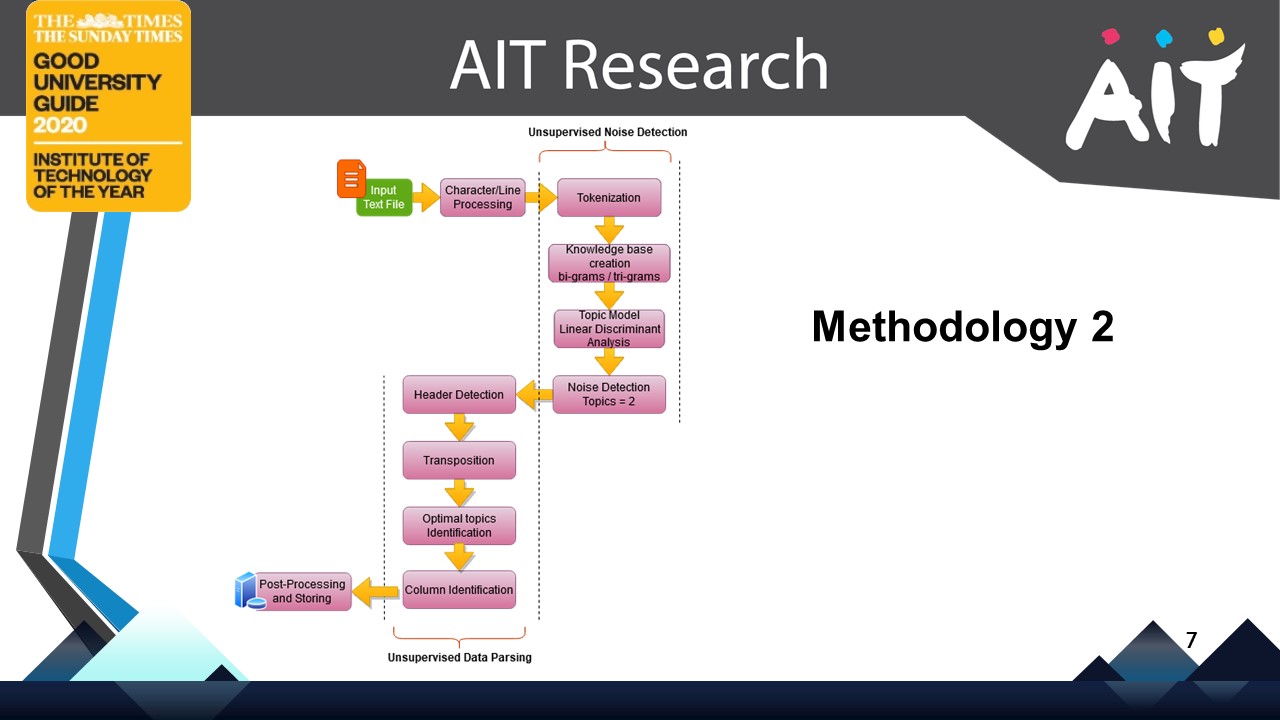
We also implemented a novel method using topic modeling algorithm shown in this figure. We pass the input file and split each line with whitespace as a separator to generate a token. We then use the tokens to transform the contiguous sequence of texts using n-grams. grouping words into bi-grams and tri-grams and creating a dictionary of words. Linear Discriminant Analysis is used to create a topic model with maximum topics set to three so that the model only classifies lines into two topics; Noise, Data, and Header. We filter out the noise label and split columns from data and header lines using whitespace distribution and meta scores similar to the previous approach. We then transpose the generated rows and columns of data and create another LDA topic model. We then compute the coherence scores to compute the best value of topics that are then used as column lengths. After choosing the best value k, we use that model to identify columns and then append them to rows to create a structured file format. |
 IEEE/ICACT20210237 Slide.07
[Big Slide]
[YouTube]