 |
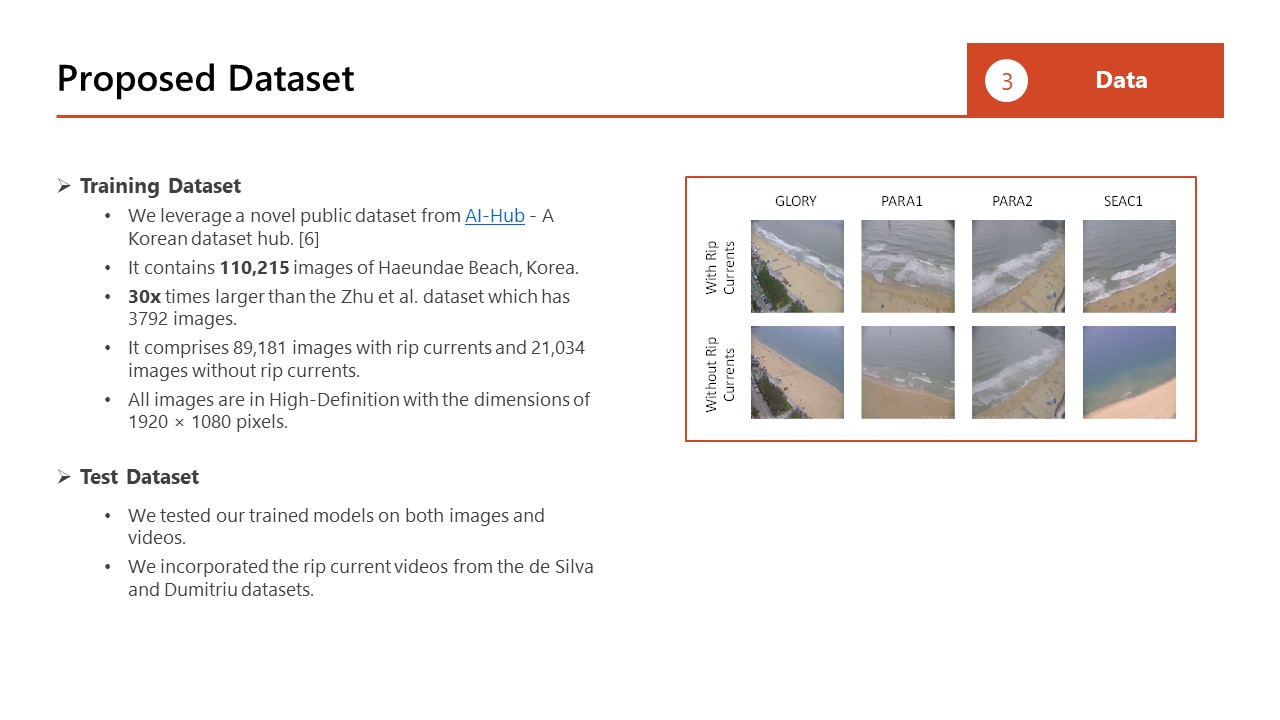
Our proposed training dataset has been leveraged from a public dataset from AI-Hub - A Korean dataset hub. It contains 110,215 images of Haeundae Beach, Korea. It is 30x times larger than the Zhu et al. dataset which has 3792 images. It comprises 89,181 images with rip currents and 21,034 images without rip currents. All these images are in High-Definition with 1920 Ąż 1080 pixels. And we tested our trained models on both images and videos.
We incorporated the rip current videos from the de Silva and Dumitriu datasets.
|
 IEEE/ICACT20240312 Slide.07
[Big Slide]