 |
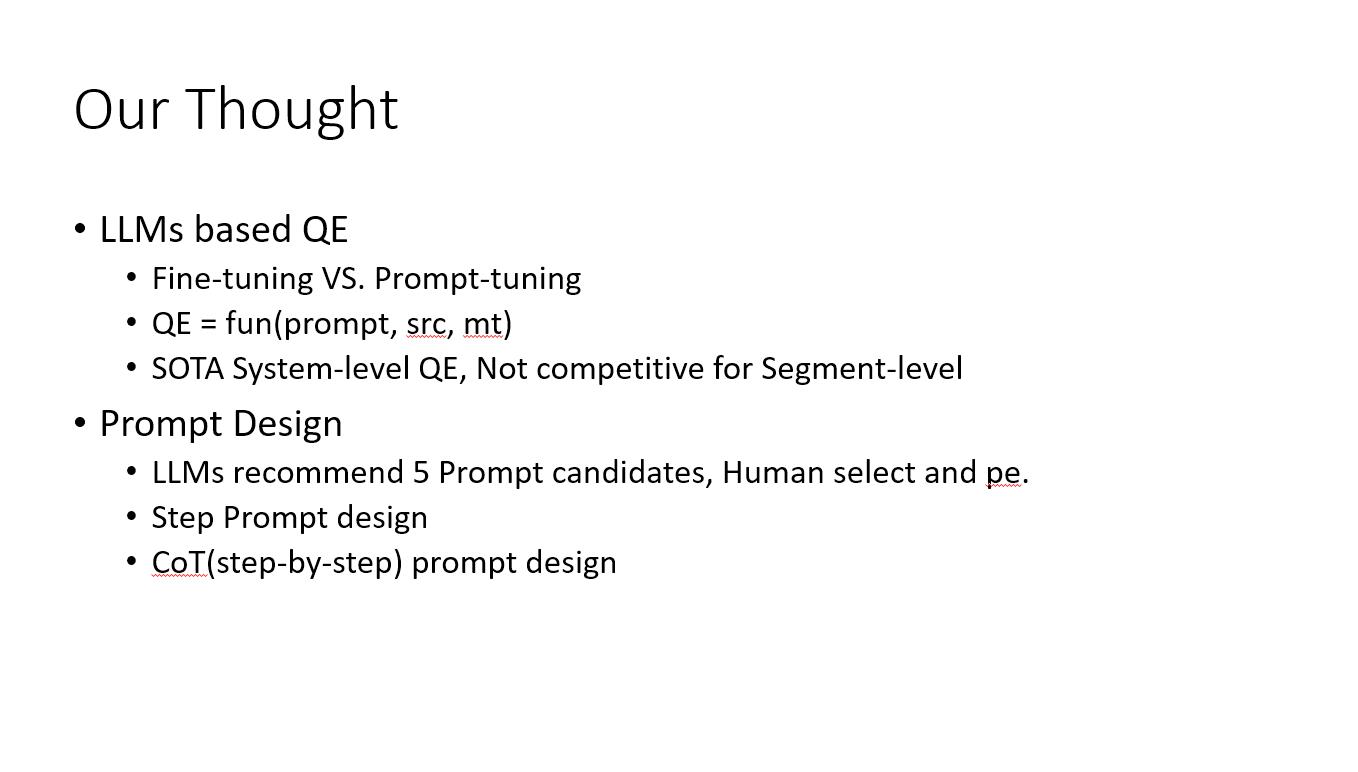
Recently, prompt-tuning LLMs has shown promise as an alternative to full model fine-tuning for machine translation QE. Formally, LLM-based QE is represented as f(prompt, src, mt), adding a prompt template string to frame the task.
While prompted LLMs achieve state-of-the-art performance for system-level QE, segment-level QE remains an open challenge.
Effective prompt engineering is key to success. We propose having LLMs recommend candidate prompts for the QE task, with humans reviewing and selecting the best prompt.
We further explore chain-of-thought (CoT) step-by-step prompting to trace model reasoning for segment-level scores. CoT explanations also aim to increase model interpretability compared to current approaches.
In summary, while prompt-tuned LLM evaluators set a new state-of-the-art for system-level MT quality estimation, segment-level performance remains to be improved. Advances in knowledge prompting and CoT explainability offer promising directions toward human-competitive fine-grained quality assessment using large language models. |
 IEEE/ICACT20240321 Slide.07
[Big Slide]