 |
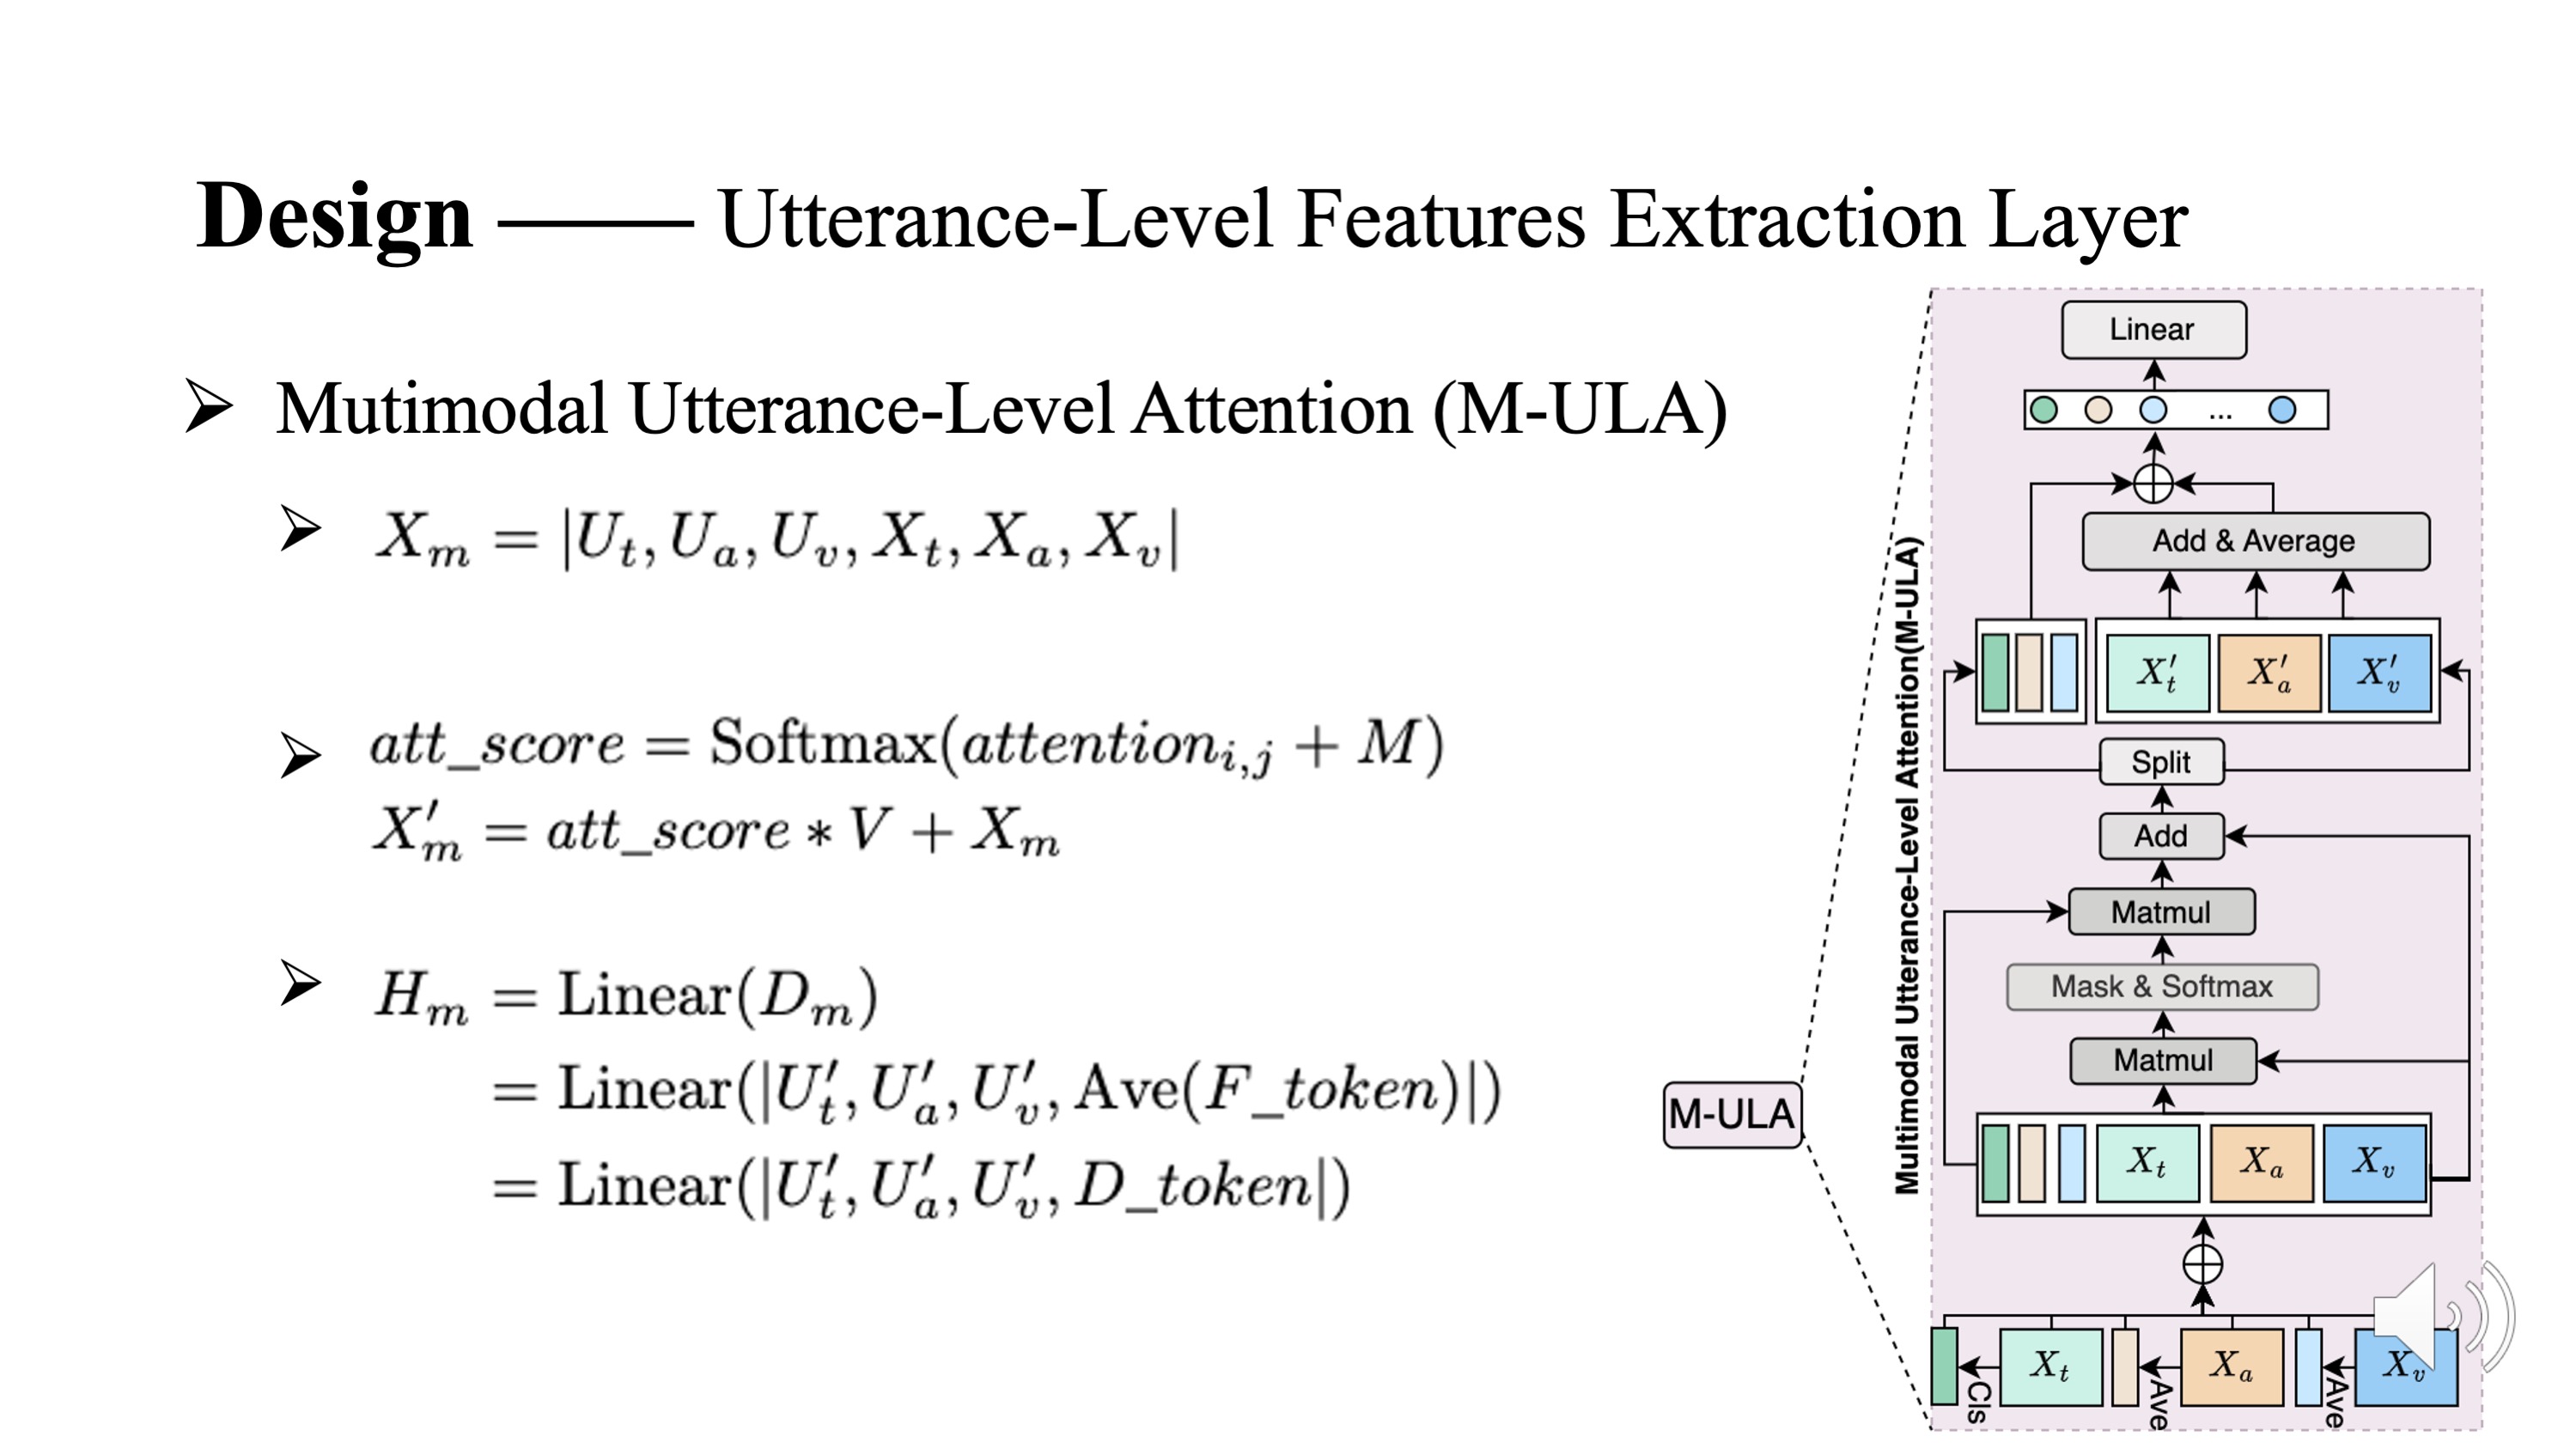
Let¡®s take a closer look at how multimodal feature extraction module works.
We take three token-level unimodal features as input and gain their utterance-level features represent, and concatenate these six features to obtain the fused features.
Then we use the attention mechanism to obtain attention score and updated multimodal feature $X_{m}^{\prime}$
Eventually, we split the interactive features into two sets and passing through several linear layers, we obtain the multimodal features representation.
|
 IEEE/ICACT20240342 Slide.07
[Big Slide]