 |
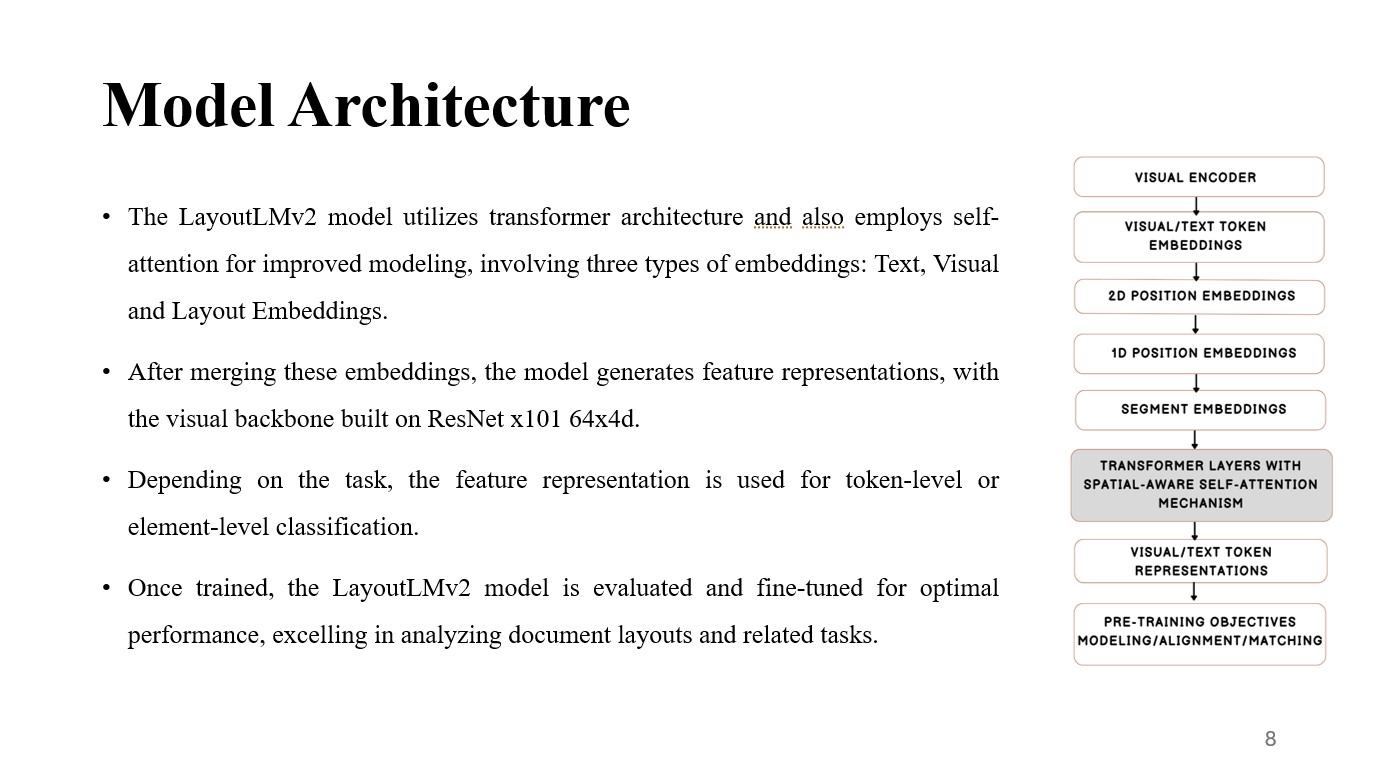
The LayoutLMv2 model, which involves three different forms of embeddings—text, visual, and layout—uses transformer architecture in addition to self-attention for enhanced modeling.
Following the merging of these embeddings, the model produces feature representations, with ResNet x101 64x4d serving as the visual foundation.
The feature representation is used for either element-level or token-level categorization, depending on the job.
The LayoutLMv2 model, which is excellent at evaluating document layouts and associated tasks, is assessed after training and adjusted for maximum performance. |
 IEEE/ICACT20240477 Slide.07
[Big Slide]
[YouTube]