 IEEE/ICACT20260046 Slide.07
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20260046 Slide.07
[Big Slide]
| Oral Presentation |
|
|
|
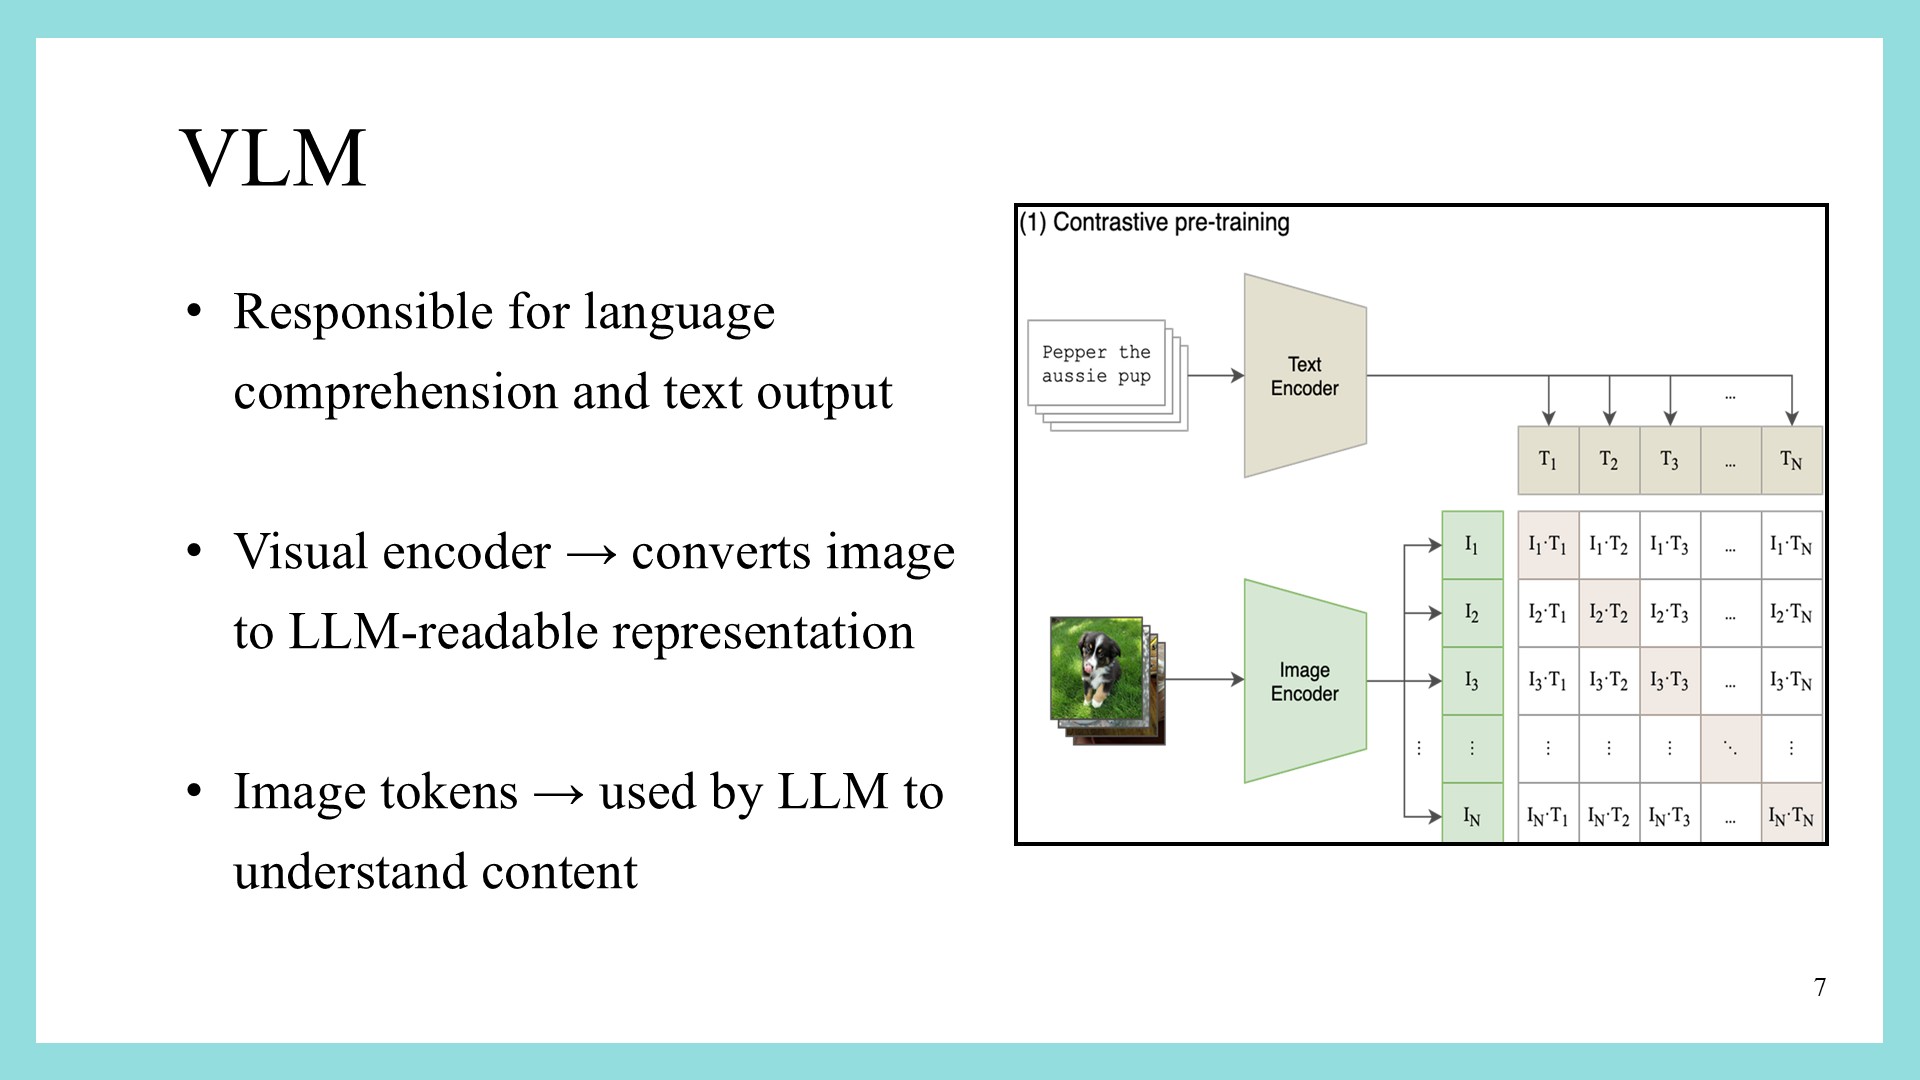
The Vision Language Model reads the detected objects with YOLO and creates a text description. And the visual encoder converts the image into LLM. In the last, the language model then uses these LLM to write meaningful sentences. This is how we turn image content into text. About to defend different detected objects¡¯ weight question. | |
| [Go to Next Slide] |