 IEEE/ICACT20260118 Slide.07
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20260118 Slide.07
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
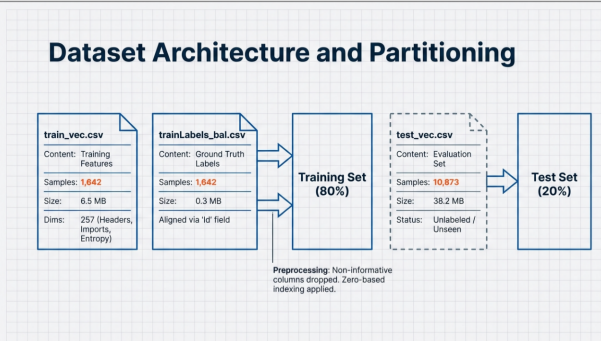
Here is how we partitioned the data. We used a standard 80-20 split. The training set includes labeled ground-truth samples, while the evaluation set contains nearly 11,000 unseen samples. We also applied zero-based indexing and dropped non-informative columns during preprocessing. | |
| [Go to Next Slide] |