 |
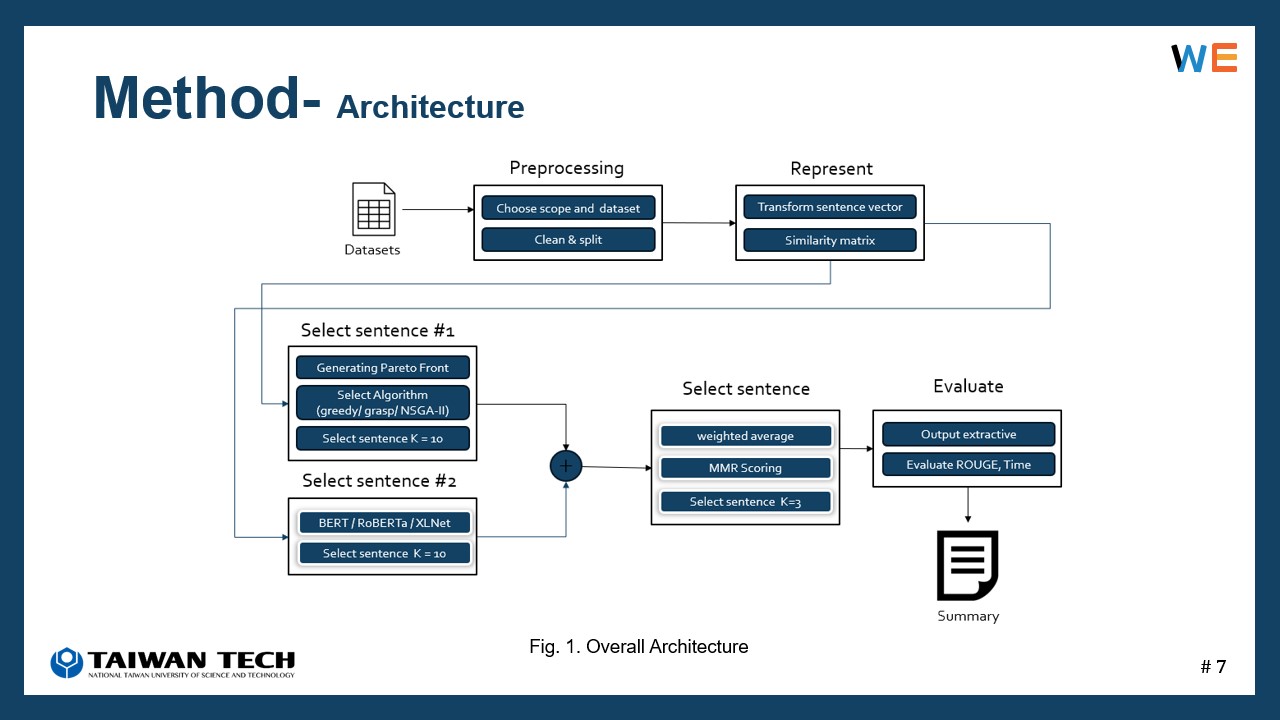
This figure shows the overall architecture of our approach.
Our system architecture can be divided into two major stages. The first stage is data preprocessing. We clean the article, convert everything to lowercase, and split it into individual sentences to form the candidate pool.
For these candidate sentences, we compute several features, such as TF-ISF, sentence length, position score, and the similarity matrix.
The second stage forms the core of our method, which focuses on generating and selecting candidate sentences.
In this stage, we use two parallel branches.
One branch is based on meta-heuristic algorithms, and the other branch uses language-model embeddings.
Each branch selects the top ten candidate sentences, and we then merge the two sets.
Finally, we apply MMR to balance relevance to the document and diversity among sentences.
From the merged candidate set, we select three sentences as the final summary. |
 IEEE/ICACT20260145 Slide.07
[Big Slide]