 |
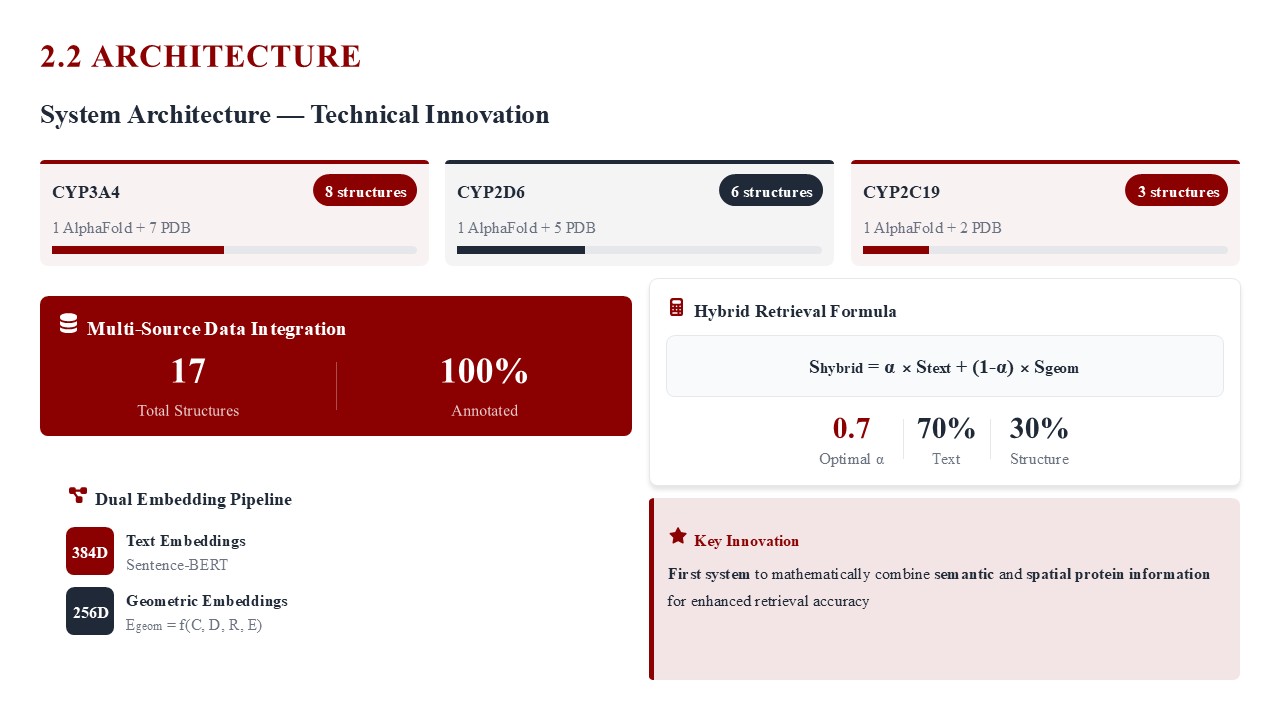
Let me walk you through our technical infrastructure. Our software stack is built on Python 3.9 with scientific computing libraries including NumPy and SciPy for numerical computations, BioPython for protein structure analysis, and PyTorch for deep learning components. For data management, we handle structure files in PDB and mmCIF formats, use Pinecone as our vector database for embeddings, and PostgreSQL for metadata storage. Performance optimization is achieved through GPU acceleration using CUDA 11.8 for embedding generation, parallel processing with 16-core CPU utilization, and efficient memory management through chunk streaming. Our evaluation framework includes 5-fold stratified cross-validation splits, metrics including NDCG@k, MRR, and Recall@k, and statistical testing using the Wilcoxon signed-rank test. The pipeline workflow consists of six stages: preprocessing, embedding generation, indexing, query processing, retrieval, and finally LLM augmentation for natural language responses. |
 IEEE/ICACT20260263 Slide.07
[Big Slide]