 |
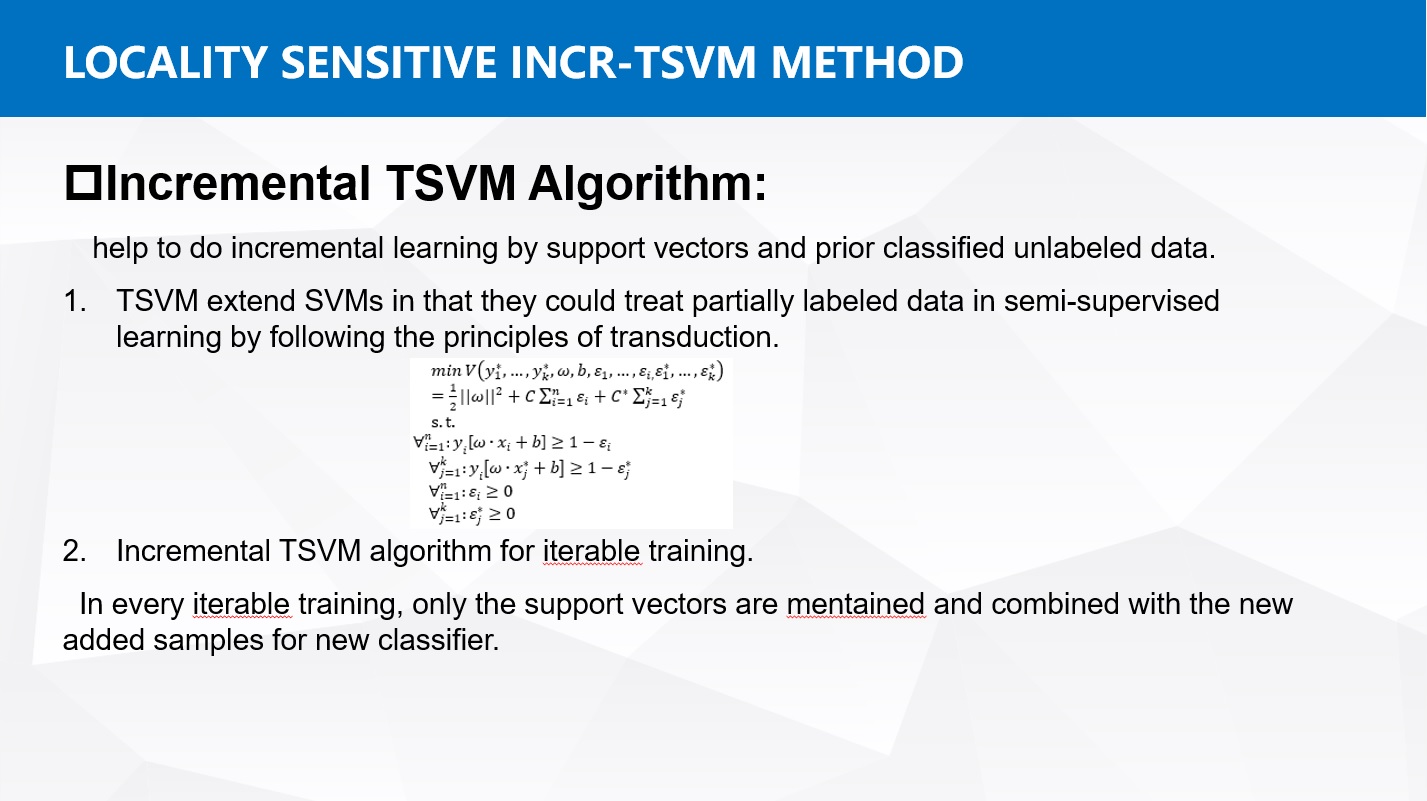
TSVM extend SVMs in that they could treat partially labeled data in semi-supervised learning by following the principles of transduction. The key idea of TSVM is that it can be treated as seeking an optimal solution in given labeled dataset and unlabeled dataset. But there are two disadvantages of transduction method. The one is that TSVM builds no predictive model. And the other one is if a previously unknown point is added to the set, the entire transductive algorithm would need to be repeated with all of the points in order to predict a label. After investigation, we find the set of support vectors can fully describe the features of the whole training set, learning in the set of support vectors is equivalent to learning in whole training set. In every iterable training, only the support vectors are mentained and combined with the new added samples for new classifier. With this, TSVM has the capacity of incremental learning. |
 IEEE/ICACT20210143 Slide.08
[Big Slide]