 |
We introduce knowledge-prompted evaluation (KPE) metrics for machine translation quality estimation, including both single-step and chain-of-thought (CoT) variants.
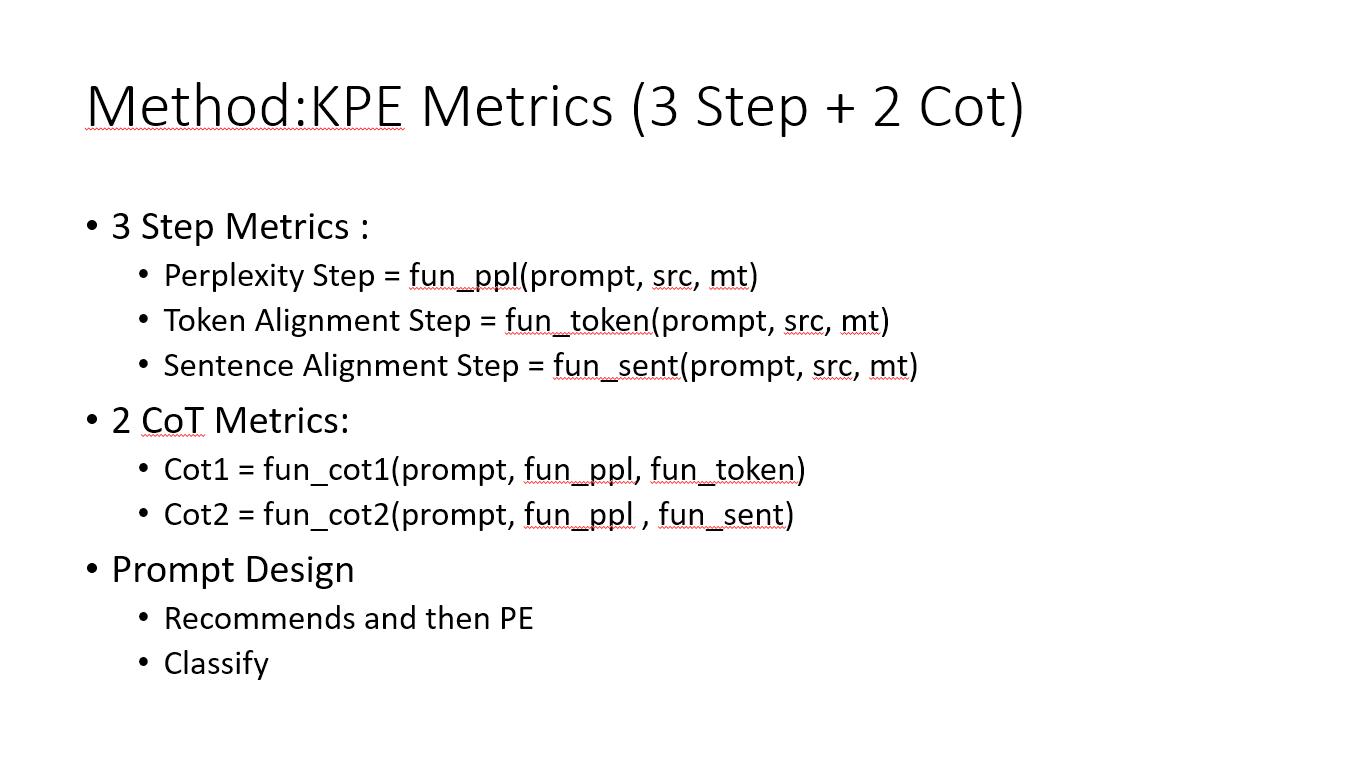
Single-step KPE metrics evaluate:
Perplexity: fun_ppl(prompt, src, mt)
Token alignment: fun_token(prompt, src, mt)
Sentence alignment: fun_sent(prompt, src, mt)
The two CoT metrics trace model reasoning over multiple steps:
Cot1: fun_cot1(prompt, fun_ppl, fun_token)
Cot2: fun_cot2(prompt, fun_ppl, fun_sent)
We generate candidate prompts using LLM recommendations then perform human prompt engineering (PE) to select optimal prompts.
Finally, we classify mt quality based on the KPE scores. We compare rating on both 3-class and 5-class scales to evaluate granularity.
In summary, we propose a systematic framework to evaluate combinations of knowledge prompting strategies and CoT explainability for fine-grained machine translation quality estimation using large pretrained language models. |
 IEEE/ICACT20240321 Slide.08
[Big Slide]