 |
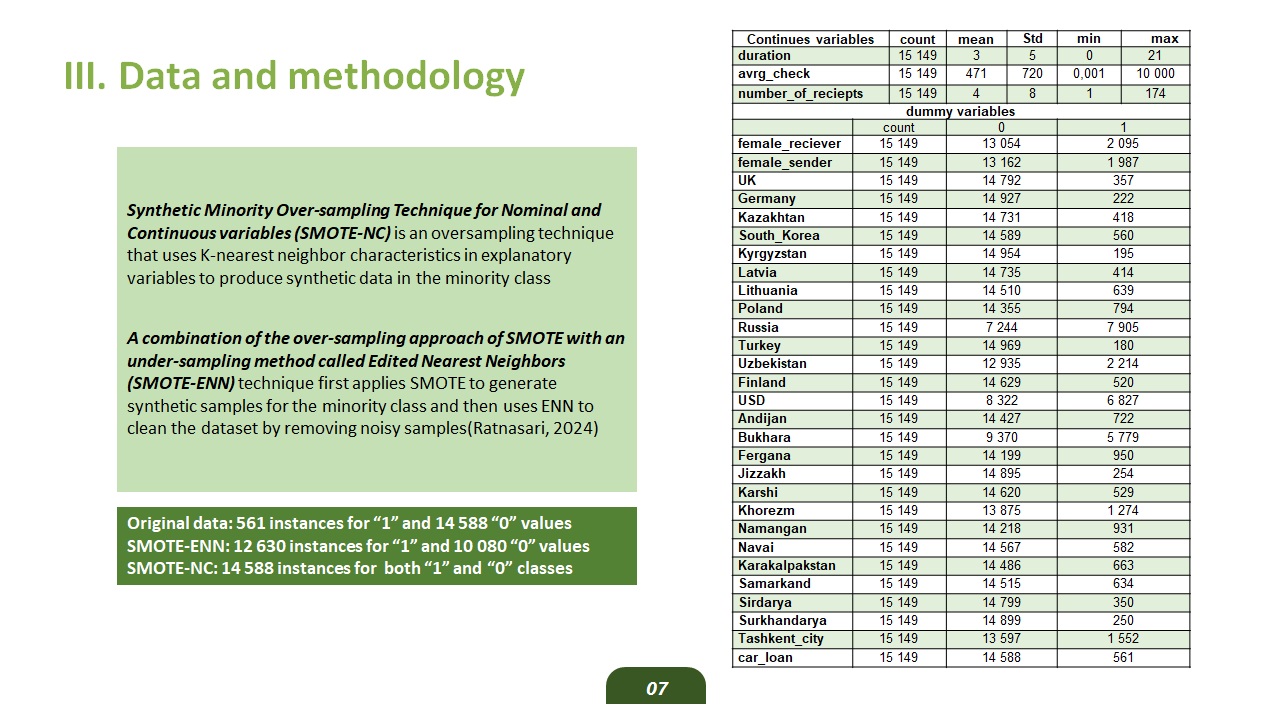
Our dataset has three continuous variables and twenty-nine dummy variables. Duration is a continuous variable. It is measured in months and shows the time passed between the first and last receipts of remittances. The minimum value of zero indicates that the client received a single remittance. The maximum duration is equal to 21 months. On average, recipients receive remittances over three months. Avg_check represents the average check amount per recipient in US dollars. The values of avrg_check range from 0.001 to 10,000 USD, with a mean of 471 USD. The number of receipts reflects the total quantity of remittances per recipient, varying from one to 174. On average, there are four remittances per recipient.
Female_reciever and female_sender indicate the gender of the recipient and sender respectively. Where a value of 1 signifies a female, and 0 represents a male. Remittances originating from 12 primary countries are represented by dummy variables (e.g., UK, Germany, Russia), which account for 95% of all the remittances to Uzbekistan. Remittances from other countries are grouped into a single variable, which we omit as required for dummy variable usage. In Uzbekistan, remittances can be sent in US dollars and Uzbek soums. USD variable indicates the currency of remittances, where 1 represents USD and 0 represents Uzbek soums. Uzbekistan has thirteen regions. Twelve regions are used to represent the originality of the recipient and one region is omitted.
Our target variable, car_loan is a dummy variable equal to 1 when the recipient has a car loan and 0 otherwise.
Of the receipts, 561 adopted car loans. This means we have an imbalanced dataset. Imbalanced data is a common challenge in classifier learning, as it can be biased toward the majority class. Balancing the dataset is essential to improve model performance. We applied the SMOTENC technique to oversample the minority class. This technique allows oversampling data containing both categorical and continuous variables. After oversampling SMOTE-ENN dataset contains 12 630 instances of the positive class (1) and 10 080 instances of the negative class (0). SMOTE-NC dataset 14 588 instances of positive and negative classes.
|
 IEEE/ICACT20250136 Slide.08
[Big Slide]