 |
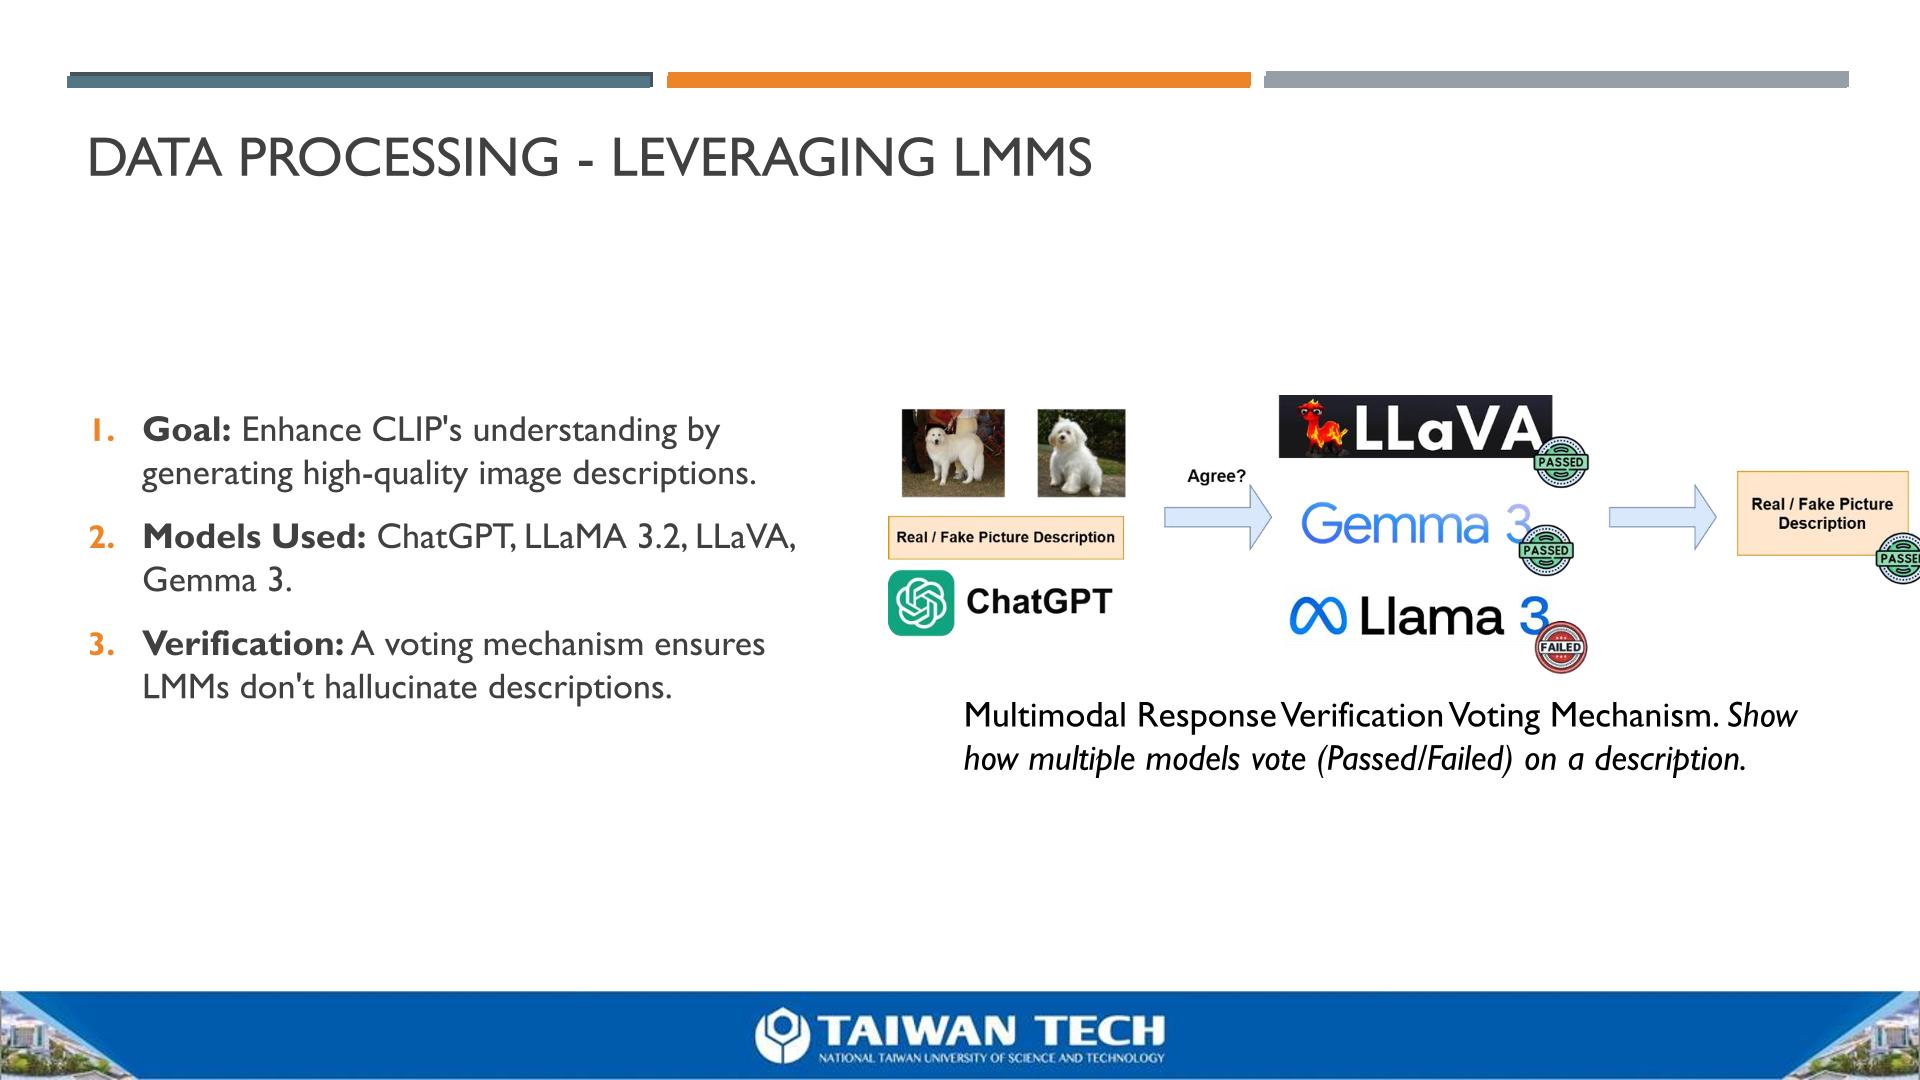
In the Data Processing stage, multiple Large Multimodal Models- including ChatGPT, LLaMA 3.2, and LLaVA- are employed to generate text descriptions for the training images. These descriptions serve as augmented data to align image and text representations within the CLIP feature space . To ensure reliability and prevent hallucinations, a voting mechanism is implemented where a description generated by one model is verified by three others . Only descriptions passing this majority vote are utilized, ensuring the training data remains factual and consistent . |
 IEEE/ICACT20260070 Slide.08
[Big Slide]