 |
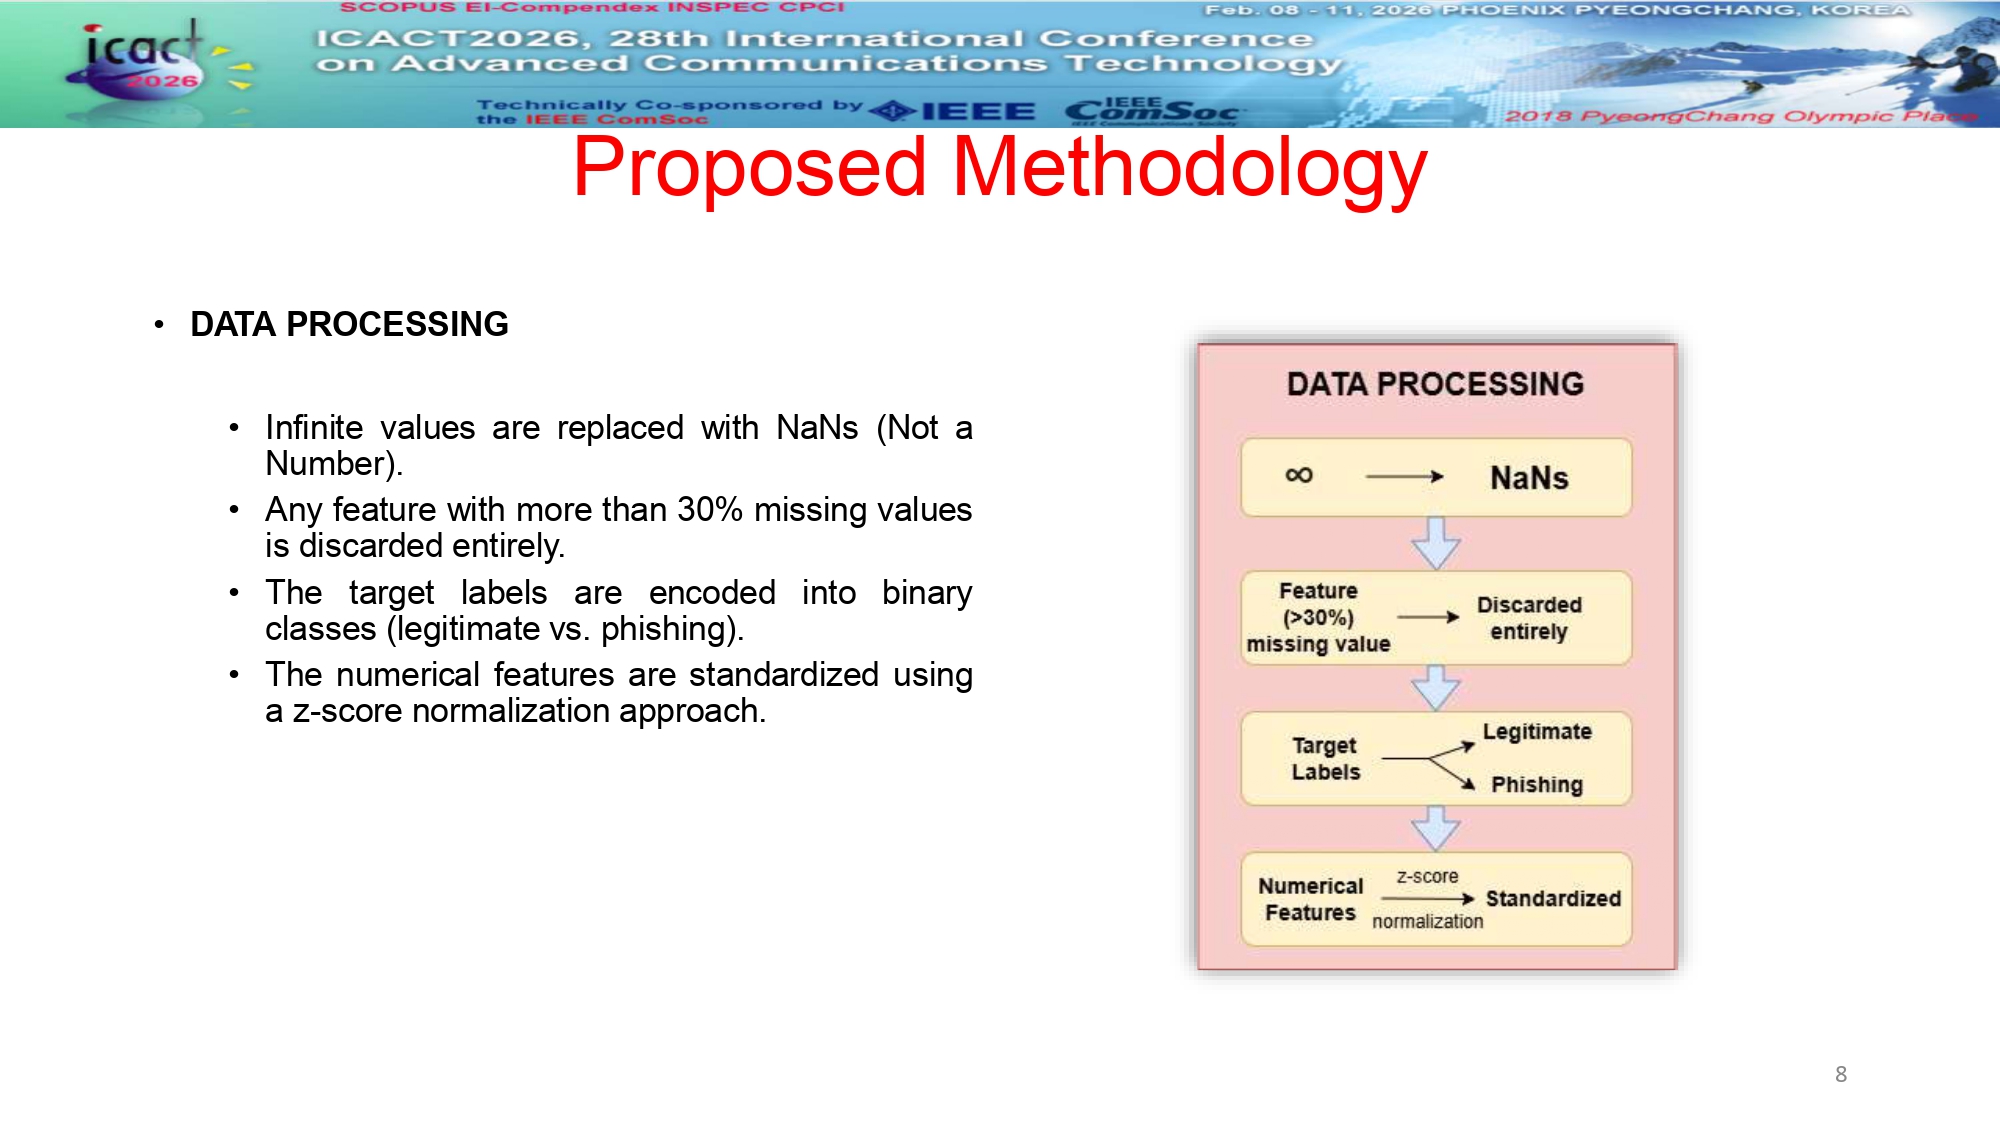
Before we could feed our data into the complex hybrid architecture, we performed meticulous preprocessing to maintain absolute numerical integrity. As you can see in our workflow, we first addressed mathematical inconsistencies by replacing infinite values with NaNs and entirely discarding any features with more than 30% missing data.
Next, we ensured our targets were machine-ready by encoding them into binary classes: legitimate versus phishing. Finally, to ensure no single feature dominated the model based on its scale, we standardized all numerical features using a z-score normalization approach. This rigorous cleaning process ensures that our BiLSTM and SVM models are training on the most informative, standardized data possible, which is the first step in achieving our high accuracy results. |
 IEEE/ICACT20260103 Slide.08
[Big Slide]
[YouTube]