 |
Now, let me explain how we evaluate each sentence.
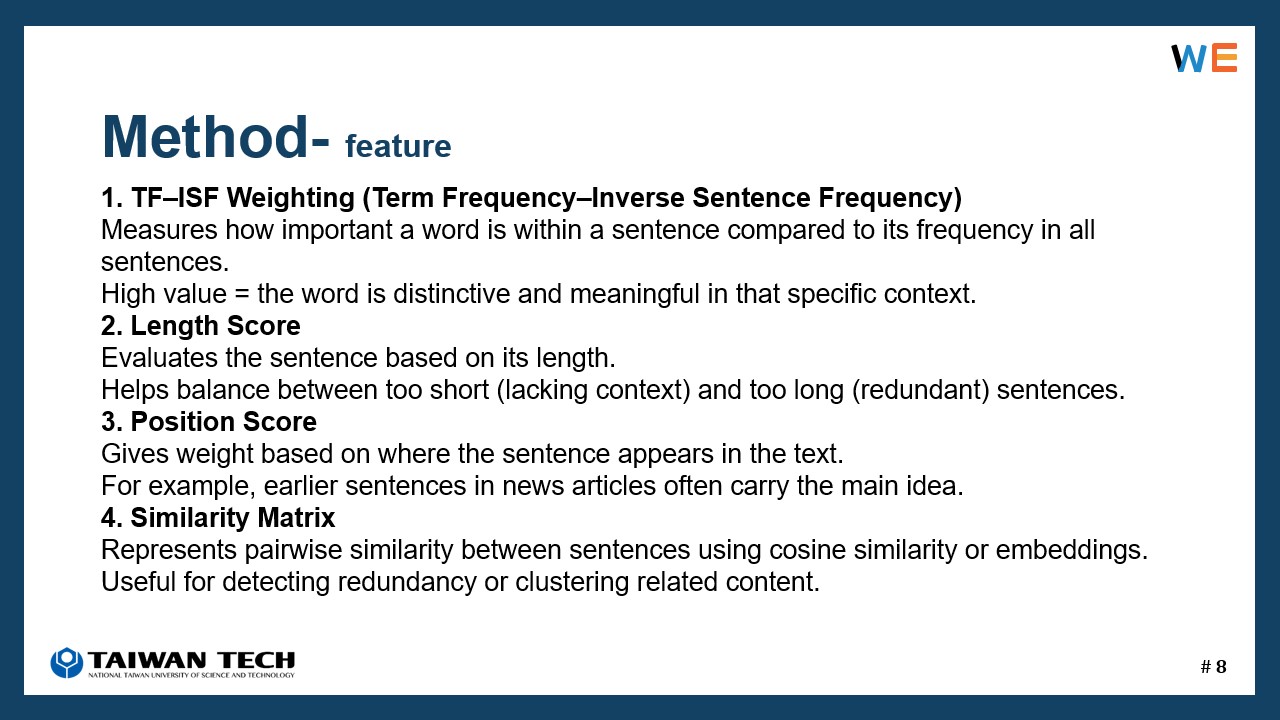
The first one is TF-ISF. It helps us identify words that are important in a sentence, but not common across the entire document.
The second feature is sentence length. Very short sentences usually lack context, while very long ones tend to be redundant.
The third feature is sentence position. This is especially useful for news articles, where key information often appears early.
The final feature is the similarity matrix. It helps us detect redundancy and avoid selecting sentences that are too similar.
Together, these features provide a simple but effective way to capture the key content of an article.
So instead of using heavy models at this stage, we rely on these simple signals to guide sentence selection. |
 IEEE/ICACT20260145 Slide.08
[Big Slide]