 |
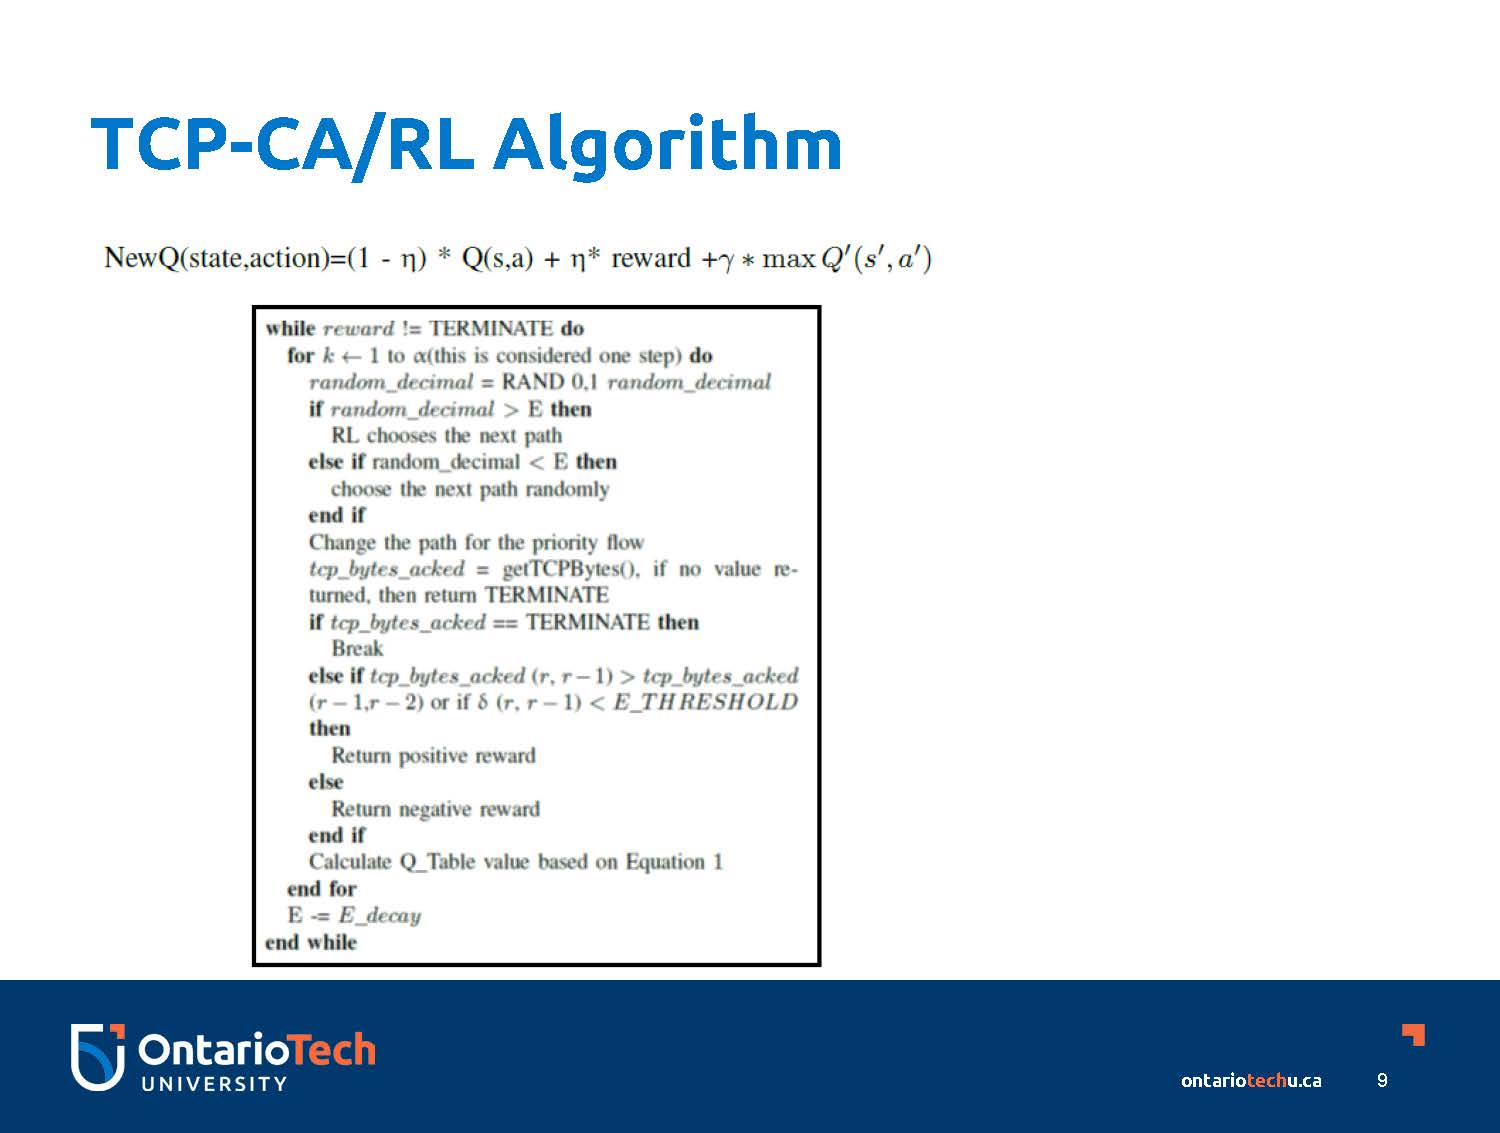
Once the reward is calculated, it is fed into Equation (1)
which is used to calculate how ¡¯good¡¯ of a decision was made
by the RL algorithm. The value that is calculated is known
as the Q-Table value for that particular state/action transition
(e.g. going from path x to path y )which is stored in a matrix,
with the best decision having the highest value. After the for
loop completes iteration as defined by , then E is decreased
by the variable E THRESHOLD so in the next iteration,
there is a greater chance that TCP-CA/RL will select the
path, eventually having the algorithm adopt a greedy model,
selecting the Q-value at each state transition that has yielded
the highest reward based on past iterations.
|
 IEEE/ICACT20210131 Slide.09
[Big Slide]