 |
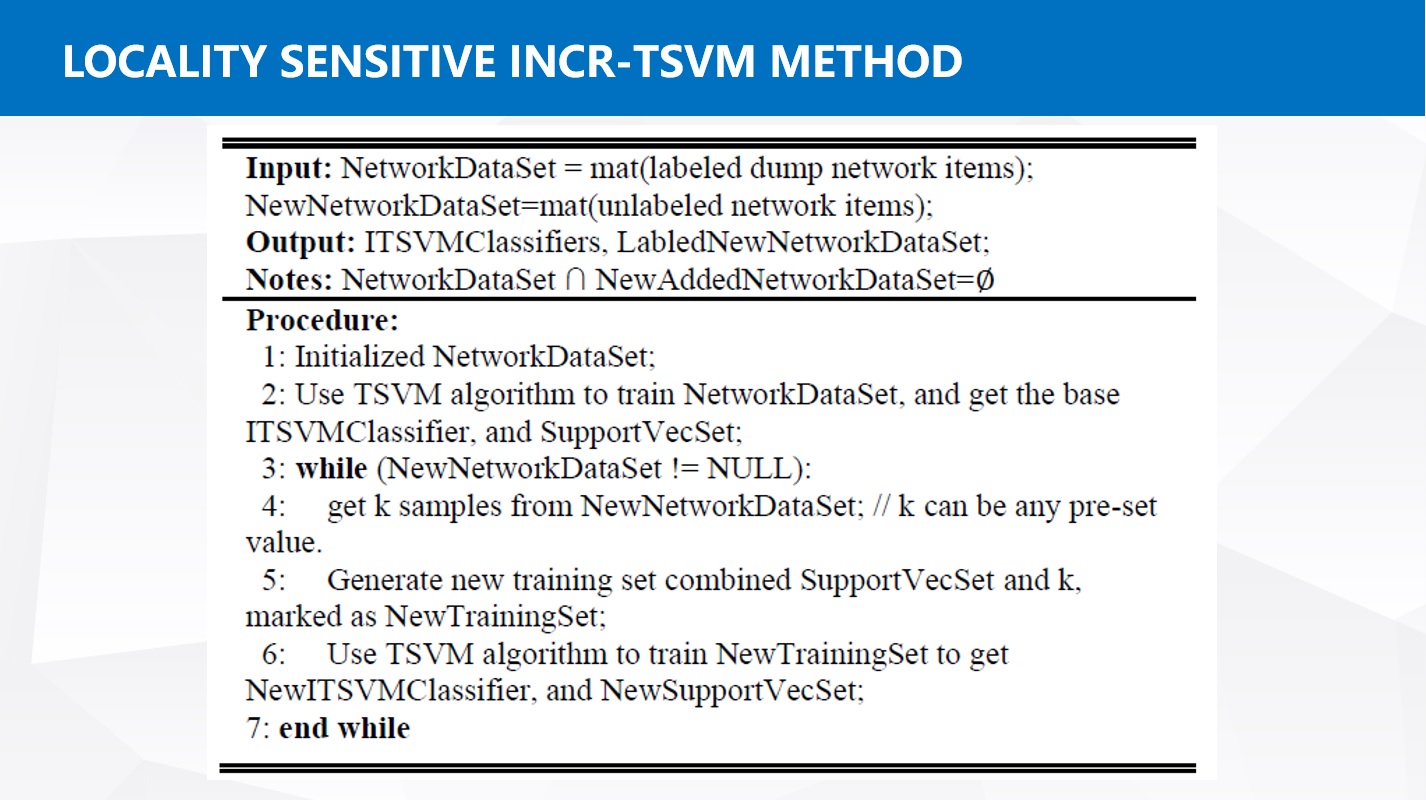
In order to obtain the optimal solution, before the algorithm, we should set well-tuned C and C* by historical experiment, and to learn the initialized SVM classifier based on labeled samples through induction method. The second step is to use this SVM classifier to classify all unlabeled samples, and mark only pairwise labels of positive and negative samples in support vectors nearby. The last step is to re-train SVM based on new chosen samples and labeled samples. Training procedure is repeated between step two and three, until all unlabeled samples have their own classification. |
 IEEE/ICACT20210143 Slide.09
[Big Slide]