 IEEE/ICACT20210237 Slide.09
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20210237 Slide.09
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
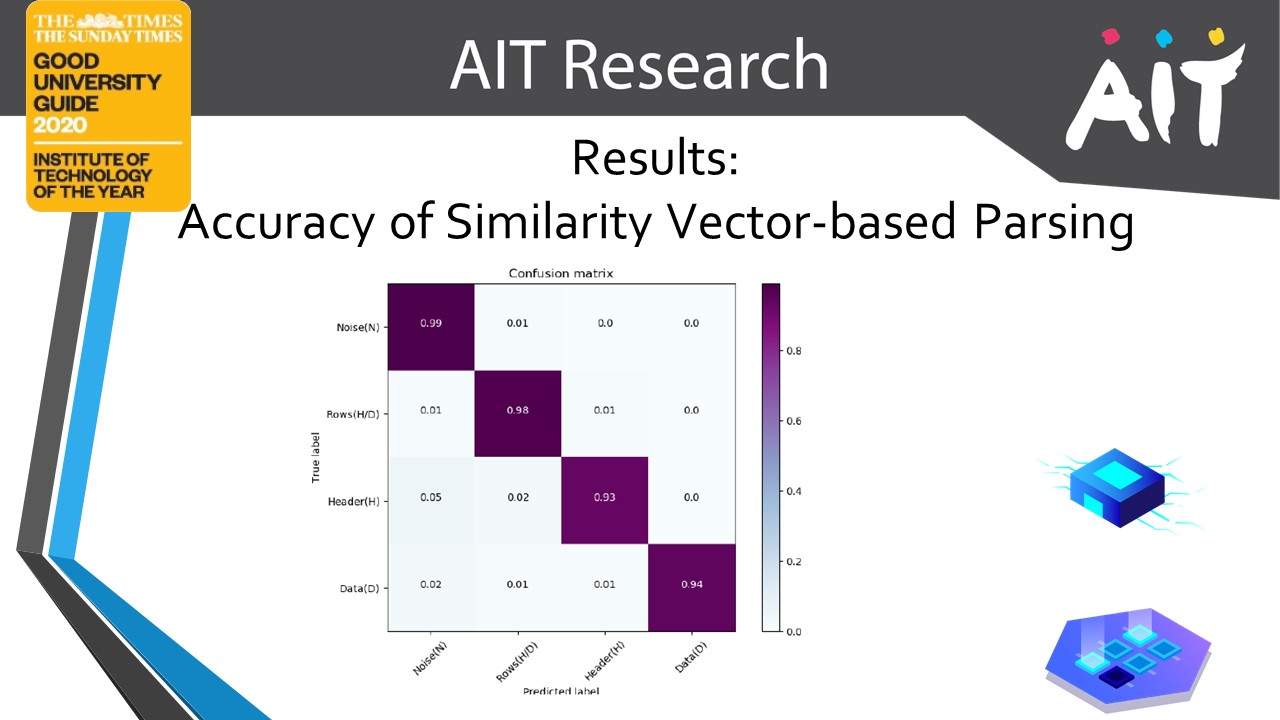
The accuracy of the method that uses Levenshtein distance to calculate similarity and Agglomerative clustering for filtering and parsing is presented in this figure. This method identifies noise, relevant rows, header, and data with higher accuracy, as seen in the figure. Identifying header components from data is confusing for the algorithm for some structures where the data contains similar keywords. | |
| [Go to Next Slide] |