 IEEE/ICACT20220065 Slide.09
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20220065 Slide.09
[Big Slide]
| Oral Presentation |
|
|
|
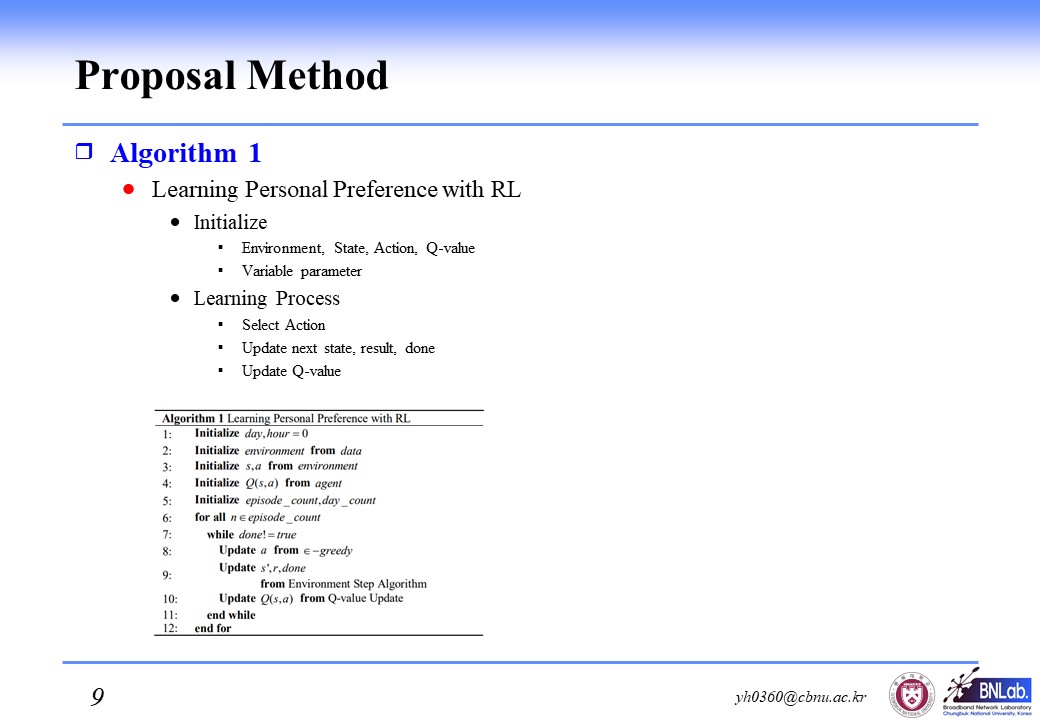
The following is an algorithm for Learning Personal Preference with RL. First, Environment, State, Action, Q-value, and Variable parameters are initialized. The learning process first selects an action and then calculates the next state, result, and done. Finally, update the Q-value. | |
| [Go to Next Slide] |