 |
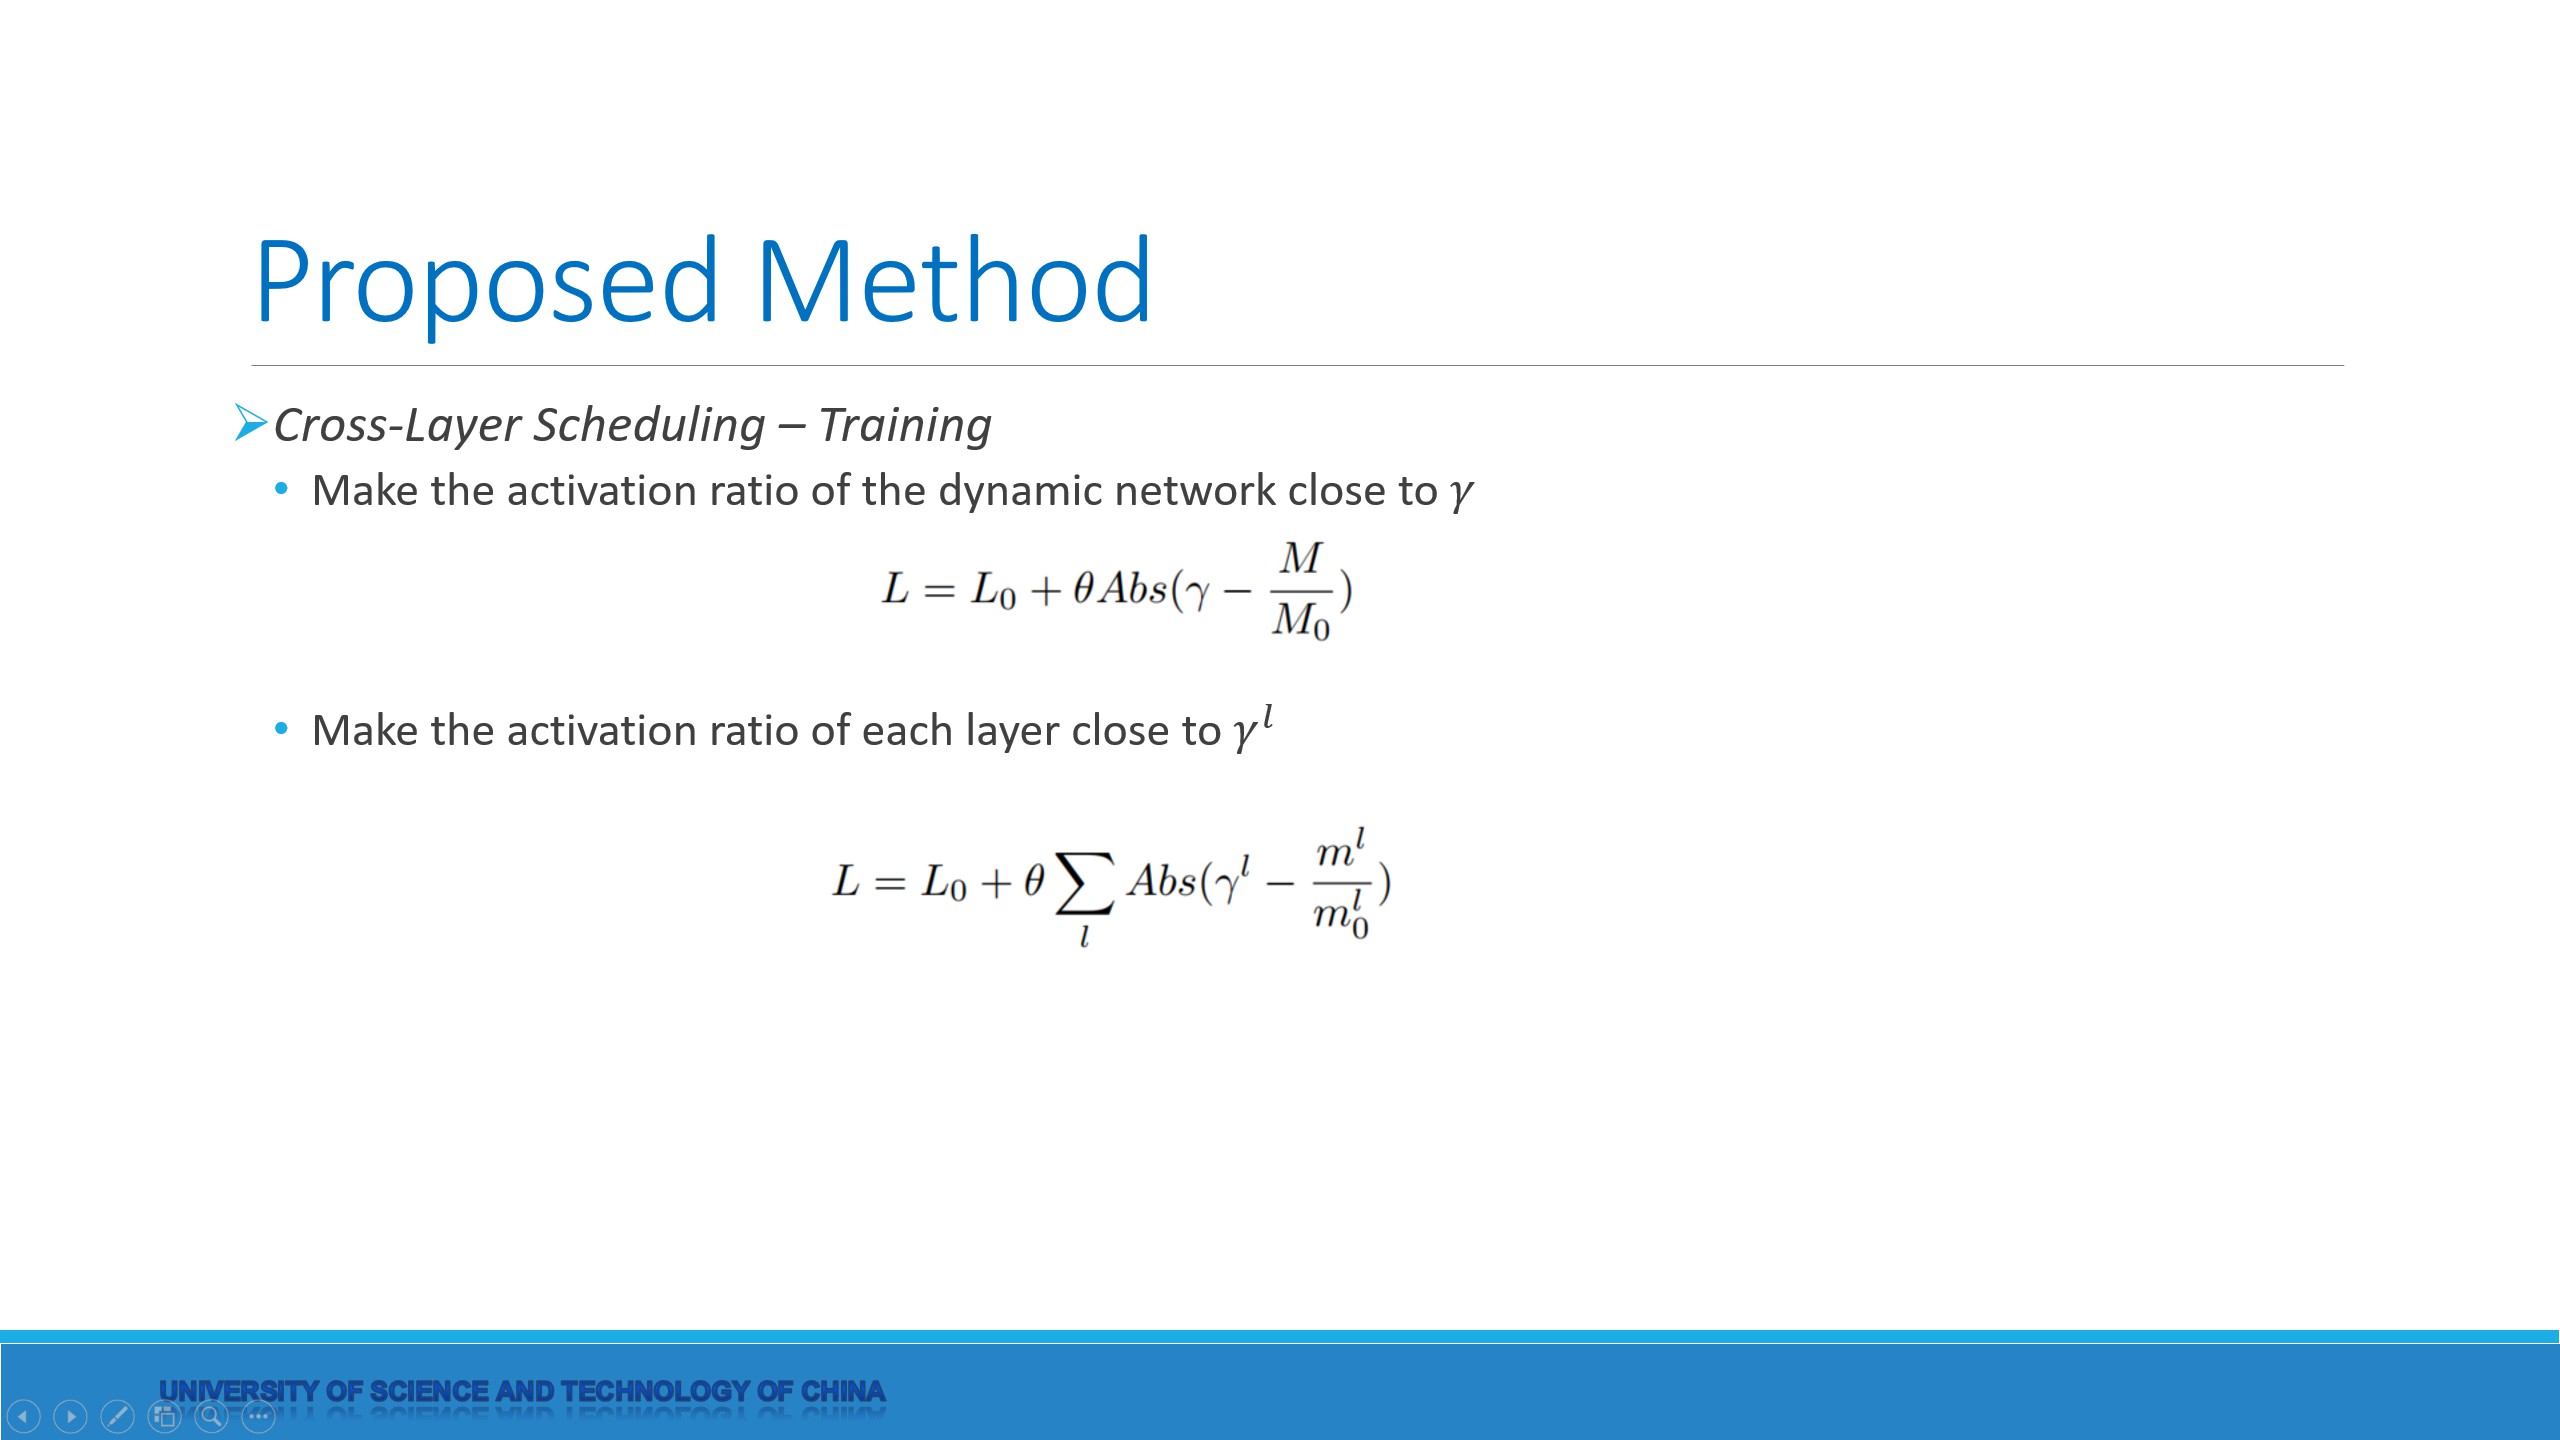
As the conventional dynamic neural network processes different samples, its network structures are very different, so it is difficult to make a static analysis and determine the fusion strategy. To facilitate analysis, we set the model activation ratio to ャ. The total computation of the static network is recorded as M_0, and the computation of each layer is recorded as m^l_0. In the training phase, we count the actual computation of each sample after layer skipping and dynamic pruning, which is recorded as M, and the actual computation of each layer is recorded as m^l. We divided the training into two steps. In the first step, we add a new item to the loss function:
where ヨ is a configurable parameter. We train the model until convergence and then obtain weights that make the overall activation ratio of the dynamic network close to ャ. In the second step, we select a batch of samples for inference, count the actual activation ratio of each layer, and average them. Then we obtain the average activation ratio of each layer ャl. The loss function is modified as follows. We train the model again. Finally, while ensuring accuracy, the activation ratio of each layer is close to the fixed value ャl.
|
 IEEE/ICACT20230038 Slide.09
[Big Slide]
[YouTube]