 |
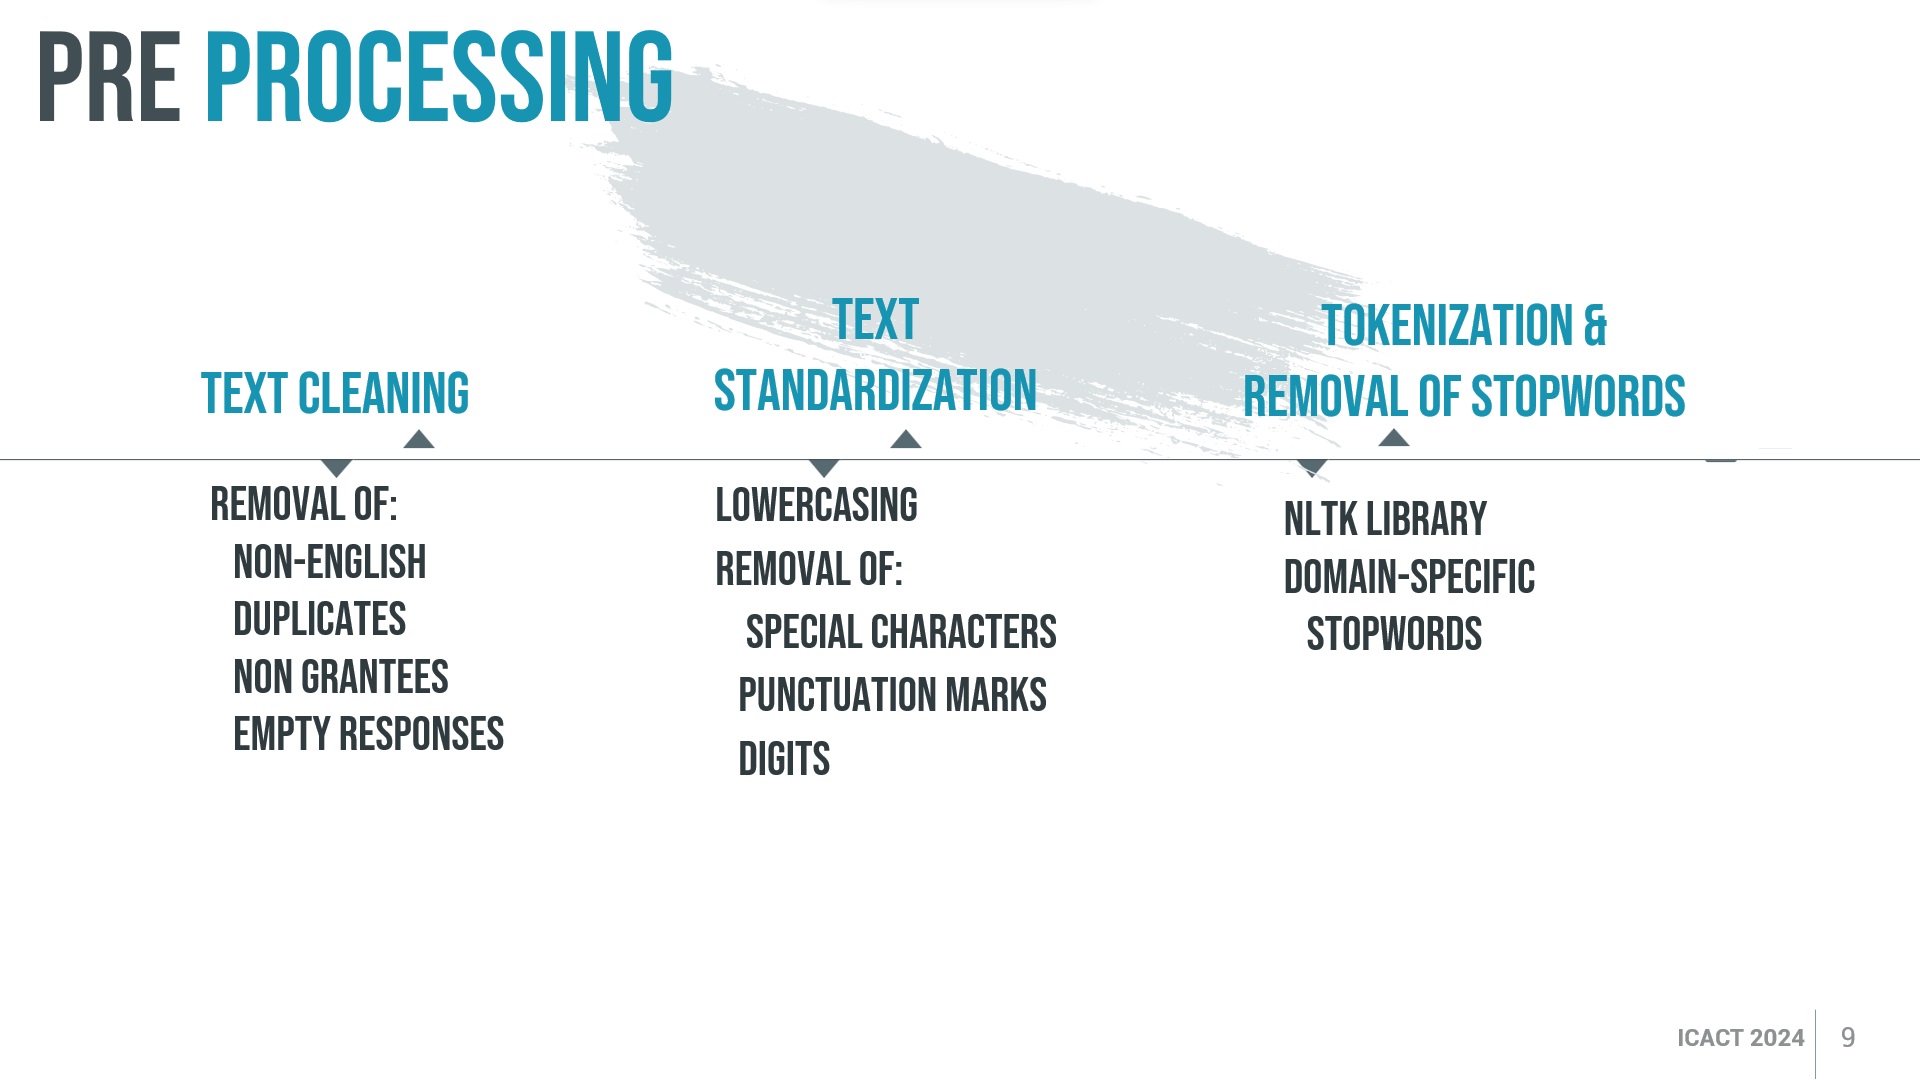
The collected responses underwent meticulous data pre-processing, involving removal of non-English, duplicate, non-grantee, and empty responses. Text was standardized by converting to lowercase and eliminating special characters, punctuation, and digits to refine textual representation, ensuring clearer analysis and reduced noise. Further steps employed the NLTK for tokenization and removed common stopwords, enhancing clarity by segmenting text into individual words and eliminating semantically limited words. Domain-specific terms like "UAQTE," "issues," "challenges," and "beneficiaries" were treated as additional stopwords to focus the text analysis and highlight key terms for more meaningful results. |
 IEEE/ICACT20240447 Slide.09
[Big Slide]