 |
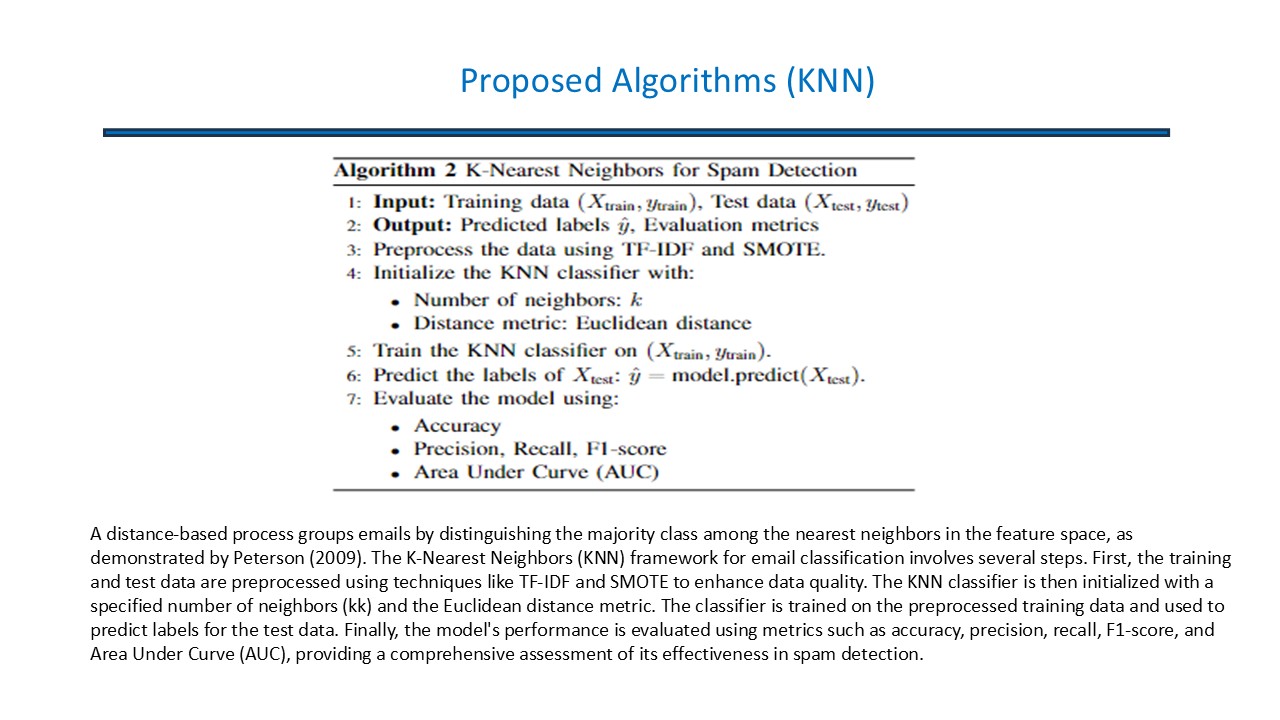
A distance-based process groups emails by distinguishing the majority class among the nearest neighbors in the feature space, as demonstrated by Peterson (2009). The K-Nearest Neighbors (KNN) framework for email classification involves several steps. First, the training and test data are preprocessed using techniques like TF-IDF and SMOTE to enhance data quality. The KNN classifier is then initialized with a specified number of neighbors (kk) and the Euclidean distance metric. The classifier is trained on the preprocessed training data and used to predict labels for the test data. Finally, the model's performance is evaluated using metrics such as accuracy, precision, recall, F1-score, and Area Under Curve (AUC), providing a comprehensive assessment of its effectiveness in spam detection.
|
 IEEE/ICACT20250220 Slide.09
[Big Slide]
[YouTube]