 |
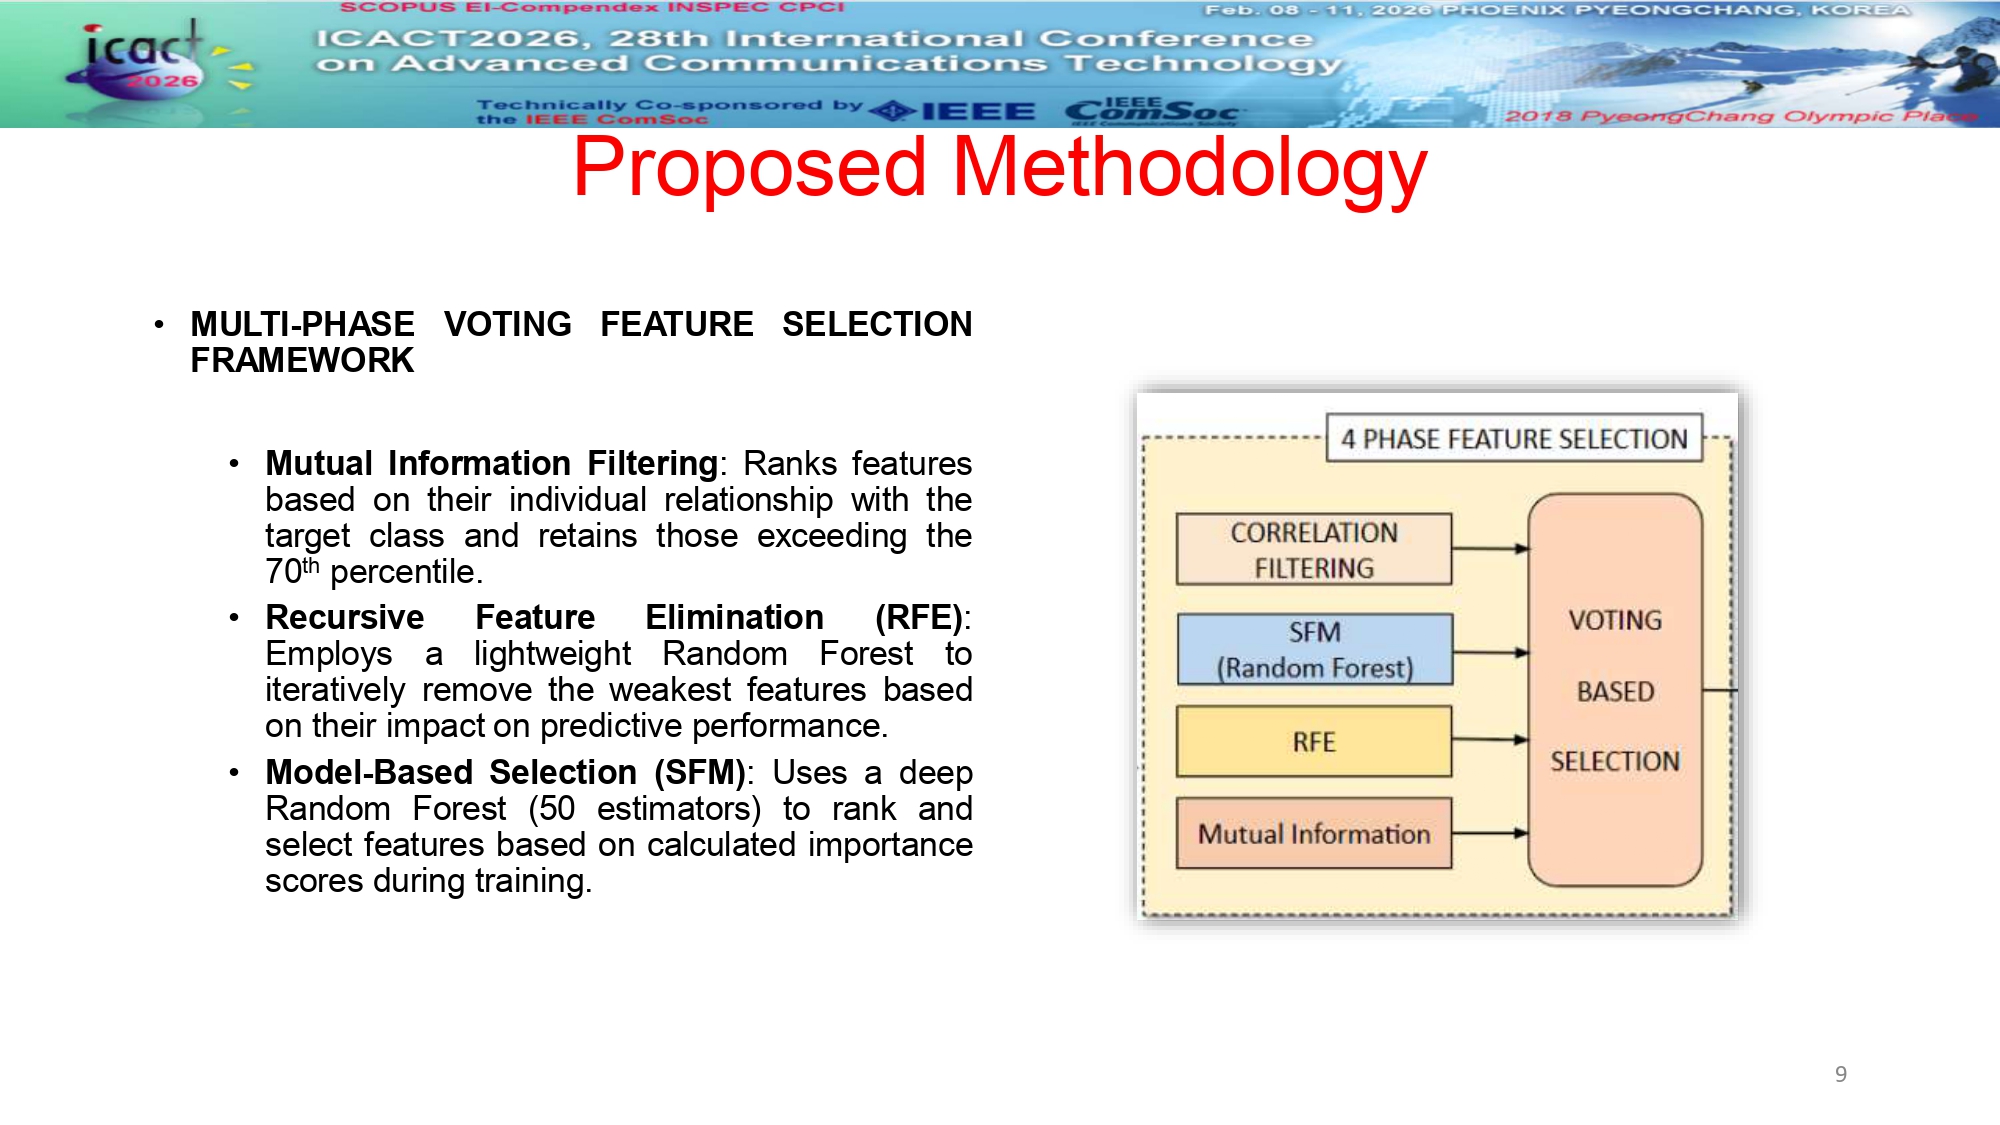
A critical component of our methodology is the Multi-Phase Voting Feature Selection Framework, designed to distill the most discriminative features from noisy URL data. To achieve this, we employ three distinct selection stages:
Mutual Information Filtering: This stage ranks features according to their individual relationship with the target class, retaining only those that exceed the 70th percentile.
Recursive Feature Elimination (RFE): We use a lightweight Random Forest to iteratively strip away the weakest features based on their direct impact on predictive performance.
Model-Based Selection (SFM): Here, a deep Random Forest with 50 estimators is used to rank and select features based on their importance scores calculated during the training process.
As shown in the accompanying diagram, these individual outputs, along with correlation filtering, are fed into a voting-based selection mechanism to ensure our final feature set is both highly relevant and non-redundant. |
 IEEE/ICACT20260103 Slide.09
[Big Slide]
[YouTube]