 IEEE/ICACT20230035 Slide.10
[Big Slide]
[YouTube] Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20230035 Slide.10
[Big Slide]
[YouTube] |
Oral Presentation |
|
|
|
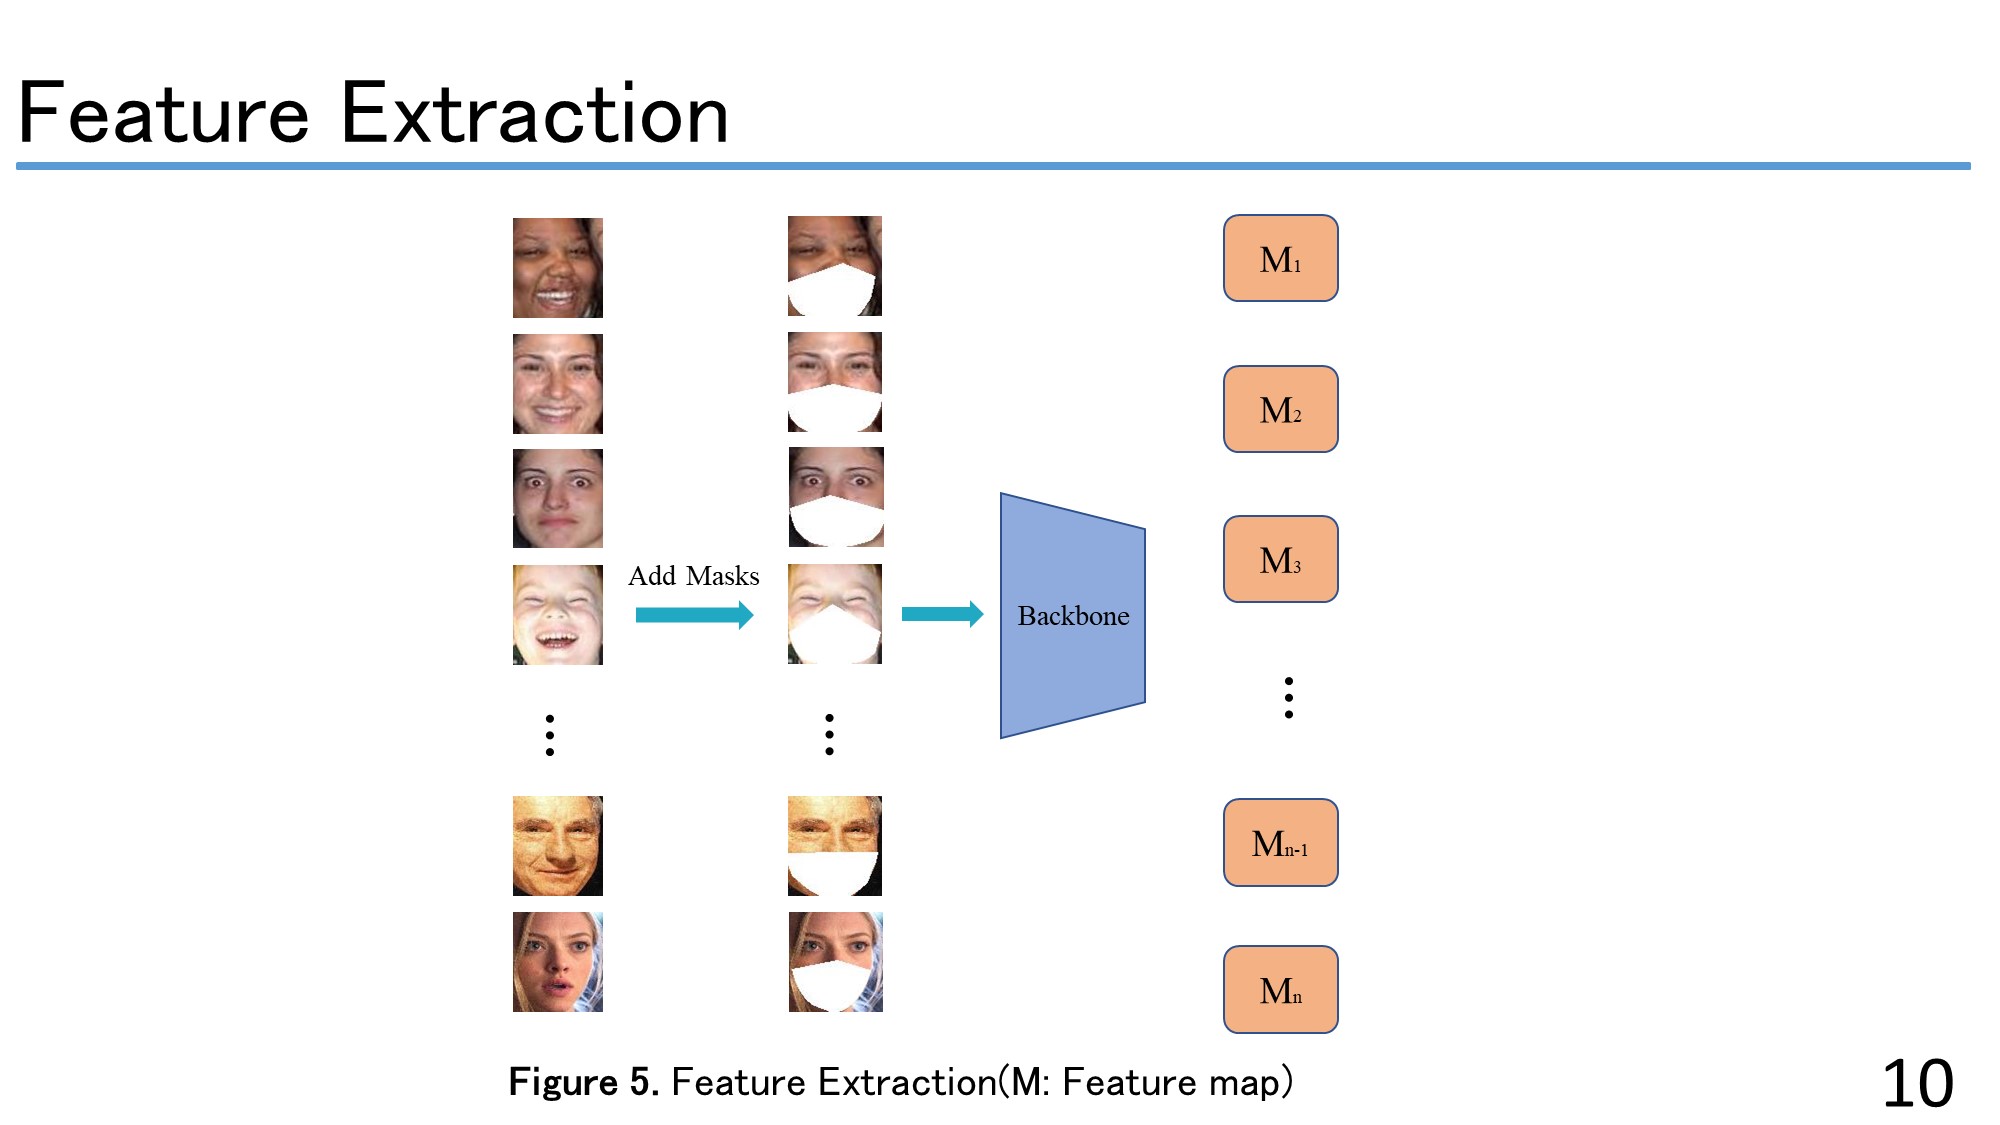
First, a mask is applied to the unmasked face image using the mask-wearing process, as shown in Figure 5. We then use the backbone CNN network to extract the deep features of the masked facial images. The CNN backbone used in this study is ResNet-18. | |
| [Go to Next Slide] |