 |
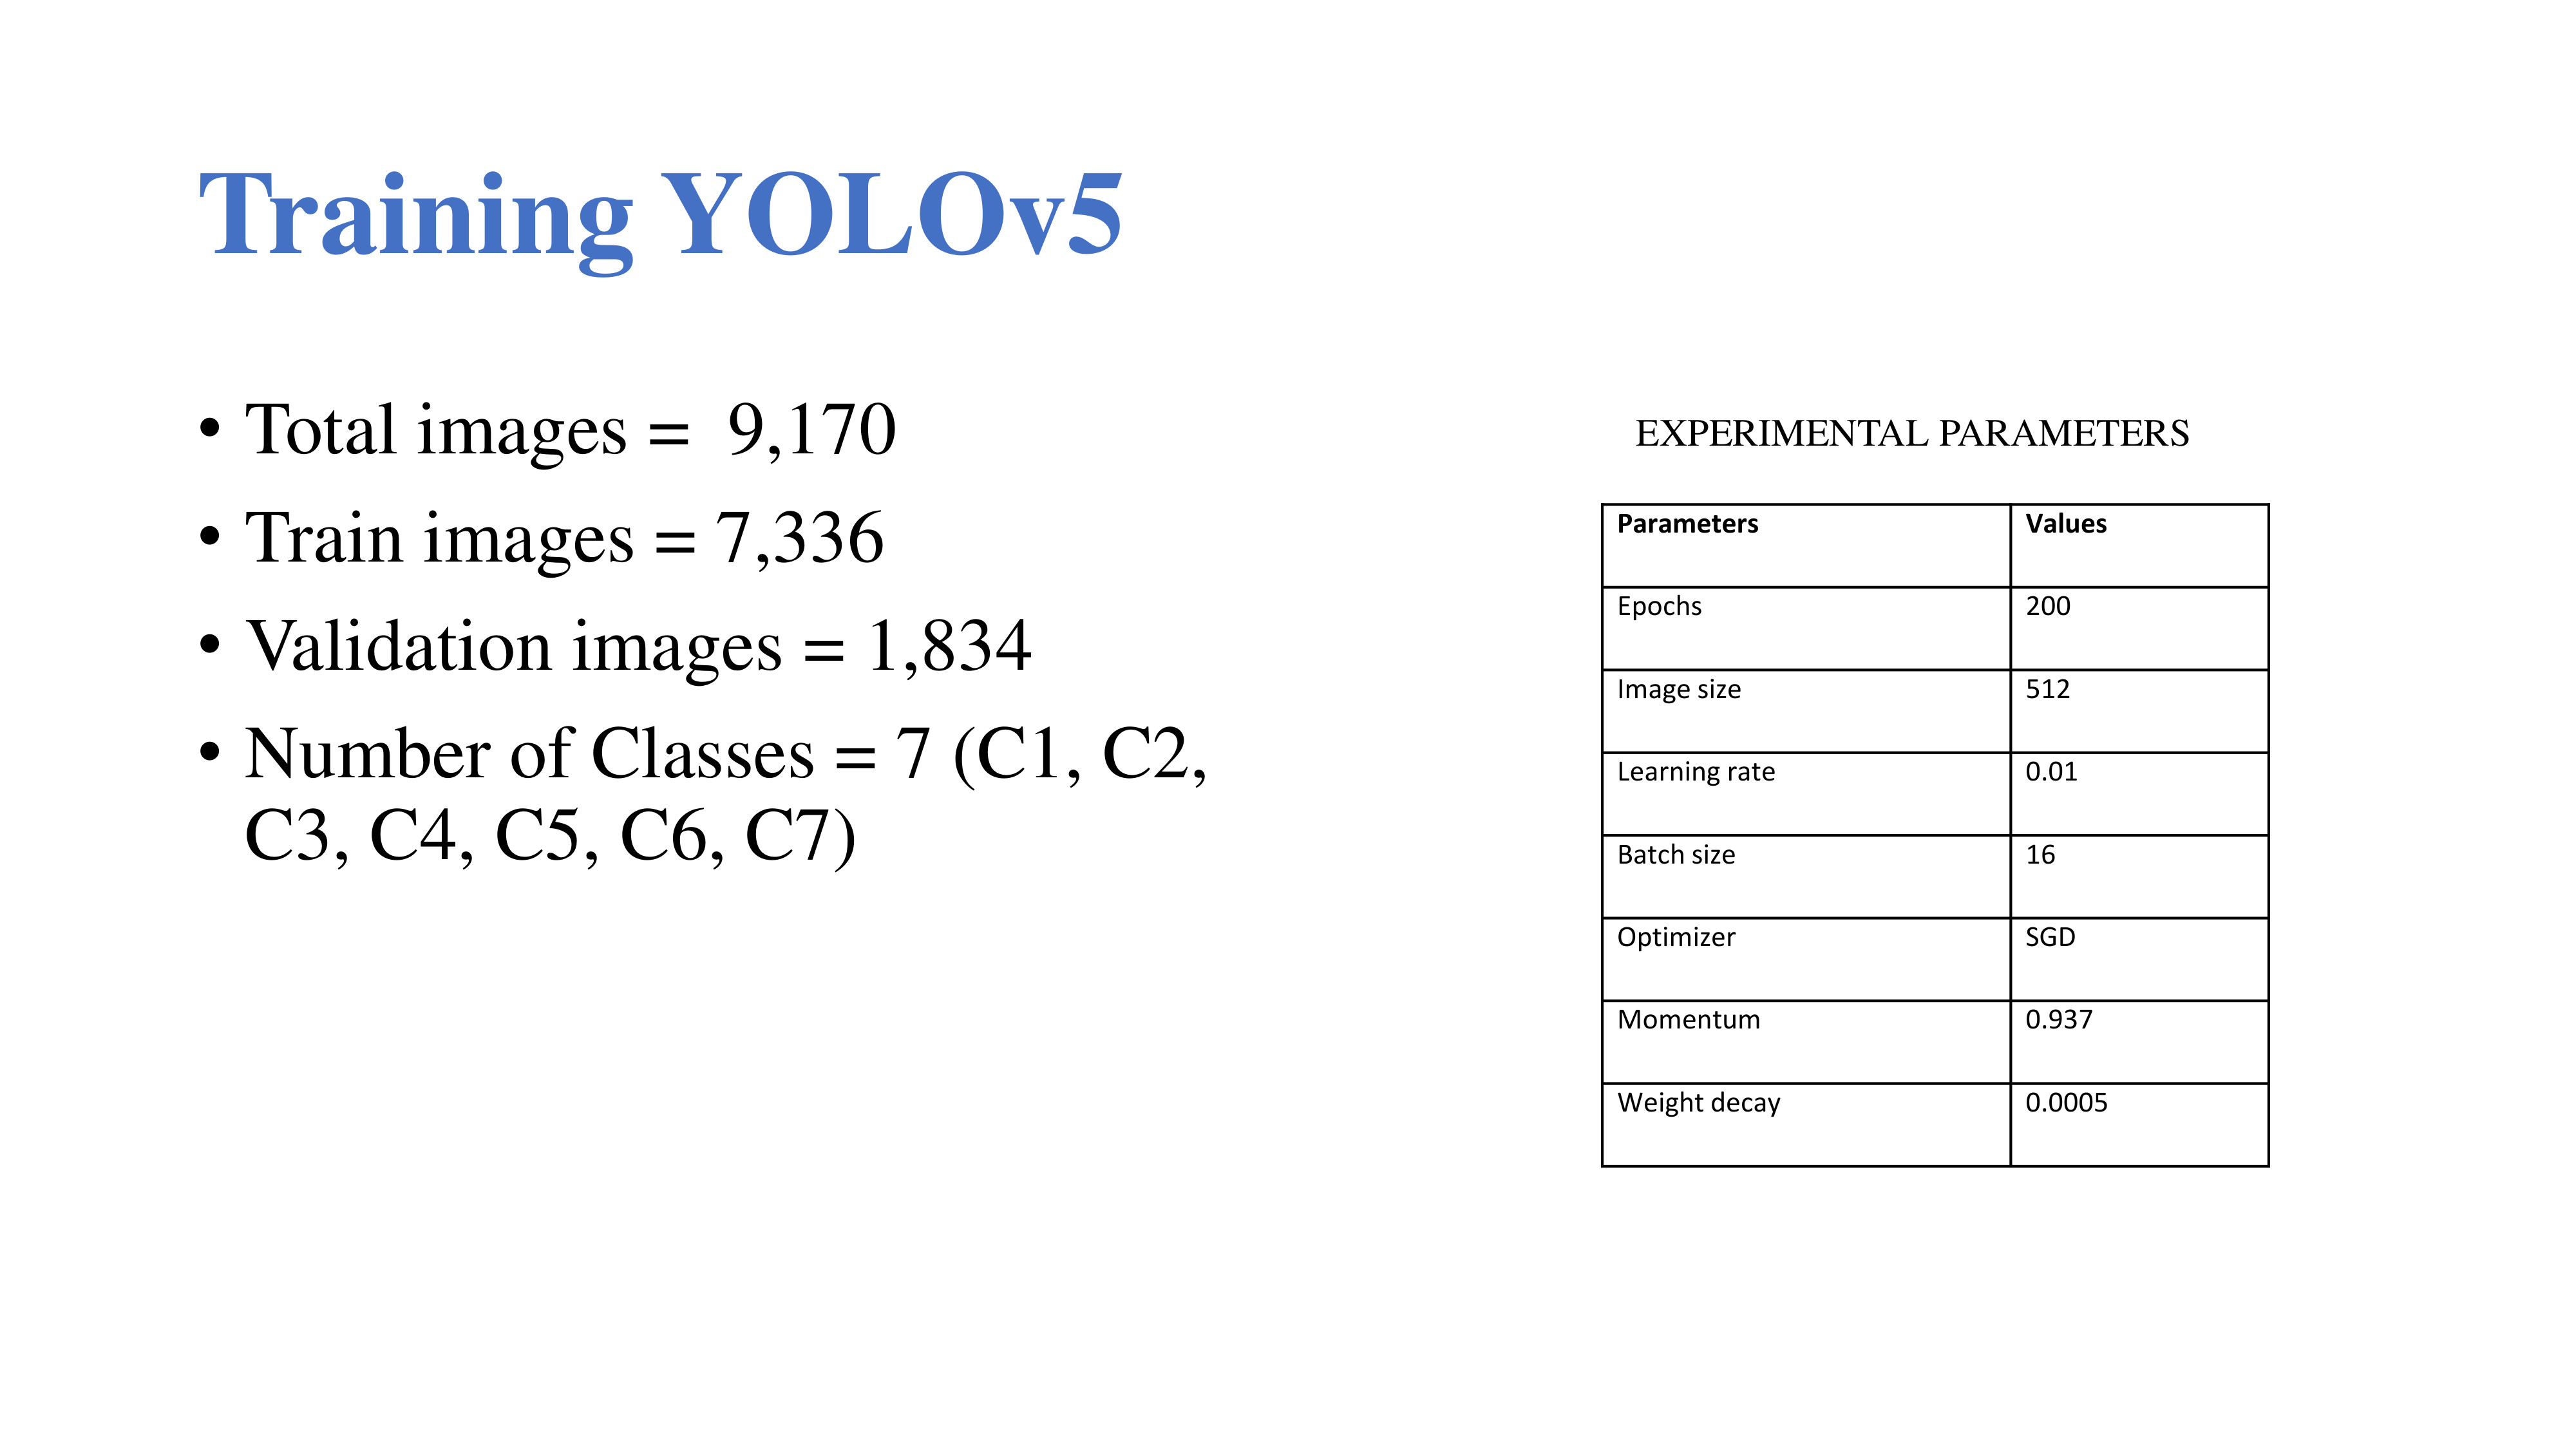
Now, let's dive into the details of our 'Training YOLOv5' phase. Our dataset, comprising a total of 9,170 images, was divided into 7,336 for training and 1,834 for validation. These images represent the anatomical regions corresponding to vertebrae C1 to C7.
For the training process, we set up the following experimental parameters:
Epochs: 200
Image Size: 512
Learning Rate: 0.01
Batch Size: 16
Optimizer: SGD (Stochastic Gradient Descent)
Momentum: 0.937
Weight Decay: 0.0005
These carefully chosen parameters aim to optimize the YOLOv5 model, ensuring effective learning and accurate detection of cervical spine bones. As we progress through the training phase, these settings play a crucial role in fine-tuning the model for our specific application.
|
 IEEE/ICACT20240327 Slide.10
[Big Slide]