 |
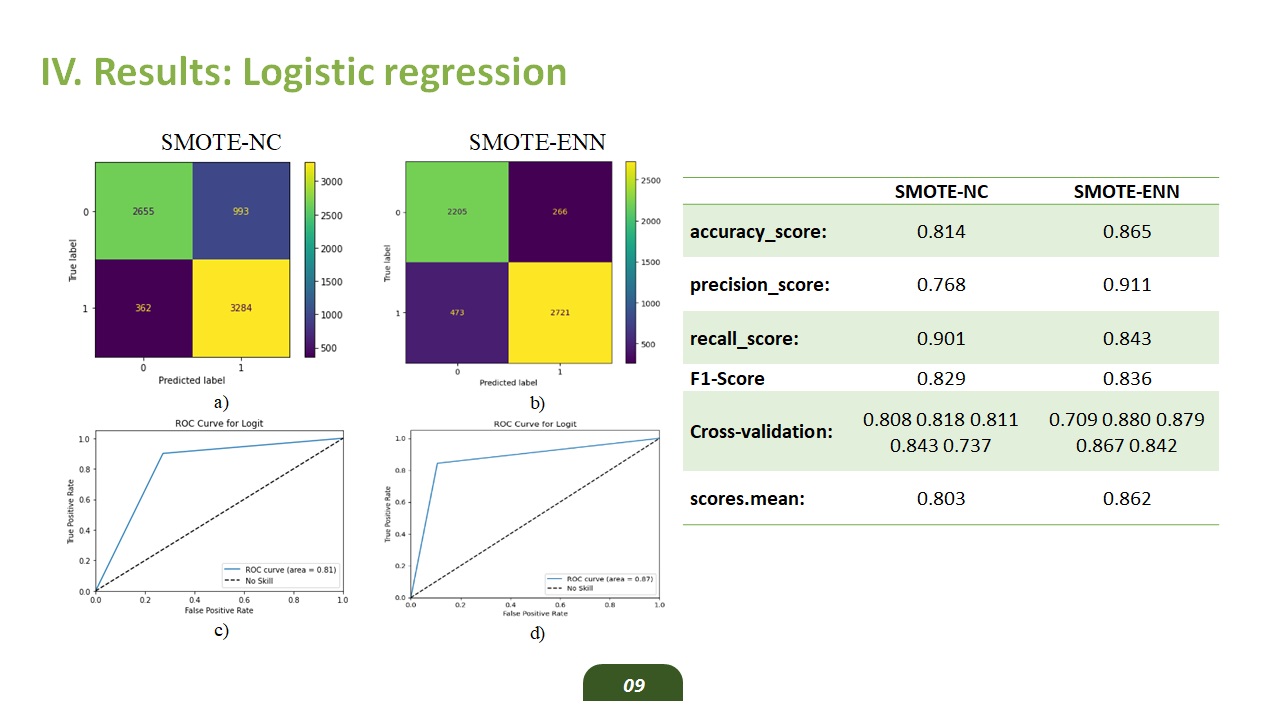
For the SMOTE-NC dataset, the LR model correctly predicts 3 284 positive outcomes and 2 655 negative outcomes. The number of false positives and false negatives is 993 and 362, respectively (Figure (a)). The area under the curve (AUC) is 0.81 (Figure (c)).
On the SMOTE-ENN dataset, the LR model correctly predicts 2 721 positive outcomes and 2 205 negative outcomes. The number of false positives and false negatives is 266 and 473, respectively (Figure (b)). AUC is equal to 0.87 (Figure (d)).
The first column of Table presents the accuracy, precision, recall, and F1-scores of the LR model on the SMOTE-NC dataset. An accuracy score of 0.814, precision score of 0.768, recall score of 0.901, and F1-score of 0.829 indicate that the LR model performs well on the SMOTE-NC dataset.To evaluate potential overfitting, we test the model on five sub-datasets. We divide the entire dataset into five folds. In each iteration, we use one-fold as the test set. We train the model on the remaining data, using each fold once as a test set. This cross-validation method allows us to obtain scores for the entire dataset. The cross-validation scores for the SMOTE-NC dataset vary across folds, ranging from 0.74 to 0.84. This variation signals a potential overfitting issue.
|
 IEEE/ICACT20250136 Slide.10
[Big Slide]