 |
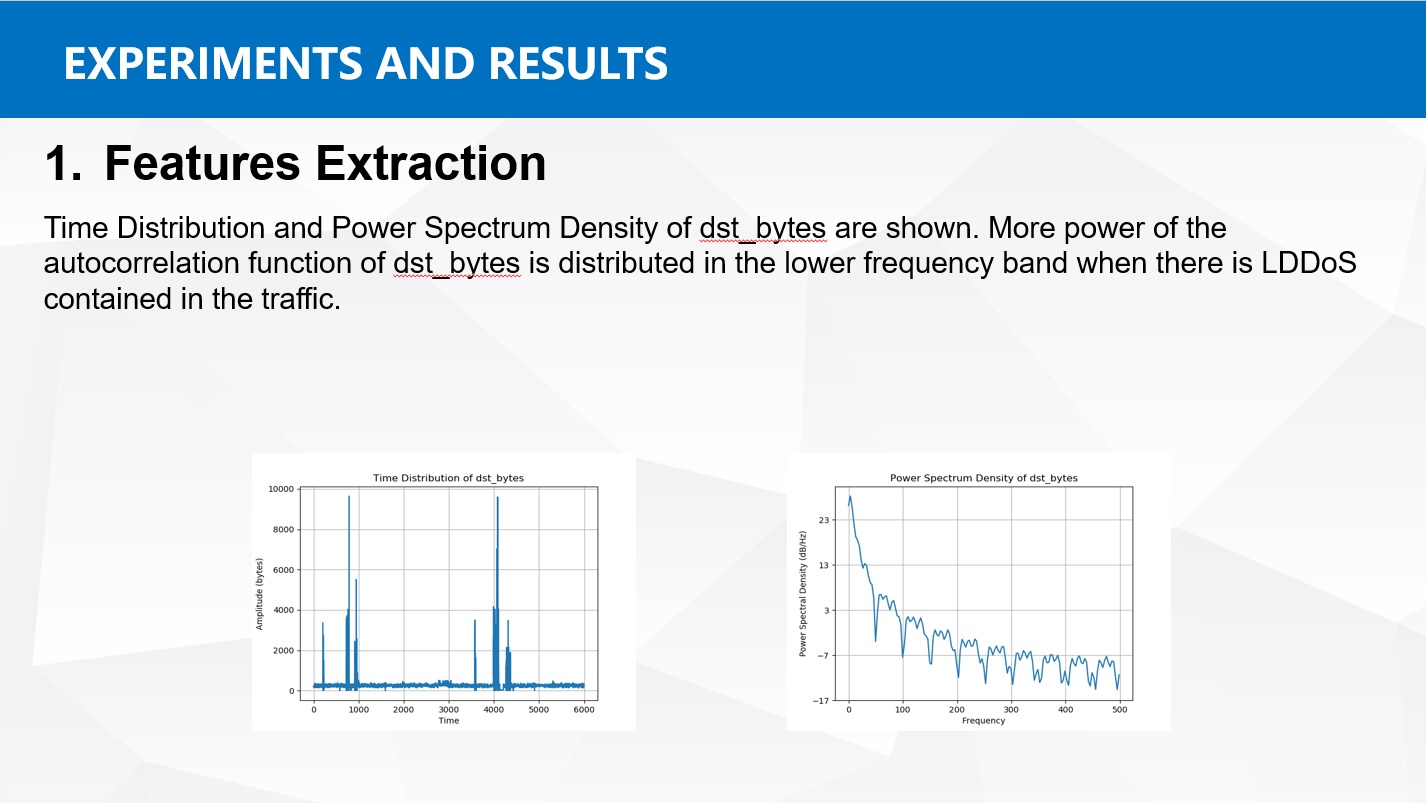
Experiences are done with KDD CUP-99 dataset. In the dataset, each of samples has 41 features. 38 features of them are character and number related features. Thus, we pre-process them by reflecting and normalization. And then, we generate PSD by FFT and add them as new dimensions. In the following two pictures, the time domain features and NCAS value of dst_bytes are shown. After above operations, dimensions of features are bumped to 110. In order to avoid the influence of the dimension of feature attribute on the experiment, it is necessary to unify the dimension of the experimental data. Thus, we normalize the feature attributes between 0 and 1. After above necessary dimensionality expand and normalize. The entropies of them are calculated for feature extraction. We well tune the threshold to 50, whose entropy values are bigger than 0.1, and chose them as training features. |
 IEEE/ICACT20210143 Slide.11
[Big Slide]