 |
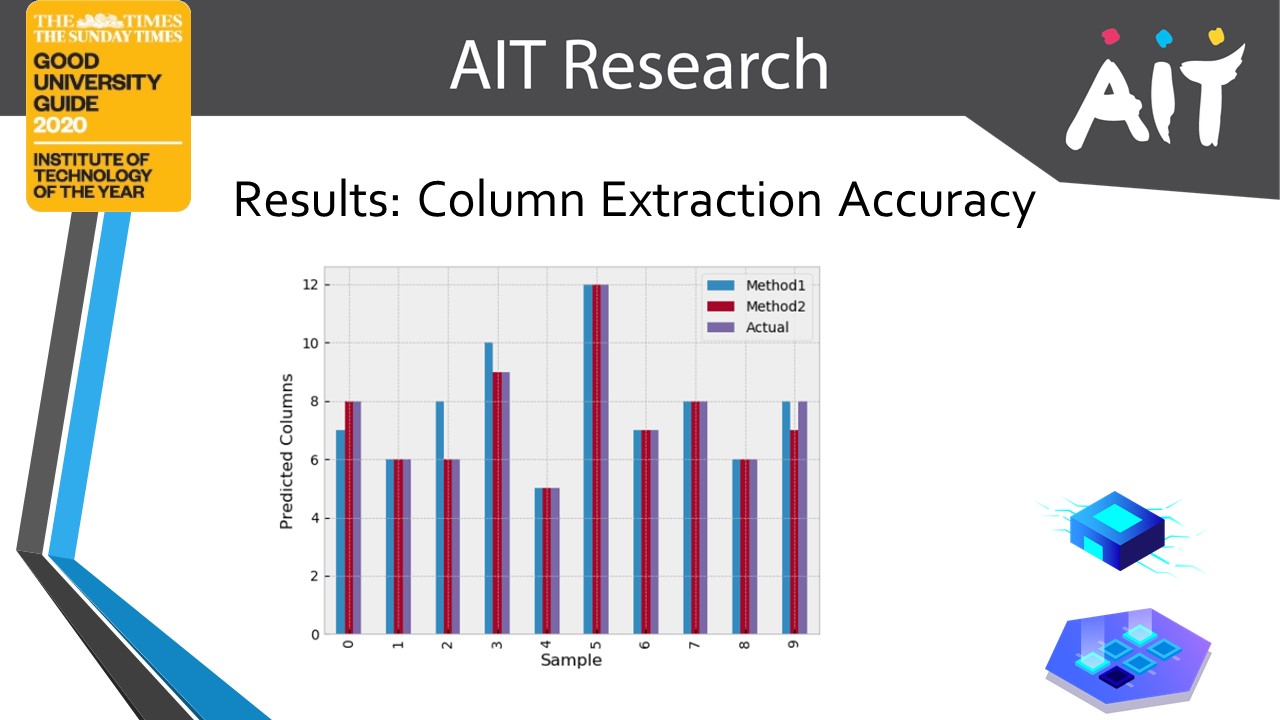
We used 10 data samples with the highest column structure variation to calculate the column component extraction accuracy of both methods. As seen in the figure, the predicted and actual columns by both methods are plotted. The results suggest that both the approaches worked well for column component extraction; however, the classification of columns as topics provided better predictions than finding similarity of lines and calculating the mean score of whitespace distributions. Thus, method 1 has more accuracy in eliminating extraneous information and detecting relevant rows and headers, while method 2 has better accuracy in extracting column components.
|
 IEEE/ICACT20210237 Slide.11
[Big Slide]
[YouTube]