 |
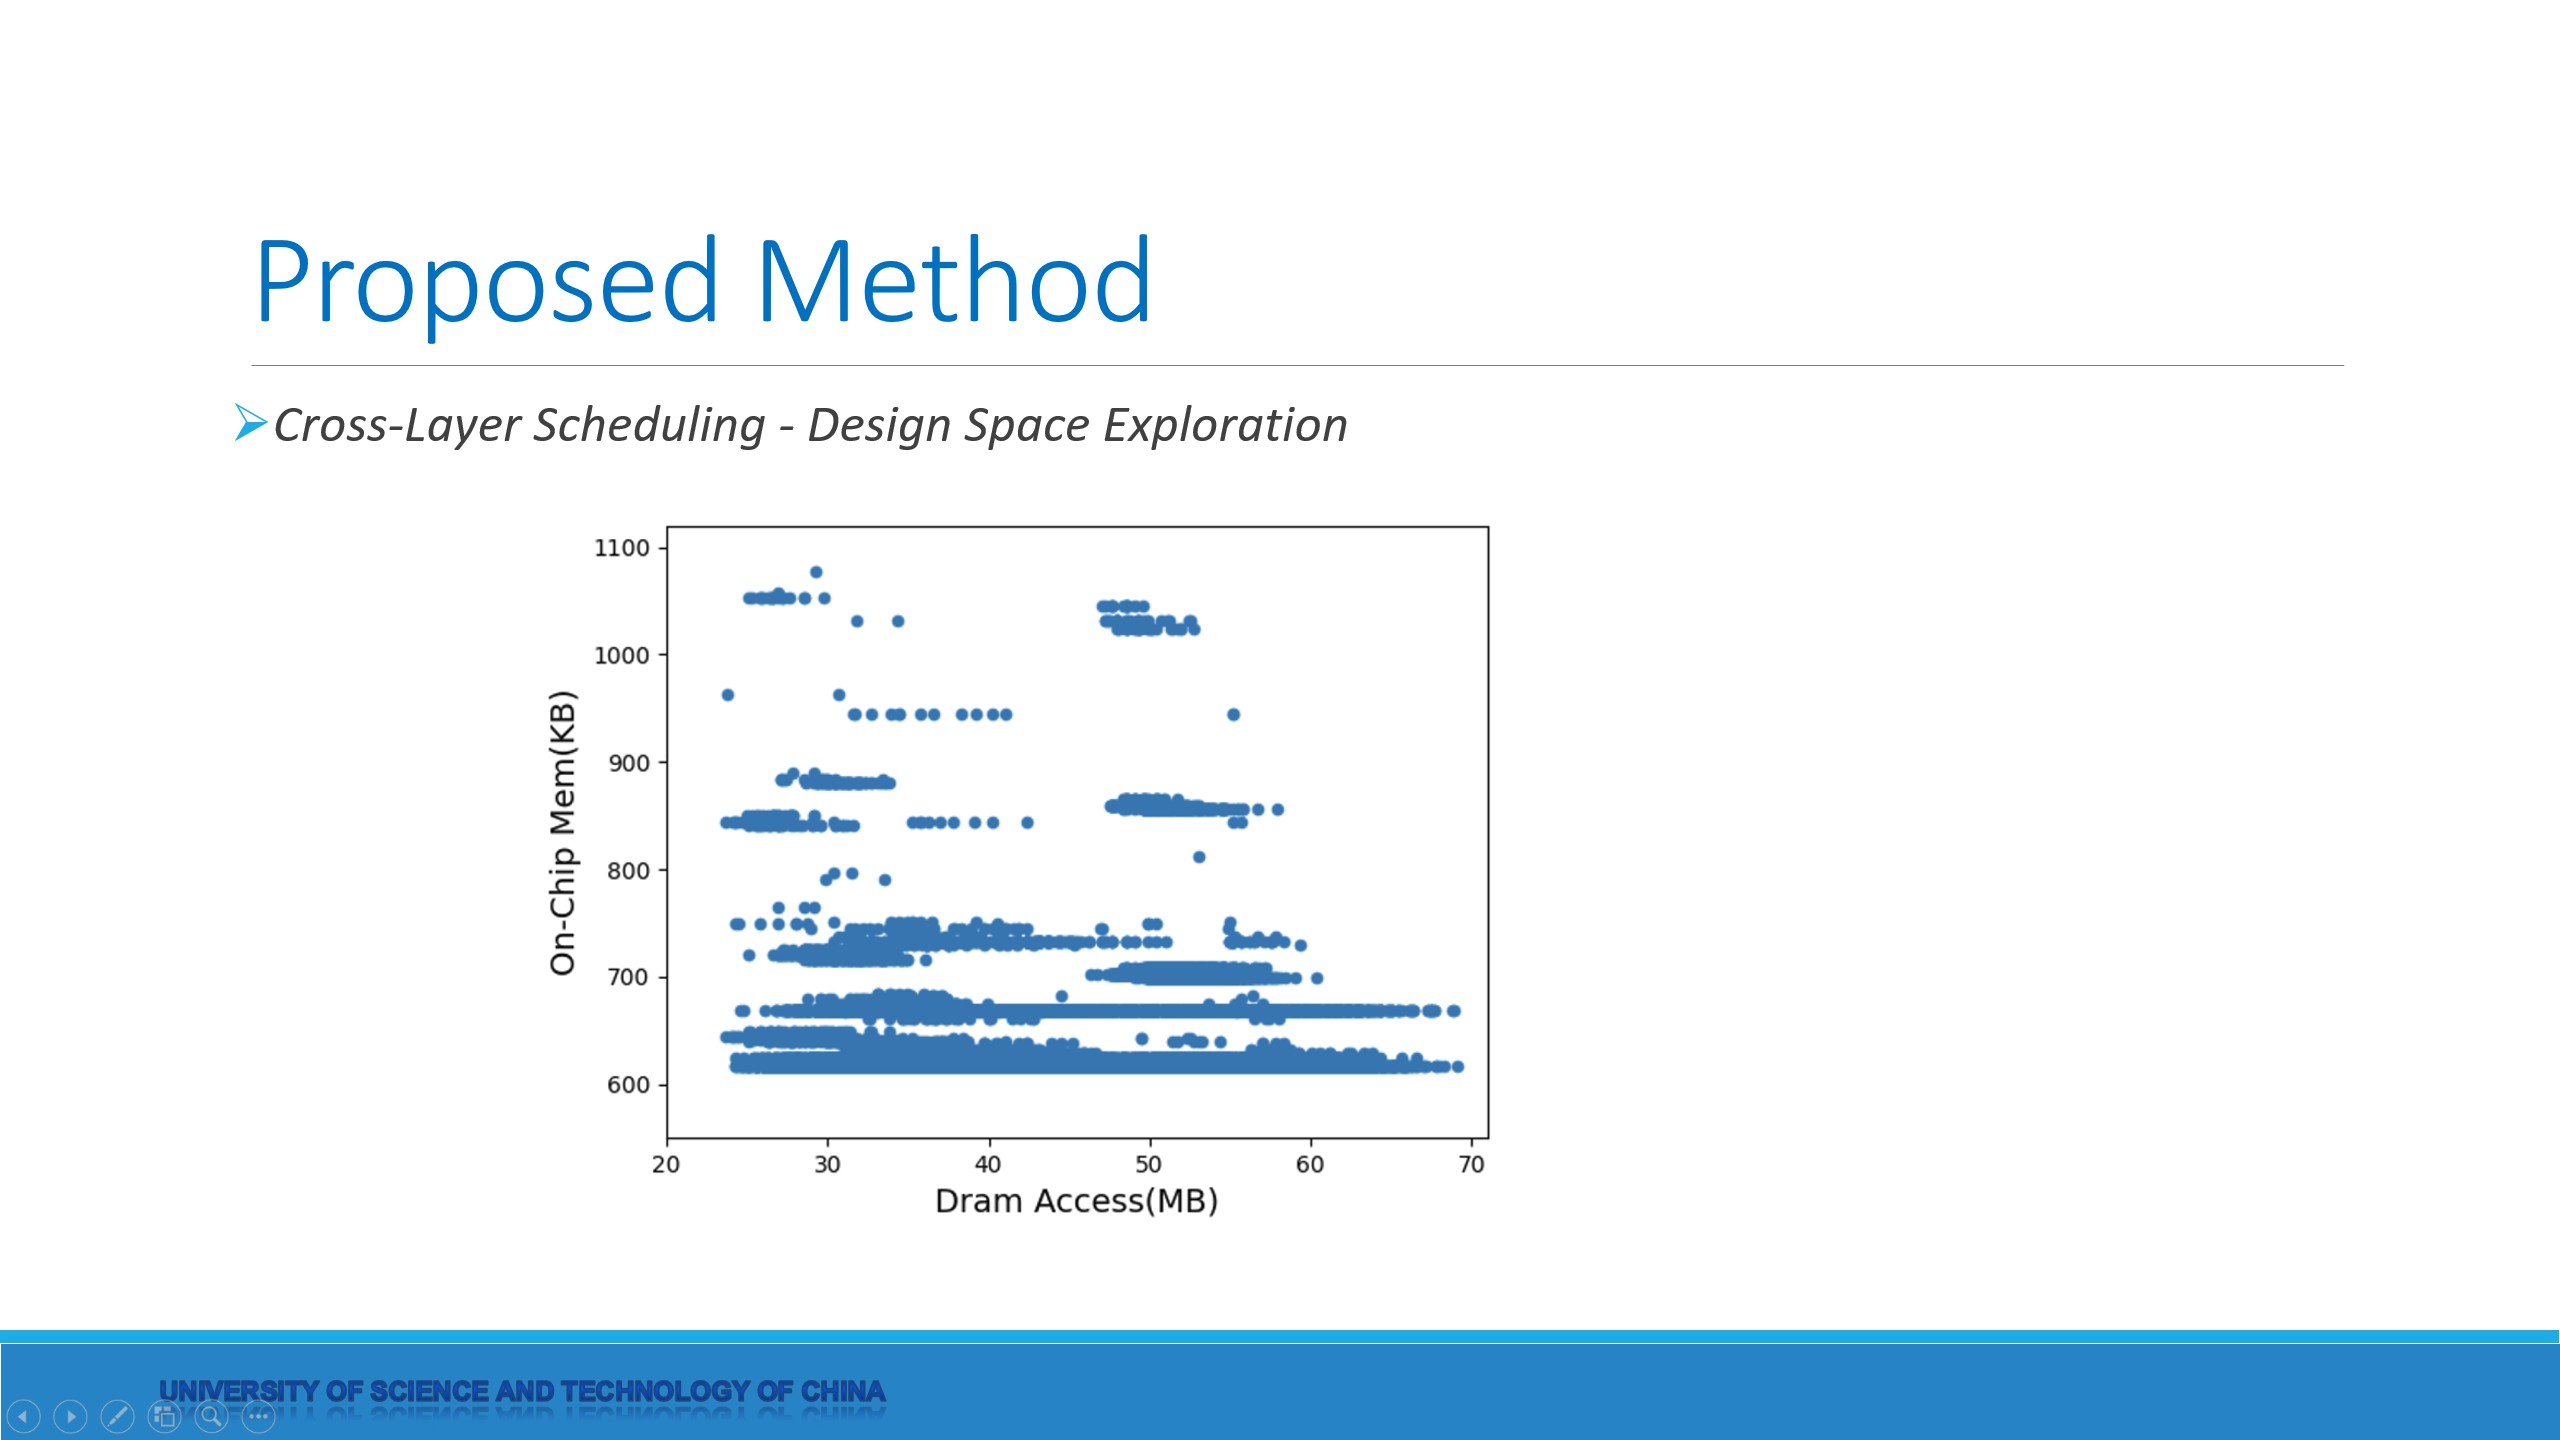
In the collection, the size of on-chip memory and the DRAM access is different, depending on the structure of these models. A scatter plot can be drawn, as shown in figure. Among them, the relatively good implementation in both indicators is selected as the final fusion model.
During the inference, the activation ratio of each layer may fluctuate, which affects the performance of the cross-layer scheduling. So we design a fine-tuning module in the accelerator. The fusion strategy is fine-tuned based on the actual activation ratio computed at runtime. The fine-tuning algorithm limits the search space and only fine-tunes 2 layers at most, so the computational overhead is minimal. The arbiter can judge the fine-tuned model, and select the fusion model with the best performance to replace the previous model.
|
 IEEE/ICACT20230038 Slide.11
[Big Slide]
[YouTube]