 IEEE/ICACT20230153 Slide.11
[Big Slide]
Oral Presentation
| Virual Oral Presentation Slide by Slide |
|
IEEE/ICACT20230153 Slide.11
[Big Slide]
| Oral Presentation |
|
|
|
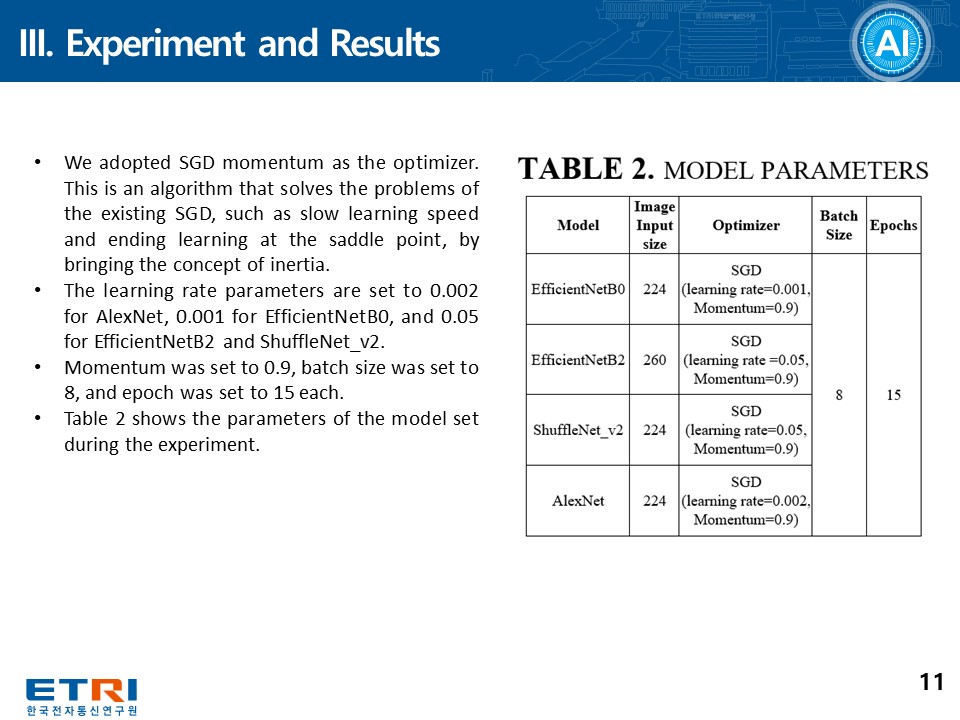
We adopted SGD momentum as the optimizer. This is an algorithm that solves the problems of the existing SGD, such as slow learning speed and ending learning at the saddle point, by bringing the concept of inertia. The learning rate parameters are set to 0.002 for AlexNet, 0.001 for EfficientNetB0, and 0.05 for EfficientNetB2 and ShuffleNet_v2. Momentum was set to 0.9, batch size was set to 8, and epoch was set to 15 each. Table 2 shows the parameters of the model set during the experiment. | |
| [Go to Next Slide] |