 |
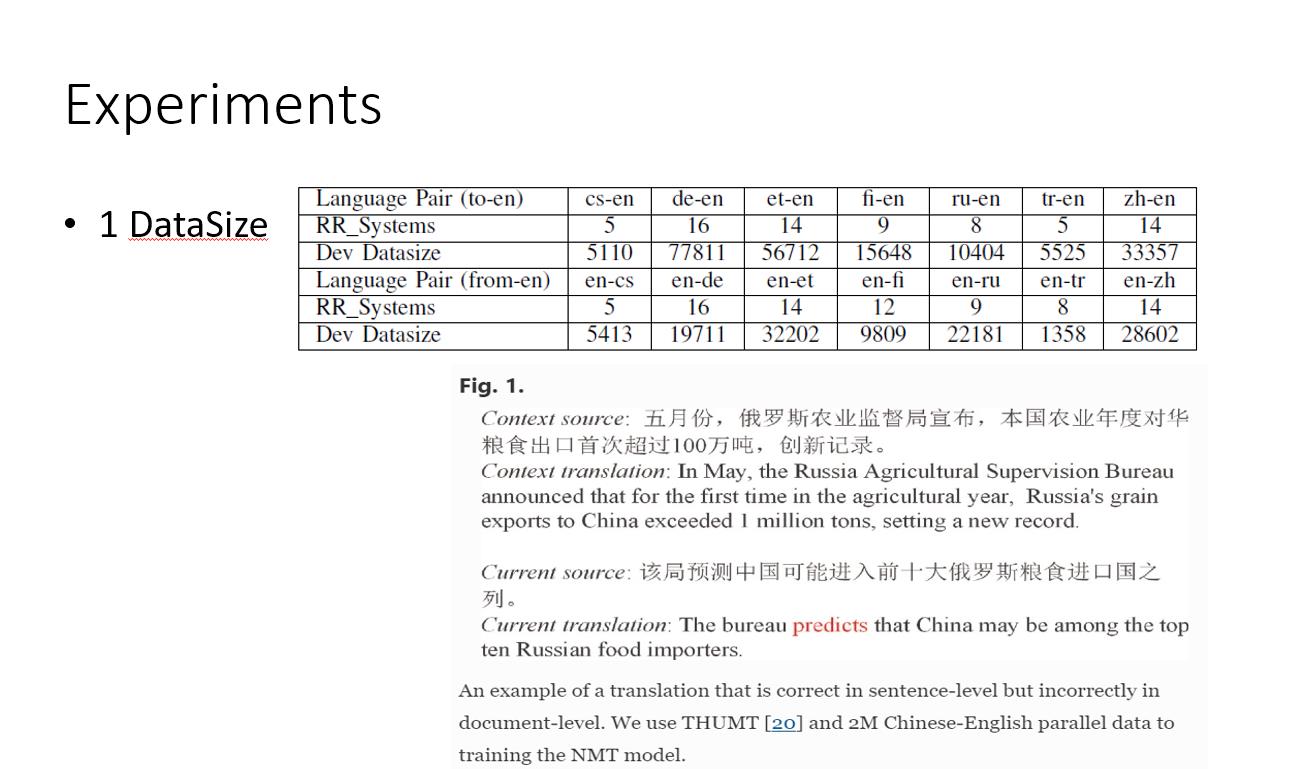
We utilize the WMT18 news translation dataset as our evaluation benchmark, consisting of 3,000 source sentences translated into 14 language pairs like DE-EN, FI-EN and ZH-EN. The dataset contains translations from all participating WMT18 teams, with DE-EN comprising the most sentence pairs (77,811) and CS-EN the least (5,110).
Importantly, the translated sentences were manually evaluated by professional multilingual human experts through pairwise comparisons. These human quality judgements serve as the gold labels to assess machine translation quality estimation performance.
In total across 14 language directions, the rich diversity of translations from dozens of WMT18 systems paired with meticulous expert quality ratings creates a robust, real-world dataset to thoroughly benchmark our proposed quality estimation methods against past leading approaches. The scale and quality of the data facilitates in-depth analyses into the strengths, weaknesses and differences of various strategies. |
 IEEE/ICACT20240321 Slide.11
[Big Slide]