 |
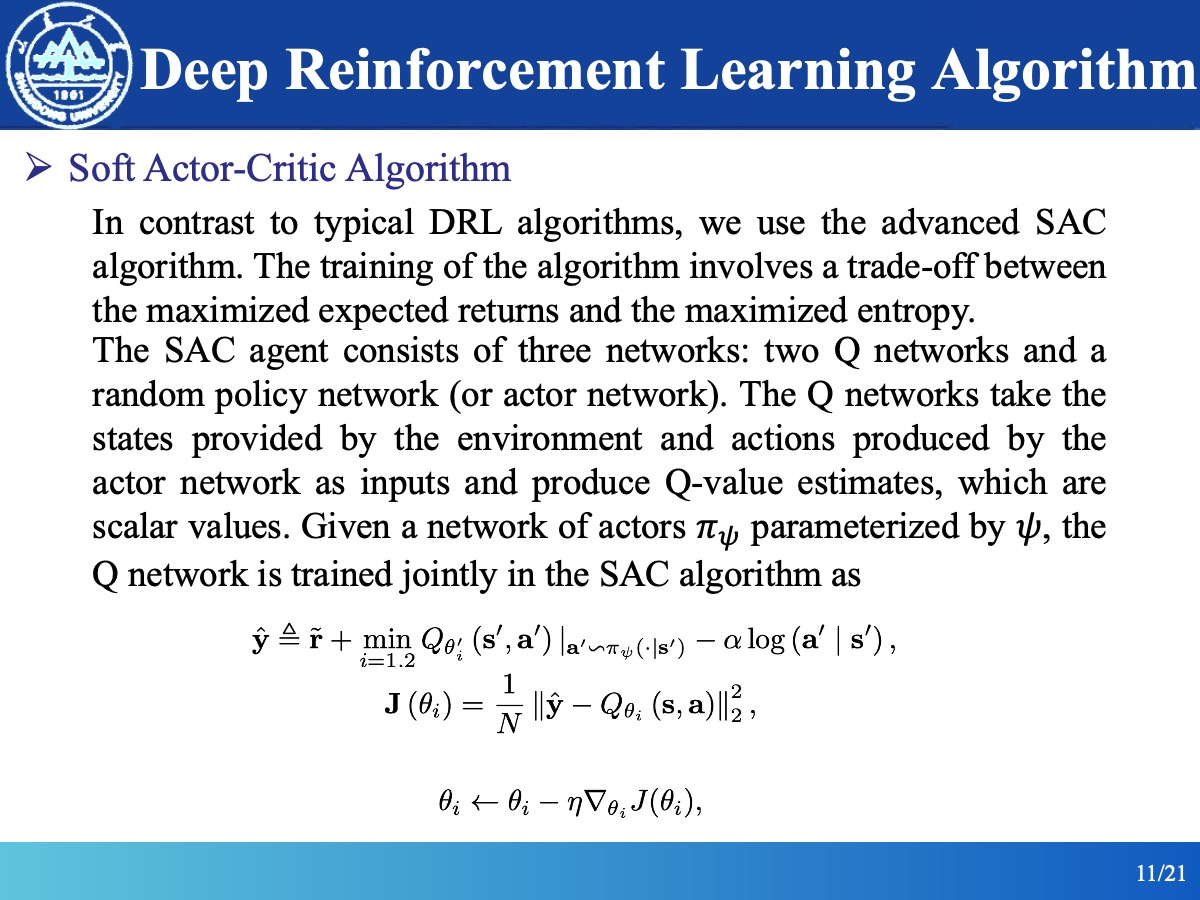
In contrast to typical DRL algorithms, we use the advanced SAC algorithm. The training of the algorithm involves a trade-off between the maximized expected returns and the maximized entropy. The SAC agent consists of three networks: two Q networks and a random policy network (or actor network). The Q networks take the states provided by the environment and actions produced by the actor network as inputs and produce Q-value estimates, which are scalar values. Given a network of actors 𝜋_𝜓 parameterized by 𝜓, the Q network is trained jointly in the SAC algorithm as the formula.
|
 IEEE/ICACT20240375 Slide.11
[Big Slide]
[YouTube]