 |
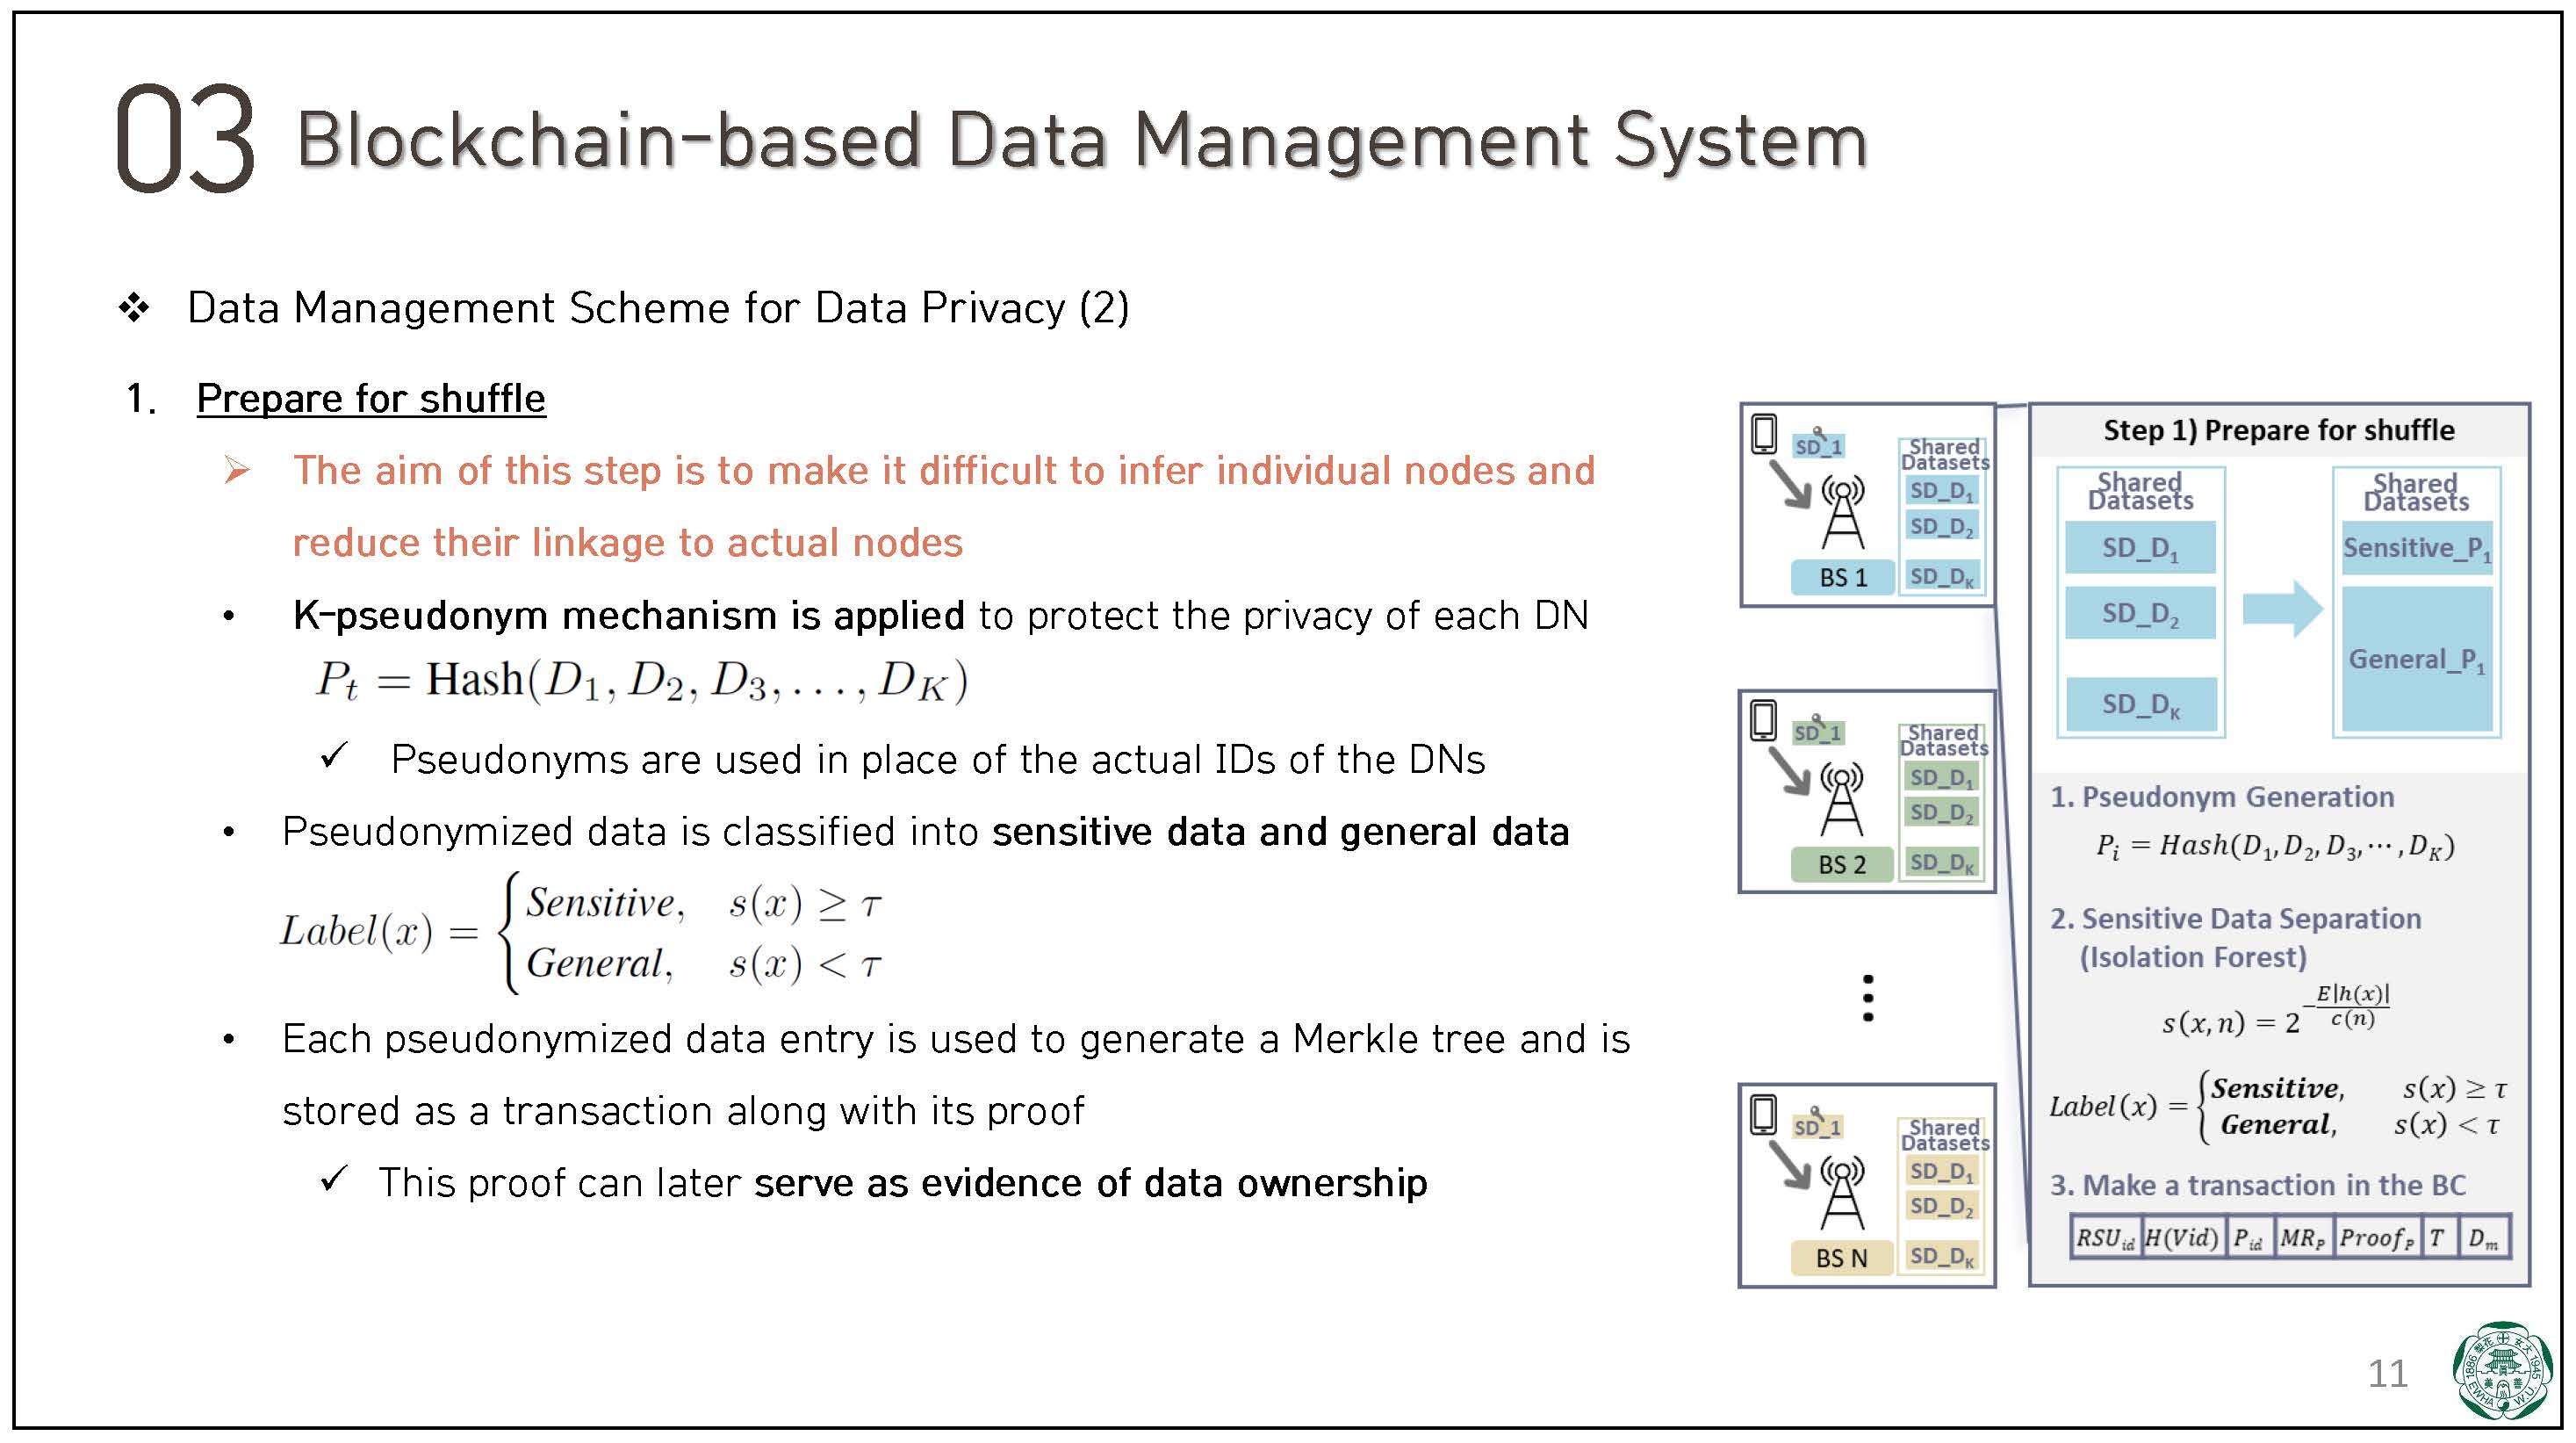
First, this is prepare for shuffle step.
The aim of this step is to make it difficult to infer individual nodes and reduce their linkage to actual nodes.
A K-pseudonym mechanism is applied to protect the privacy of each device node.
Pseudonyms are used in place of the actual IDs of the device nodes.
Then, Pseudonymized data is classified into sensitive data and general data.
Each pseudonymized data entry is used to generate a Merkle tree and is stored as a transaction along with its proof.
This proof can later serve as evidence of data ownership. |
 IEEE/ICACT20260202 Slide.11
[Big Slide]