 |
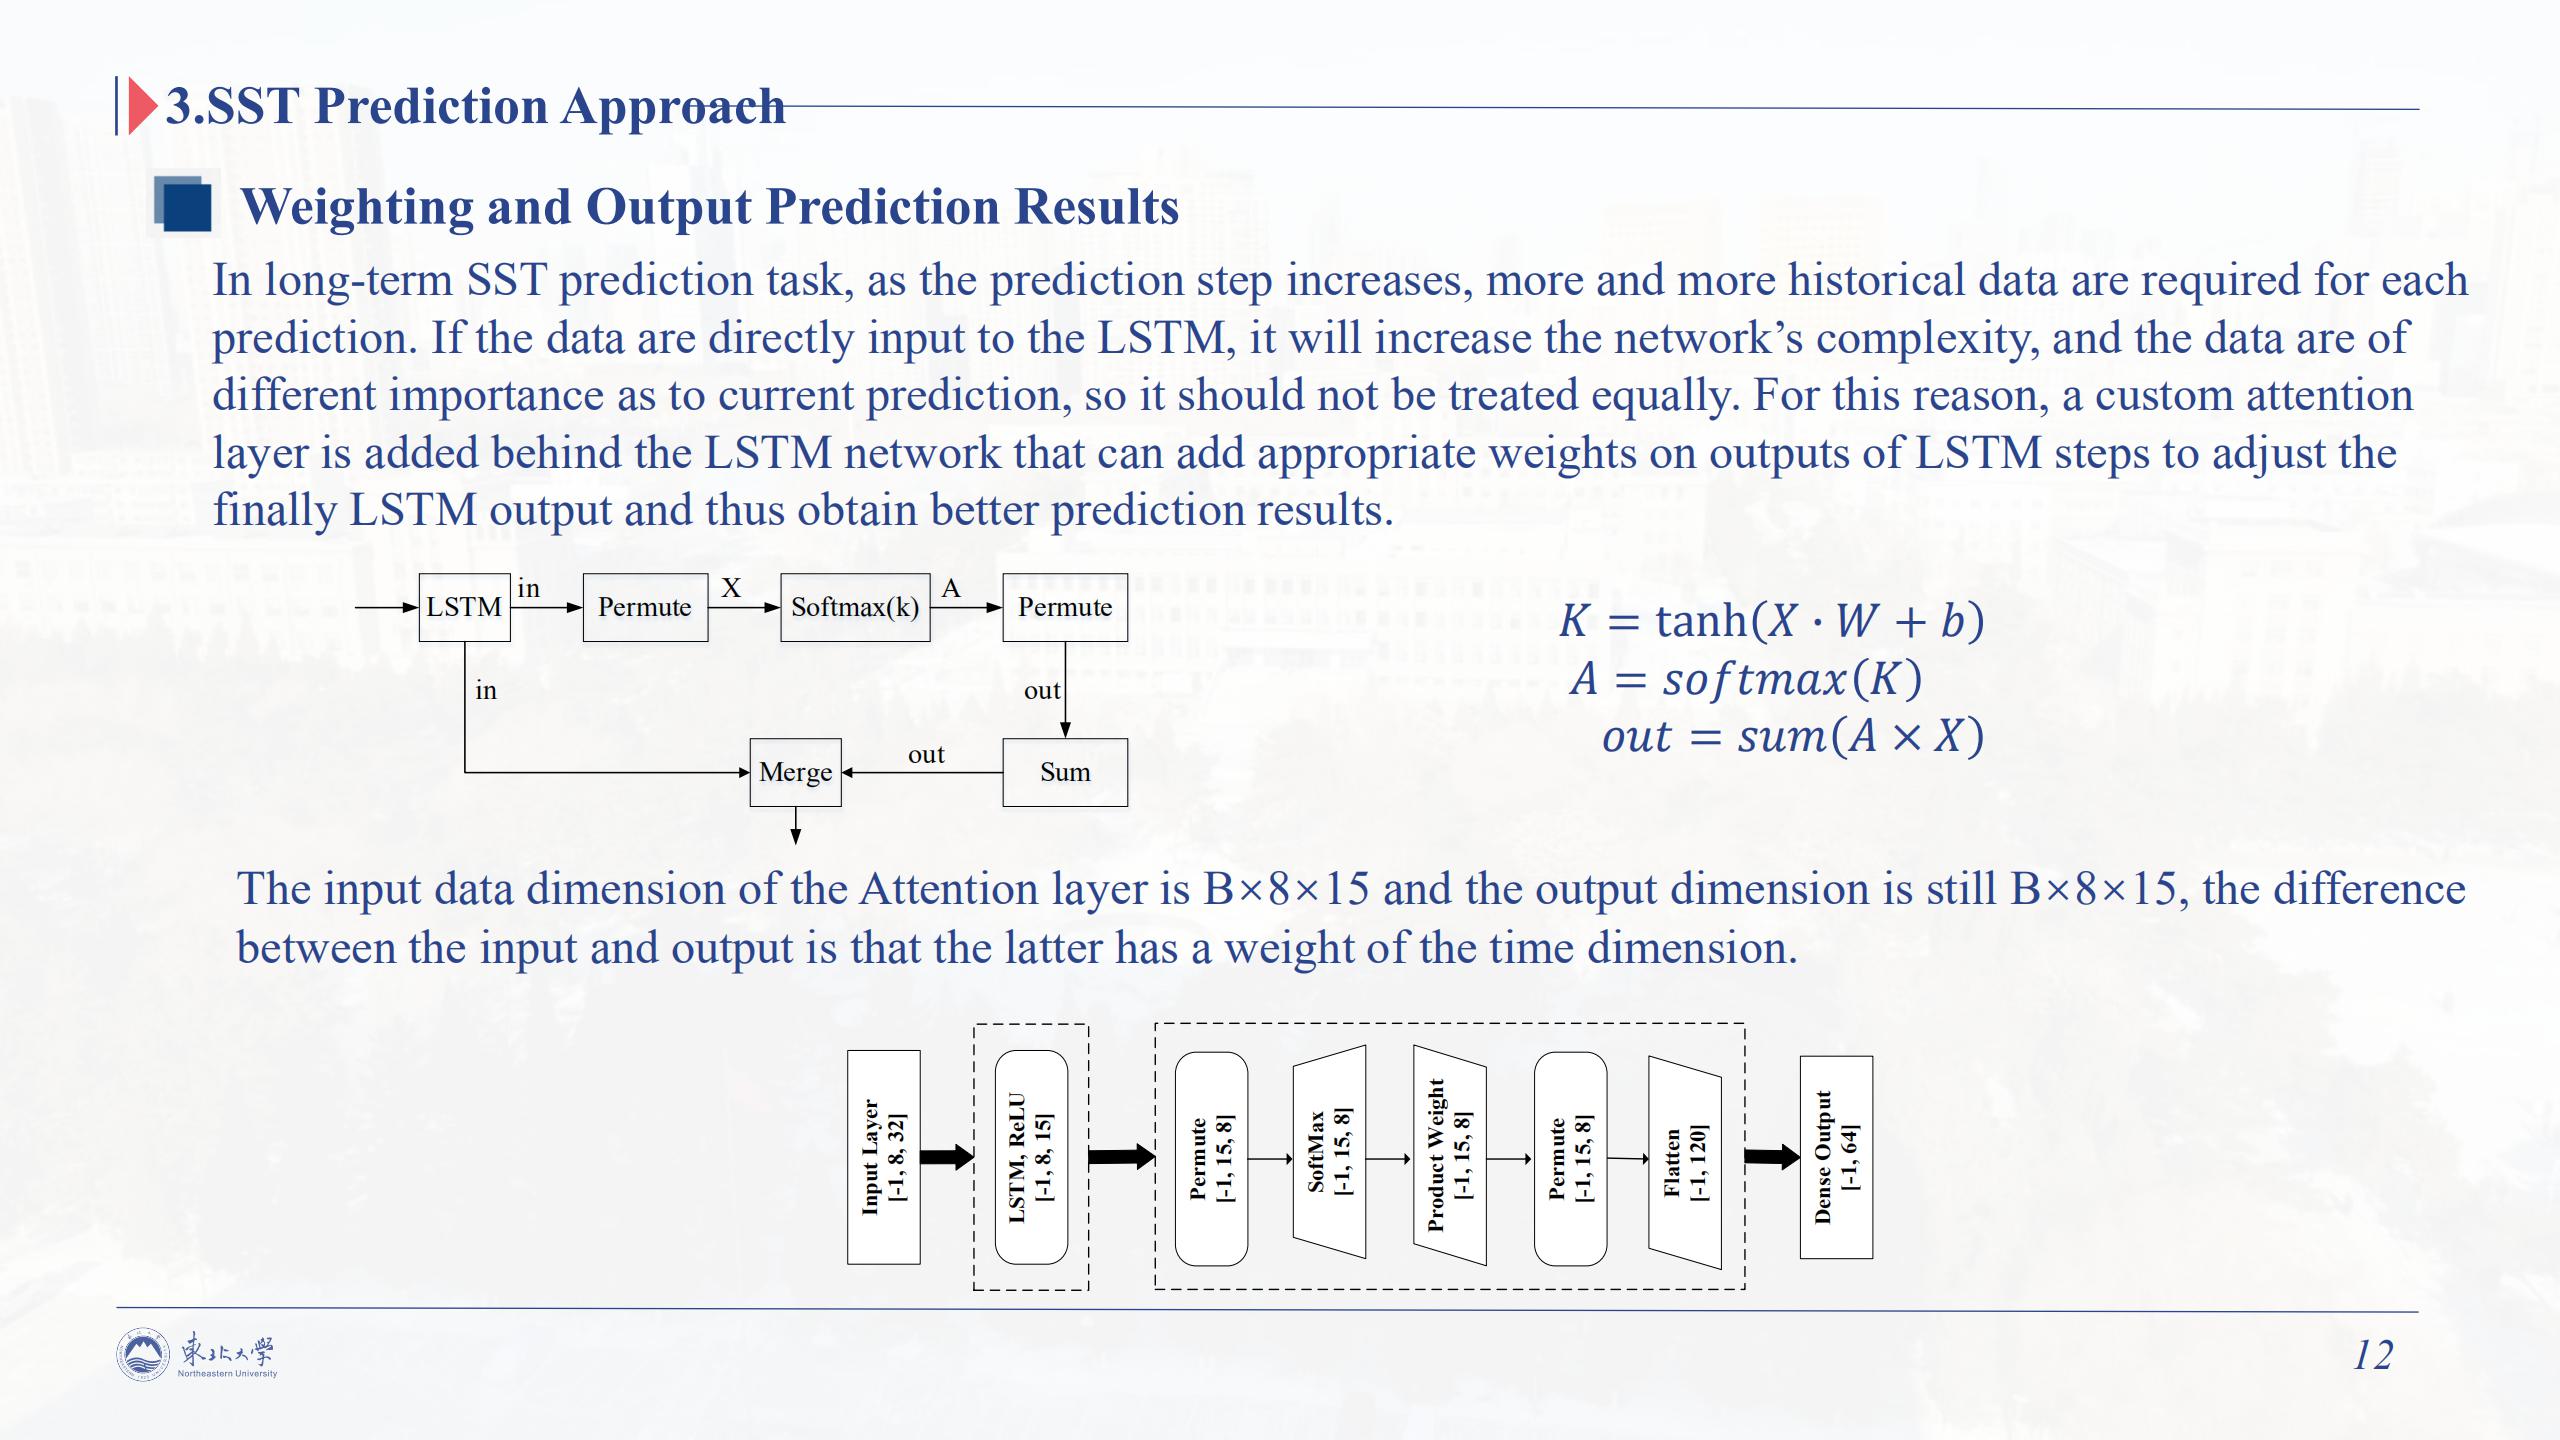
In long-term SST prediction task, as the prediction step increases, more and more historical data are required for each prediction. If the data are directly input to the LSTM, it will increase the network¡¯s complexity, and the data are of different importance as to current prediction, so it should not be treated equally . For this reason, a custom attention layer is added behind the LSTM network that can add appropriate In long-term SST prediction task, as the prediction step increases, more and more historical data are required for each prediction. If the data are directly input to the LSTM, it will increase the network¡¯s complexity, and the data are of different importance as to current prediction, so it should not be treated equally . For this reason, a custom attention layer is added behind the LSTM network that can add appropriate weights on outputs of LSTM steps to adjust the finally LSTM output and thus obtain better prediction results. A custom attention layers is shown above. The input data dimension of the Attention layer is B¡¿8¡¿15 and the output dimension is still B¡¿8¡¿15, the difference between the input and output is that the latter has a weight of the time dimension. A fully connected layer is then used to obtain the final prediction results. the layering of the LSTM and Attention layers is shown below.
|
 IEEE/ICACT20210141 Slide.12
[Big Slide]